Maintainer runbook: the onboarding atlas, seven parts, one page.
Engineering history, long. This is the record kept for the people who run
the data pipeline: dated incident notes, fixes and open gaps, about four hours of reading.
Its figures are snapshots with their dates, not current counts. To use the platform, start
with How to use the platform.
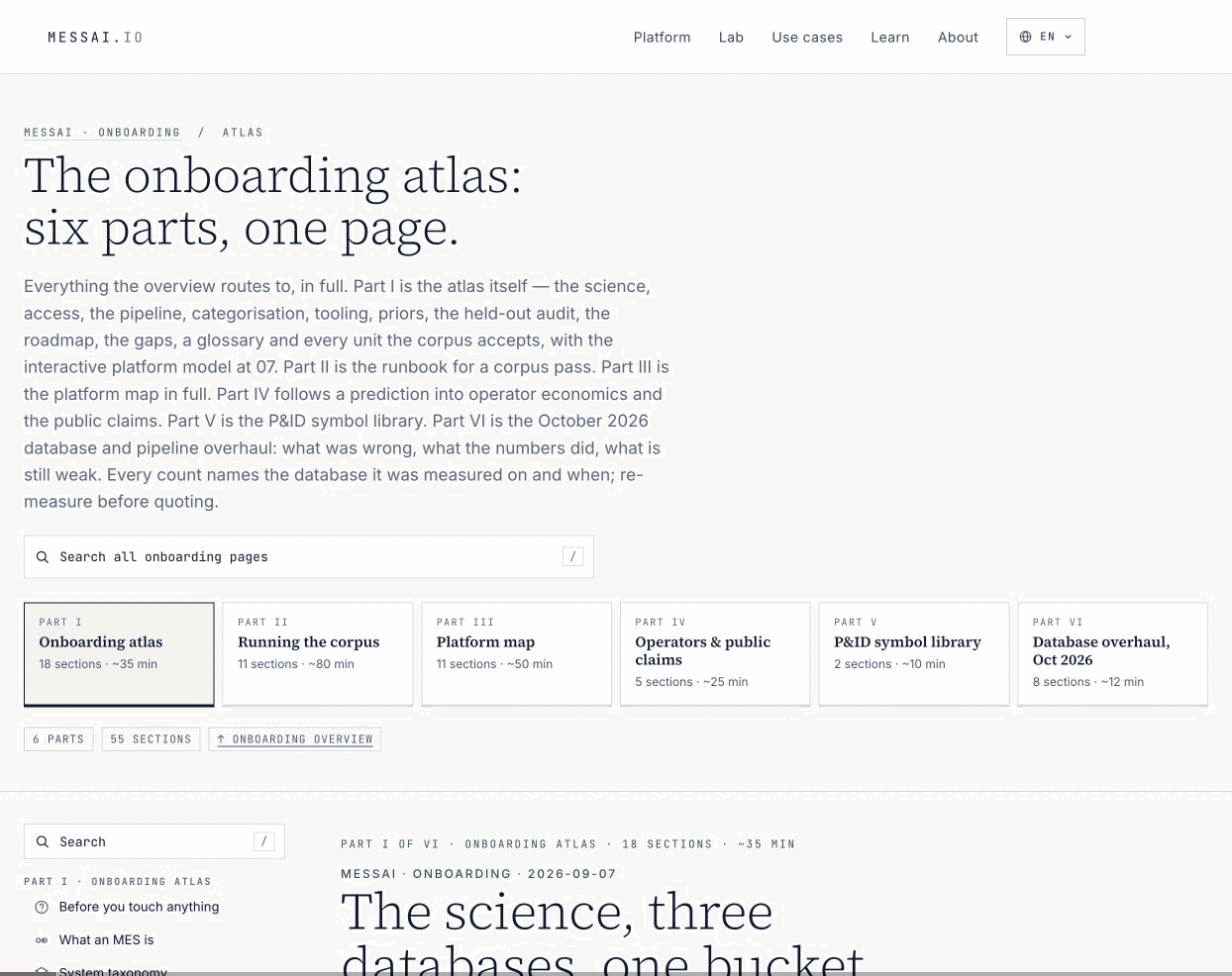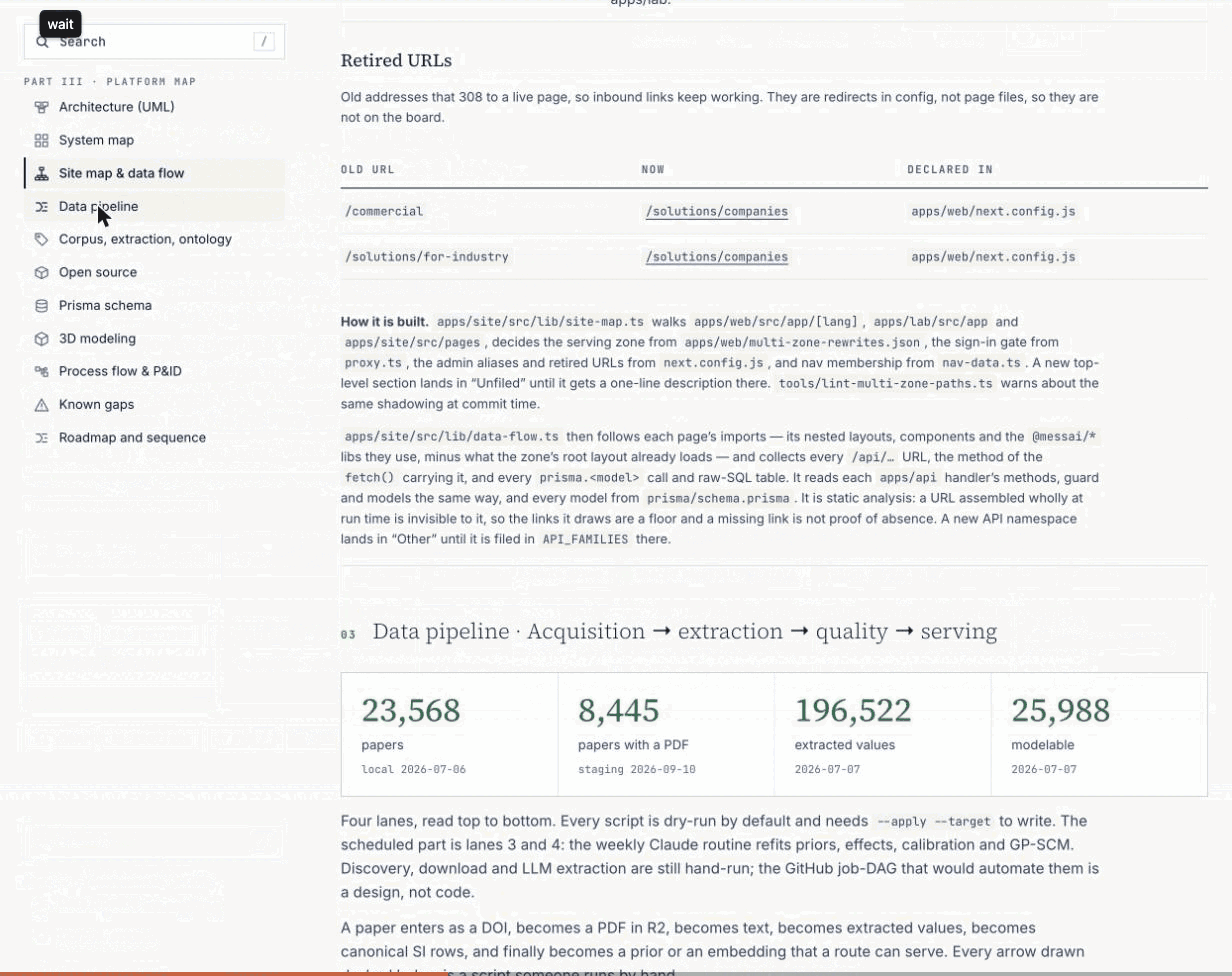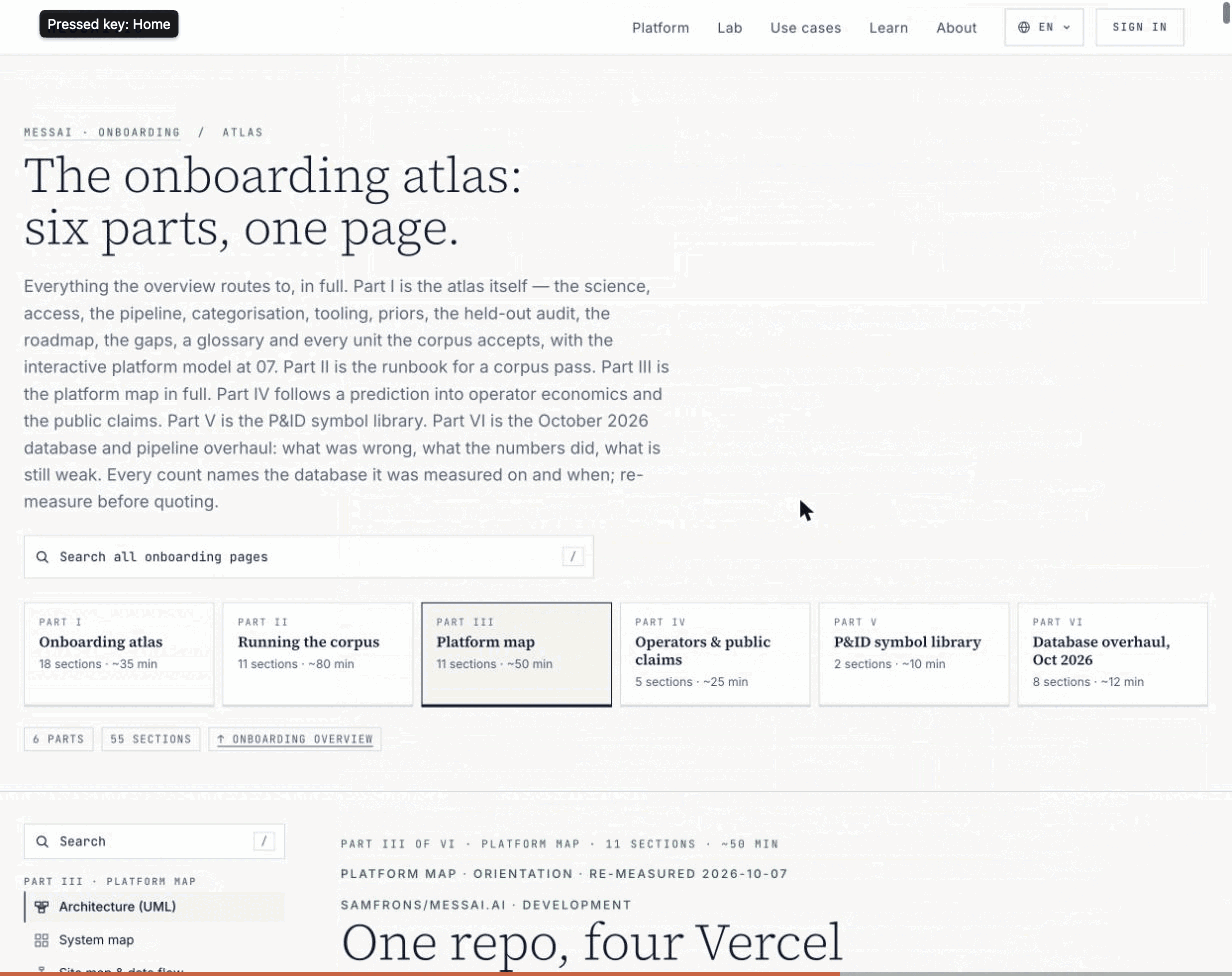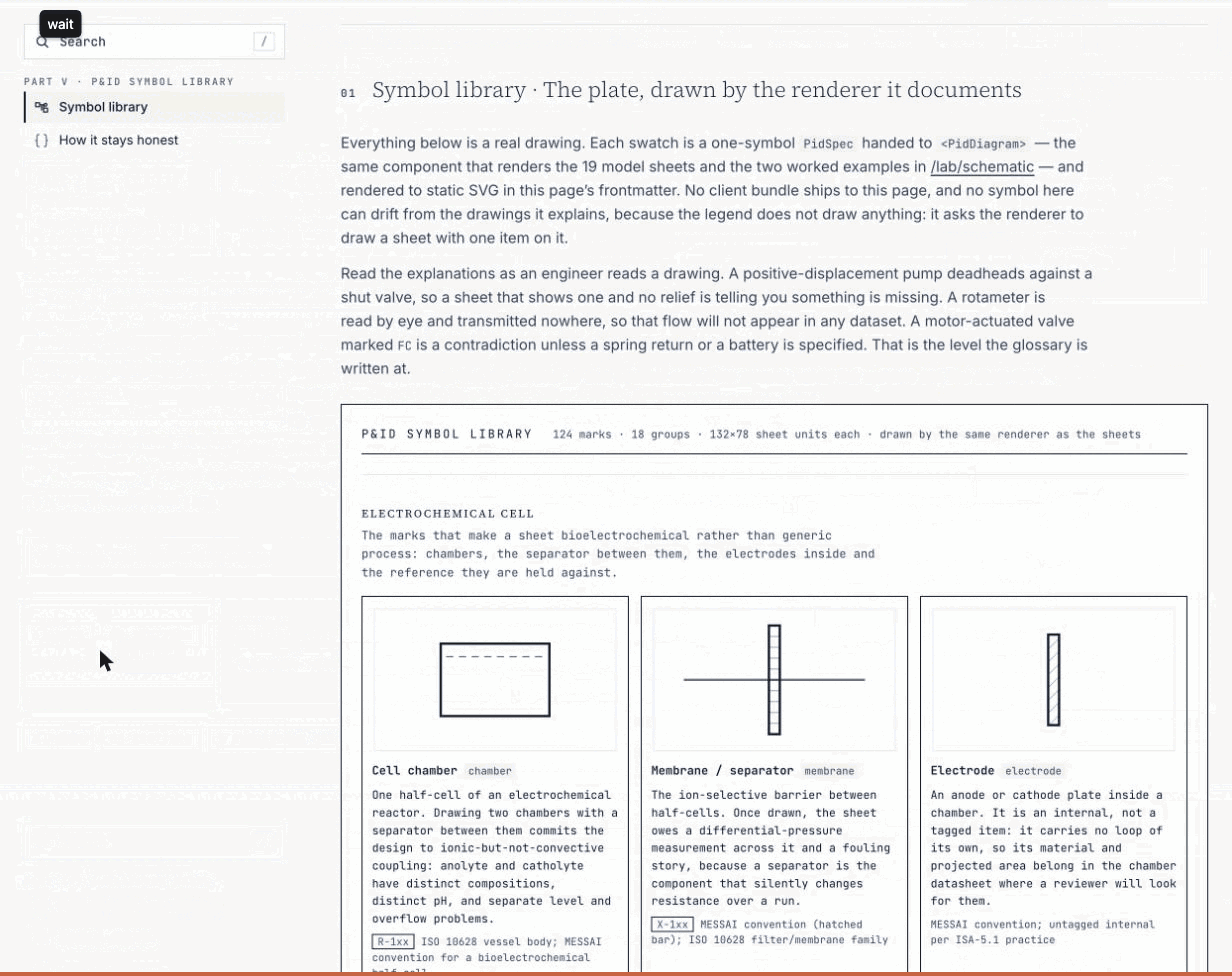
Everything the overview routes to, in full. Part I is the atlas itself — the science, access,
the pipeline, categorisation, tooling, priors, the held-out audit, the roadmap, the gaps, a
glossary and every unit the corpus accepts, with the interactive platform model at 07. Part II is the runbook for a corpus pass.
Part III is the platform map in full. Part IV follows a prediction into operator economics and
the public claims. Part V is the P&ID symbol library. Part VI is the October 2026 database and
pipeline overhaul: what was wrong, what the numbers did, what is still weak. Part VII is the walkthrough by screen: what each part of the platform is for, the steps to take and how to read its numbers. Every count names the database it was
measured on and when; re-measure before quoting.
Part I of VII · Onboarding atlas · 18 sections · ~35 min
MESSAI · Onboarding · 2026-09-07
The science, three databases, one bucket, six pipeline stages, and the week that changed the diagnosis.
The Onboarding Atlas, keeping the artifact’s numbering. Sections 01–05 are the science with no repo access needed; 06 is where the data lives and 11 the acquisition tooling; 13–14 are what the models can actually do and the held-out audit that measures it; 15–18 are the July 2026 week, the roadmap, the ranked gaps and the glossary. 07 and 12 are pointers: the platform map is Part III and the corpus runbook is Part II. The corpus reference that used to sit here as 08–10 — the pipeline, categorisation and ontology, growing the corpus — now lives in Part II as 08–10, next to the runbook it belongs to. Every number carries its date; re-measure before quoting.
3 + 1
Environments local · staging · prod, plus one shared R2 bucket
last discovery run acquisition stalled; 2025–26 is 23% PDF-backed
as of the 2026-09 audit · see Part II · 10 Growing the corpus
4.1%
of the R2 corpus usable for modeling before the July work
316 of 7,782 · CORPUS-DIAGNOSIS.md
00Before you touch anything · what to load, and what never to do
This is the reference half of onboarding. If you are looking for where to start — the four routes, the six pipeline stages, what the platform can and cannot support, and your first task — that is the onboarding overview, and it takes about six minutes. This page is what you read once you know which part you need.
Part I is numbered on its own 00–18 scale, so a cross-reference like “see 08 Pipeline” means section 08 of this part. Every number here carries the database it was measured on and the date; re-measure before quoting. The other four parts, with their section counts and read times, are listed at the foot of this page.
For agents, load before touching anything
The memory index at ~/.claude/projects/-Users-samfrons-repos-messai-ai/memory/MEMORY.md, then four entries in particular: feedback-corpus-lives-on-staging-not-local, feedback-grade-experiment-records-not-paper-completeness, feedback-dangling-node-modules-symlinks-false-green-typecheck, project-acquisition-path-status-2026-09-07.
The six skills that carry the procedures: mes-paper-retrieval, mes-parameter-extraction, mes-data-harmonization, mes-db-migration-sync, mes-experiment-modeling, mes-knowledge-graph.
Never write to a remote database except through resolveDbTarget(), gated on the Supabase project ref. Staging and production share a pooler hostname, so a hostname check proves nothing.
Never start a paid extraction without a three-paper smoke run first.
Archive, never delete. Move rows and files; do not drop them.
Never quote a corpus number that is older than its last re-measurement. Re-measure the target database and carry the date.
Never trust a type check you have not watched fail. Forty-six dangling symlinks in the root node_modules make the type gate report false green.
Read this first if the science is new to you. A microbial electrochemical system (MES), also called a bioelectrochemical system, uses the electrochemical activity of living microorganisms to interconvert chemical and electrical energy, or to drive synthesis. Every device in the taxonomy is a variation on one cell; what changes is the reaction you drive and the product you harvest. The full treatment is on /learn/science; the two diagrams below are the pair everything later in this page assumes.
The reference device
In the canonical case — a microbial fuel cell — electroactive bacteria colonise an anode and oxidise an organic substrate such as acetate or the organic load of wastewater. Oxidation releases electrons, which the bacteria deposit onto the electrode instead of onto a soluble acceptor. Those electrons travel through an external circuit to a cathode, where they reduce a terminal acceptor, often oxygen. The electron flow is a usable current; the proton flow that balances it closes the circuit through the electrolyte.
The biofilm on the anode oxidises substrate and deposits electrons on the electrode; they do useful work through the external load and return to the cathode, while protons migrate through the electrolyte to close the circuit. Redrawn from /learn/science.
The core mechanism
Oxidise, transfer, reduce
Bacteria at the anode oxidise substrate and release electrons. Electrons flow through the external circuit to the cathode, generating power while reducing an acceptor. Protons migrate through the electrolyte or a membrane to balance charge.
Why microbes
Self-replicating catalysts
Microbes are self-replicating, self-repairing catalysts that work at ambient temperature and pressure, and can process complex, dilute waste streams that precious-metal catalysts handle poorly or not at all.
Why the method looks like this
Two facts govern everything
The literature reports the same quantity in mutually incompatible ways — different normalisation bases, peak versus steady-state, undeclared reference electrodes — so raw numbers cannot simply be averaged. And the headline metrics are heavy-tailed across orders of magnitude, so a single number is almost always the wrong answer.
The disciplined response
Five verbs
Classify precisely, extract with provenance, harmonise ruthlessly, model on the log scale, and report calibrated distributions rather than point values. Sections 02 to 05 are the first two verbs; Part II and Part III are the third; Part IV is the last two.
The public methodology page, section by section
Everything on messai.io/learn/science is carried here, so either page answers the question and neither is the only copy. That page is the outward-facing account and is depth-layered behind “Read the full method” panels; this one adds what was measured internally, and says where the two disagree. Use whichever you are already in.
On messai.io/learn/science
What it covers
Here
Overview
What an MES is, the reference device, why microbes, the two facts that shape the method
Sibling pages that page links out to, not duplicated here: System types, Sustainability, History of MES, the proof dashboard (live database counts and training artifacts per request) and the whitepaper — the strategic why, where the science page and this Atlas are the technical how.
The four public claims, and where each one is tested here
Claim
What the public page says
Where it is audited in this Atlas
honesty Honest data-quality signals
Every prediction ships a data_status field. Missing artifacts surface as awaiting_artifact, never a silent zero. Power-density CoV ≈ 1,285%, so point estimates always travel with context.
The output contract and its two refusal states, 13. The CoV and why no bare mean is quoted, 05.
coverage Full taxonomy coverage
17 primary types + 12 combinations + multi-axis subtypes. No silent coercion of MES / MDC / MMRC papers to MFC-shaped output — every system routes through its physics family.
The taxonomy itself, 02. What the corpus actually carries, 09: primarySystemType is NULL on 10,286 visible papers, and five vocabularies describe the same papers.
traceability Provenance on every value
Every extracted number is linked to its source paper. About half also carry the verbatim snippet, with an extractor version and confidence — where that is missing they say so rather than implying a quote. Roughly a quarter of papers have no DOI.
Provenance fields and the disk-vs-DB audit, 08. What “done” means for a row, 08. The 2,075 no-DOI papers, 17.
rigour Statistics that respect the data
Hierarchical, log-scale priors that pool strength across classes — not arithmetic means of heavy-tailed distributions. The mathematically wrong v0 was retired, not shipped.
The priors and partial pooling, 13. Whether they beat a class median on paper-disjoint data, 14 — the answer is no, for every model tried.
The proof numbers, as published in July 2026 (historic figures, 2026-07): 23,568+ curated papers, 195,846 extracted value rows, 2,812 parameter-graph edges, and 97.98% out-of-sample interval coverage on MFC + MEC, with an honest-gaps section naming what is thin or unvalidated. Two of those need the footnote this Atlas adds: the coverage figure was computed on a split that 14 shows is separable at AUC 0.77–0.92, and the corpus counts are dated snapshots that differ slightly from the staging measurements below. Since 2026-10-25 the site quotes the count /research lists, which leaves out stub rows and merged duplicates, so the current figure is lower than the counts on this page; take today’s number from /research, not from here. Open data: the curated packages are public — canonical microbes, electrode materials with DFT-derived properties, the parameter ontology, and a catalog of external datasets — each shipping a SCIENTIFIC_INTEGRITY.md of known caveats, with large blobs mirrored to Hugging Face. Details in 07.
The canonical taxonomy (version 2) is 17 primary system types — 14 real devices plus 3 meta classes — with 12 combination types, multi-axis subtypes, an 11-value study-focus axis and 8 application domains, all routed for prediction through 5 physics families. It is the authoritative classifier that the extraction pipeline, the ML predictors and the UI all share; the enum lives in apps/web/src/lib/taxonomy/system-types.ts. Section 09 measures how much of the corpus actually carries each value.
Why the family, not the device, is the unit of prediction
Restricting the world to MFC / MEC / MDC — as most tools do — silently coerces desalination, metal-recovery, synthesis and sensing systems into fuel-cell-shaped output. The right abstraction is the physics family: the group whose transport and reaction physics actually govern the outcome. Predictions route to a family; subtypes become features, combinations become coupling rules. The rationale is statistical: branching on all 17 types would train rare classes on a handful of papers each and return noise.
Anodic oxidation
MFC · MESNORK · MRB
Organic substrate oxidation at a bio-anode. The energy-harvesting workhorse — power generation, and the electron supply for downstream reduction.
Cathodic reduction
MEC · MES · MEFS
A reaction driven at the cathode: hydrogen evolution, CO₂ fixation to organics, or Fenton-reagent generation. Often needs a small applied voltage.
Ion transport
MDC · MREC · MCDI · MNRC
Selective ion migration across ion-exchange membranes — desalination, salinity-gradient power, capacitive deionization, nutrient migration.
Selective reduction
MMRC · MERC
Targeted reduction of a specific species — metal recovery, and the electro-driven degradation or immobilisation of contaminants.
Sensor / photo
MBES · MSC
Current as a signal (biosensing) or light as a driver (biophotovoltaics), where the output tracks an analyte or a photosynthetic input rather than bulk power.
The full device roster
Type
Full name
Family
What it does
MFC
Microbial Fuel Cell
anodic
Oxidises organics, delivers current spontaneously
MEC
Microbial Electrolysis Cell
cathodic
Adds a small voltage to make H₂ at the cathode
MES
Microbial Electrosynthesis
cathodic
Reduces CO₂ at the cathode into organics
MDC
Microbial Desalination Cell
ion
Field drives ions out of a middle chamber
MSC
Microbial Solar Cell / Biophotovoltaic
sensor/photo
Couples phototrophy to the electrodes
MEFS
Microbial Electro-Fenton System
cathodic
Generates H₂O₂ / •OH to degrade pollutants
MESNORK
Microbial Electrochemical Snorkel
anodic
Short-circuited electrode accelerates oxidation
MERC
Microbial Electroremediating Cell
selective
Degrades or immobilises a target contaminant
MNRC
Microbial Nutrient Recovery Cell
ion
Recovers N / P (ammonium, struvite)
MMRC
Microbial Metal Recovery Cell
selective
Reduces dissolved metals at the cathode
MRB
Microbial Rechargeable Battery
anodic
Bioelectrochemical energy storage
MBES
Bioelectrochemical Sensor
sensor/photo
Current tracks an analyte (BOD, toxicity, …)
MREC
Microbial Reverse Electrodialysis Cell
ion
Harvests salinity-gradient energy
MCDI
Microbial Capacitive Deionization Cell
ion
Capacitive ion storage for deionization
Three meta classes complete the 17: REVIEW (review / meta-analysis), FUNDAMENTAL (mechanistic electron-transfer studies) and OTHER (genuinely novel architectures). They are tracked so the predictor never mistakes a review’s cited numbers for fresh measurements — the same reason 26.3% of values sourced from references is a headline finding in 15 July 2026 agents. Abiotic fuel cells (PEM, SOFC, PAFC) are a separate taxonomy: the predictor stack has tuned physics for them, but they are not bioelectrochemical and are kept out of the BES classifier so a proton-exchange-membrane paper never contaminates the microbial priors.
Careful: MES means two different things
On this page and on the public science page, MES is the umbrella — microbial electrochemical system, the whole field.
In the extraction schema and in primarySystemType, MES narrowly means Microbial Electrosynthesis, cathodic CO₂ reduction: one of the 14 devices. audit-non-bes-candidates.py uses the second sense throughout.
Physics families are for calibration strata and out-of-distribution detection, not as predictors in their own right, and there is still no TypeScript constant for the family mapping — it lives in prose in docs/system-class-aware-predictor-architecture.md. See the ontology rules in 09.
Subtypes: orthogonal axes, not one flat list
Subtypes are stored as an object of orthogonal axes because a token like acetate means something different for a synthesis product than for a substrate. Each primary type populates the axes that make sense for it.
Real reactors are often two systems at once. Rather than train a separate model per combination — which would be starved of data — each is treated as a coupling rule over the base families. The best-studied combinations carry their own variants: CW_MFC splits into horizontal_subsurface_flow, vertical_flow and floating.
Two orthogonal axes: study focus and application domain
The primary type says what reactor a paper is about. Two further axes say what kind of study it is and what it is for, so a query can ask “which MFC papers are about new anode materials for wastewater?” without full-text search.
power_generation · wastewater_treatment · resource_recovery · electrosynthesis · bioremediation · desalination · biosensing · general. A paper can carry several. This axis is the most specific stratum key in prior lookup, so a missing domain silently falls back to a coarser prior.
03Thermodynamics & kinetics · What a cell can do, and what it actually does
What a cell can do is bounded by thermodynamics; what it actually does is set by kinetics and losses. Thermodynamics gives the ceiling, and the ceiling is the gap between the two half-reaction potentials.
Cell potential and free energy
E_cell = E_cathode − E_anode
ΔG = −n · F · E_cell
E = E° − (RT / nF) · ln(Q) (Nernst — potential at real concentrations)
n = electrons transferred · F = Faraday constant, 96 485 C/mol · R = gas constant · T = temperature · Q = reaction quotient.
The redox ladder
Each half-reaction has a standard potential on the standard-hydrogen-electrode (SHE) scale, shifted for real concentrations by Nernst. The cathode couple sits high, the anode couple sits low, and the vertical gap between them is the theoretical cell voltage. Swap the cathode couple and you have a different device.
Half-reaction
E° (V vs SHE)
Role
O₂ + 4H⁺ + 4e⁻ → 2H₂O
+0.82 (pH 7)
Air-cathode acceptor (MFC)
Fe(CN)₆³⁻ + e⁻ → Fe(CN)₆⁴⁻
+0.36
Common lab catholyte
2H⁺ + 2e⁻ → H₂
−0.41 (pH 7)
MEC cathode, hydrogen evolution
acetate / CO₂ couple
≈ −0.28
Acetate oxidation at the anode
CO₂ → acetate (8e⁻)
≈ −0.28 to −0.5
Electrosynthesis target (MES) — below the anode, which is why it needs an energy input
An air cathode (O₂/H₂O, +0.82 V) against an acetate-oxidising anode (≈ −0.28 V) gives E°cell ≈ 1.1 V. Real cells deliver 0.3–0.8 V after losses.
Where the 1.1 V goes — the loss cascade
The 1.1 V ceiling is spent, not delivered. Activation overpotential (the kinetic price of turning the reactions on), ohmic loss (IR drop through electrolyte, membrane and contacts), and concentration overpotential (reactant depletion at the surface) each take a bite, leaving 0.3–0.8 V under load. Illustrative split, redrawn from messai.io/learn/science.
η_act
Activation
The kinetic price of driving each electrode reaction at a useful rate. Dominates at low current.
η_ohmic = IR
Ohmic
Resistance of the electrolyte, membrane, electrodes and connections. Grows linearly with current.
η_conc
Concentration
Depletion of reactant, or build-up of product, at the electrode surface. Dominates at high current and sets the ceiling on current.
Kinetics: Butler–Volmer and Tafel
Kinetics turns a thermodynamic possibility into a rate. The governing relationship between overpotential and current density is the Butler–Volmer equation, with the biofilm acting as the anode’s catalyst layer.
Butler–Volmer, and its Tafel limit
j = j₀ · [ exp(α_a · F · η / RT) − exp(−α_c · F · η / RT) ]
Tafel (large |η|): η = a + b · log₁₀(j) b = 2.303 · RT / (α · n · F)
j = current density · j₀ = exchange current density · η = overpotential · α_a / α_c = charge-transfer coefficients · b = Tafel slope in mV/decade.
The exchange current density j₀ captures how intrinsically fast the electrode reaction is at equilibrium; the transfer coefficient α sets how symmetric the anodic and cathodic branches are; and the Tafel slope — the straight-line region on a log-current plot — is what most papers actually report, from which α can be back-fitted. A good bio-anode has a high j₀: the reaction turns on for less overpotential, so more voltage reaches the load. Every millivolt of η is voltage you do not deliver.
The polarisation curve, and the four levers
Sweeping the load traces voltage against current. The three regions map one-to-one onto the three losses — activation (the steep initial drop), ohmic (the linear middle), mass transport (the final collapse) — and the power curve peaks where the external load matches the internal resistance. That peak, not the open-circuit voltage, is what a design is optimised toward, which is why extracting a single quoted “maximum power density” without its derivation method is lossy (see the derivation_method field in 12 Corpus run).
Reactant must diffuse across a thin diffusion layer to reach the electrode. Push the current higher and the surface concentration falls; when it reaches zero the current is diffusion-limited and cannot rise further, no matter the voltage. That is the collapse at the right of the curve, and the limiting current.
Lever
Mechanism
Where it stops working
Shrink electrode spacing
Lower ohmic resistance → higher power
Until mass transport or short-circuiting intervenes
Raise electrolyte conductivity
Lower ohmic resistance
Within osmotic and biological limits
Grow a better biofilm
Raise j₀, lower activation overpotential at the anode
Biofilm thickness has a sweet spot — see 04
Improve the cathode catalyst
The cathode is frequently the limiting electrode in air-cathode MFCs
Cost and durability
Internal resistance is often the single largest lever on power: the sum of ohmic resistance (electrolyte, membrane, electrode spacing) and the charge-transfer resistances of both electrodes. By the maximum-power-transfer theorem, power delivered to the load is maximised when the external resistance matches the internal resistance — which is why it is one of the parameters the knowledge graph links to power with a causal edge.
Impedance (EIS). Electrochemical impedance spectroscopy applies a small AC perturbation across a frequency range and fits the Nyquist spectrum to an equivalent circuit — typically a Randles circuit — separating losses a single DC polarisation curve blends together: Rs solution resistance (the high-frequency intercept, the ohmic term), Rct charge-transfer resistance (the semicircle diameter, inversely related to j₀), Cdl double-layer capacitance, and the Warburg low-frequency diffusion tail. EIS spectra are Tier C on the extraction roadmap (12 Corpus run) — the schema does not capture them today.
Why the platform does not compute these from first principles
These levers interact non-linearly and trade off against each other — shrinking the electrode gap that lowers ohmic loss can also starve mass transport.
The losses are coupled and depend on variables papers report unevenly, so a fitted analytic model generalises poorly across the corpus.
MESSAI therefore learns their net effect empirically, conditioned on system class. The served physics layer is a 0-D mean function, not a spatially-resolved multiphysics model — stated plainly so it is not oversold. 14 Held-out benchmark measures what that buys.
04Biofilm & EET · How bacteria put electrons on a rock
The defining trick of MES is extracellular electron transfer (EET): electroactive bacteria route respiratory electrons onto a solid electrode instead of a soluble acceptor. Understanding EET is understanding the anode.
Route 1
Direct transfer
Outer-membrane multiheme cytochromes make near-contact with the electrode, within about 1–2 nm, and hand off electrons directly. Fast, but limited to cells touching the surface.
Route 2
Conductive nanowires (pili)
Conductive protein filaments extend microns from the cell, wiring distant cells into the electrode and letting thick biofilms stay electrochemically active.
Route 3
Mediated transfer
Soluble redox shuttles — flavins secreted by Shewanella, or added mediators — ferry electrons across the gap. Effective, but shuttles can wash out of flow-through reactors.
Route 4
Biofilm-matrix conduction & DIET
Conduction through the matrix itself, so current scales with active biomass. Direct interspecies electron transfer lets one species hand electrons to another through pili or minerals — the basis of syntrophic consortia and electromethanogenesis.
The four routes are usually mixed in one biofilm, which is why by_mechanism (direct_ET_cytochrome, direct_ET_nanowire, mediated_endogenous, mediated_exogenous, interspecies_ET) is a subtype axis on FUNDAMENTAL papers rather than a device class.
Uptake is proportional to concentration when substrate is scarce and flattens to a maximum when it is abundant. K_s is substrate-specific, which is why substrate identity is kept as a canonical feature rather than pooling glucose and acetate kinetics together — and why substrate being the worst-linked input in the corpus (0.7% coupled, see 12) is a modelling problem, not a cosmetic one. On 2026-09-08 the identity μ_max = ln 2 / doubling time validated three values the paid LLM verifier had rejected: a free invariant beating a paid check.
Two facts about biofilms that shape the data model
Biofilm thickness has a sweet spot. Too thin and there is not enough catalyst; too thick and substrate cannot diffuse to the inner layers while protons cannot escape, so the interior goes acidic and inactive. The knowledge graph encodes this as a causal edge (biofilm thickness → power density) rather than a monotonic rule.
Community composition matters as much as any single species. Real anodes are mixed communities where fermenters, syntrophs and electroactive bacteria form a food web. Enrichment and inoculum are among the least reproducible variables in the literature — which is why the extractor records the community-analysis method (16S versus metagenomics) as a confidence signal, not just the organism name. Inoculum is reported on 0% of benchmark rows (14).
05Performance metrics · What is measured, and the normalisation trap
MES performance is reported through a compact set of metrics, but with inconsistent normalisation across the literature. Knowing exactly what a number is normalised to is the difference between a fair comparison and a meaningless one.
Metric
Typical unit
What it tells you
Power density (areal)
mW/m²
Power per electrode area — the most-cited MFC metric
Power density (volumetric)
W/m³
Power per reactor volume — the scale-up metric
Current density
mA/cm² · A/m³
Electron flux per area or volume
Coulombic efficiency
%
Fraction of substrate electrons recovered as current
COD / BOD removal
%
Organic load removed — treatment performance
Cell voltage / OCV
V
Working voltage under load / open-circuit voltage
Internal resistance
Ω · Ω·cm²
From the polarisation slope or an EIS fit
Energy efficiency
%
Useful energy out / energy in
H₂ production rate / yield (MEC)
m³/m³/d · mol/mol
Rate and recovery for electrolysis cells
Product titre / rate (MES)
g/L · g/L/d
Electrosynthesis output
Salt removal (MDC)
% · mg/L
Desalination performance
Sensitivity (MBES)
signal / analyte
Biosensor response
The normalisation trap, and why it is the platform’s central discipline
Power density is the worst offender. The same reactor can be reported at wildly different numbers depending on whether power is divided by anode area, cathode area, membrane area, or reactor volume.
Areal and volumetric densities are therefore routed to separate canonical kinds so they never pool into one prior. Mixing W/m² and W/m³ is a category error that contaminates the posterior roughly 1000× — the first harmonization hard rule in 08 Pipeline.
Every row records normalization_basis (anode vs cathode vs membrane vs volume) and value_kind / phase (peak vs steady-state), because those distinctions are worth 1.5–3× and up to 10–1000×. Peak-versus-steady-state alone produces 2–3× errors.
Reference electrodes are the quiet one. A 30–110 mV offset between reference types makes raw voltages incomparable; everything is normalised to vs-SHE. This is the single genuinely missing field in the v2 extraction schema — voltage_reporting_convention, whether a value is vs Ag/AgCl, vs SHE, or a whole-cell voltage. See 12.
The three efficiencies are not interchangeable. Coulombic efficiency is the fraction of available substrate electrons recovered as current, bounded 0–100%. Cathodic capture is the fraction of arriving electrons that end up in the desired product (H₂, acetate) rather than side reactions. Energy efficiency combines voltage and coulombic losses into the bottom line.
Why a bare mean is never quoted
Power density is right-skewed over orders of magnitude, so the arithmetic mean is dragged far past the median by a handful of high performers. The median describes a typical system; the mean describes almost none. Across the corpus the coefficient of variation is ≈ 1,285%. This is the concrete reason the priors are fitted on the log scale (13), and the reason the served interval on power density is four decades wide (14).
Coulombic efficiency is the diagnostic one
It is bounded and interpretable: a high current with low coulombic efficiency means electrons are leaking to alternative acceptors — oxygen crossover, methanogenesis, other respiration — rather than reaching the electrode. It is often more informative about the biology than power density is. On the held-out benchmark it is also the target with the widest between-paper spread (2.04 logit).
Always read the interval, the system class and the normalisation before comparing two numbers. Section 09 is how a raw name becomes a canonical slug and an SI value; section 14 is what happens when you try to predict these metrics across papers; 19 lists every unit the normaliser accepts, the factor it applies and what it refuses to convert.
06Where the data lives and who may write to it
Staging and prod share the same Supabase pooler host in eu-central-1, so a hostname check proves nothing. Every remote write in scripts/ passes through resolveDbTarget(), which pins staging to its project ref and demands --expect-ref for prod. Promotion is one direction, additive, schema before data.
Refs and ports verified against scripts/lib/db-target.ts and .env.local on 2026-09-07. No secret values.
Day-one checklist
#
Get
From
Verify with
1
GitHub access to samfrons/messai-ai
the repository owner
git clone
2
.env.local + .env.development.local
the repository owner, out of band. Never chat, never git.
bash scripts/quality/preflight-corpus-work.sh
3
R2 token, bucket-scoped to messai-papers
the account owner · Cloudflare → R2 → Manage API Tokens
Not on day one. Handed over per task; every prod --apply is announced first.
Each rule is a past incident
Never DROP, TRUNCATE, reset or force-overwrite. Archive by moving or soft flags.
Migrate schema before syncing data. Sync intersects columns and silently drops the rest. Lost 22 patent rows, 2026-05-13.
Sync is insert-only. Backfilling existing rows is a separate NULL-guarded UPDATE. The most common "my sync failed".
Never pg_dump over :6543. The 2026-05-12 dump was 9 MB with zero data rows; DIRECT_URL gave 400 MB.
Verify a backup by row count.grep -c '^COPY public\.' ≈ 60–80.
Never put DB URLs in .env. The Prisma CLI reads it directly.
Dead variables that still answer
STAGING_DATABASE_URL — old Prisma host, empty since 2025-08-09.
PRODUCTION_DATABASE_URL, DEVELOPMENT_DATABASE_URL — retired 2026-08-11. They respond with a stale 3,892-paper snapshot; pnpm backup dumped the wrong DB for months.
Root cause: a duplicate accessor for a string an env file already owns. Never add another.
dotenv.config() writes into process.env; resolving two targets in one process leaks the first URL into the second. Use dotenv.parse.
07Platform map · One repo, four zones, one Postgres
Part III is the platform map The measured platform — zones, schema, pipeline, 3D, P&ID, open source, gaps — lives once, in the Platform map tab. This section only opens the interactive model so it is one click from the atlas.
Architecture: one model, eight UML views
Eight UML 2 views over one model of the whole platform. C1 is the altitude everything else hangs from: three kinds of actor, four Vercel zones, the shared packages, the state layer and the external systems. Every box with a + corner opens its own diagram — the four zones, the package graph, the persistence model and the corpus pipeline — and Esc comes back up. Structural counts were measured against this repository on 2026-09-09; corpus and science numbers deliberately stay out of the diagram and live in the dated tiles.
C1System contextComponent / deployment diagram
100%
One repository, four Vercel projects, one Postgres. Everything a browser touches enters through apps/web, which owns the rewrite table; everything that writes to the database goes through apps/api. Click any node to open it.
actor Vercel zone / route group shared package state batch script external system dormant
ML engine «service» — Docker · local/batch · :8001
GitHub · Google OAuth «external» — identity providers
Sentry «external» — @sentry/nextjs · apps/api
Resend «external» — transactional email
Prerequisites. The memory entries to load, the six skills that carry the procedures, the three gates that tell you a run actually worked, and the rules that are never negotiable are in 00 Before you touch anything. The five-layer state table is in Part II · 00.
What Part III carries
The rest of the platform is drawn and inventoried in Part III, once: the
interactive UML model of the whole
infrastructure, the site map of every page and
the zone that serves it, the Prisma schema and its
hub-and-spoke relation map, the data
pipeline as it actually runs, the 3D stack
and the four registries a new reactor model must join, the
P&ID library, the
nine open-source packages, and the
dependency order between the gaps. This
section is the orientation; that is the reference.
08Design system · One component library, three generations of it
Every surface MESSAI ships is supposed to be built from @messai/ui and the Tailwind preset next to it. Most are. This section is the inventory a newcomer builds against — what exists, which generation is live, the rules that are not negotiable, and the measured distance between the rule and the tree. Counted against development on 2026-09-11; re-measure before quoting. Three things have moved since that count: the stock-colour rule became a lint ratchet (2026-09-12), the palette became warm monochrome (2026-10-05), and v3 was folded into v1 and archived (2026-10-06) — all noted below.
48
live components what @messai/ui exports
the v1 tier
0
v3 components left behind @messai/ui/v3
archived 2026-10-06 · two parts folded into v1
20
app-local duplicates of library components
own code, not shims · 8 files left after 2026-09-12
2,823
hard-coded palette classes outside the token set
was 4,489 at v3 branch start
1
Tailwind preset every zone extends it
tailwind-preset.cjs
The three hard rules
Not negotiable — two are lint-enforced
No border-radius, anywhere. Sharp corners are the intended aesthetic. Two exceptions exist and no third one does: rounded-chip (2 px) for the badge / tag / pill family, and the radio button, which uses an inline borderRadius: 9999 rather than widening the Tailwind enum. Enforced by no-restricted-syntax.
Native <select> is banned — use Select from @messai/ui. Enforced by the same rule, with a 21-path allowlist that grandfathers surfaces mid-migration. Each follow-up removes its own entry; when the list empties the rule applies platform-wide on its own. Do not add to it.
Colour comes from the preset, never from Tailwind's stock palette.text-blue-600 and bg-red-50 have no place in a MESSAI surface — the mes-* tokens carry the meaning, so a value swap in the preset moves every page at once. Enforced since 2026-09-12 by messai/no-stock-palette as a ratchet: tools/stock-palette-allowlist.js names the 183 files that already offended, the rule is on everywhere else, and pnpm tsx tools/stock-palette-allowlist.ts refuses to make the list longer. Since 2026-10-05 the stock scales are also remapped in the preset (amber → caution ochre, red/rose → critical rust, green/teal → positive moss, blue/gray → the warm neutral ramp), so a legacy class at least lands on-palette.
What exists, by tier
Tier
Where
Count
What it is
Atoms & molecules
src/components
48
Button, Input, Select, Checkbox, Radio, Switch, Slider, Label, Link, Code, Tag, Badge, Pill, Divider, Skeleton, Spinner, Eyebrow, FormField, Segmented, Card, AnchoredCard … This is the tier the @messai/ui barrel exports, so it is what an import gives you today.
UniversalHeader (7 files), UniversalFooter (4), AuthMenu, top-bar. The cross-zone furniture — a new zone mounts these rather than drawing its own.
Shells
—
0
The v3 AppShell, LabShell and MarketingShell had no production consumer and were archived with v3 on 2026-10-06 (archive/2026-10-ui-v3/). A page mounts the chrome above directly.
Tokens
tailwind-preset.cjs
1
The single build-time source every zone extends. Colour, spacing, type scale, the rounded-chip exception, motion durations.
The catalogue is drawn, not just listed: /design-system renders live token swatches and component examples.
Three generations, and only one is live
This is the thing to understand before adding a component, because the obvious guess is wrong twice.
Generation
Import path
Consumers
Status
v1 · src/components
@messai/ui
every zone
live The barrel exports this tier and nothing else. Build against it.
v3 · archived
—
0
folded into v1 Archived 2026-10-06 with its /dev/v3 proving page (archive/2026-10-ui-v3/). The two parts with production use moved into the v1 tier: DetailDrawer is now exported from @messai/ui, and the v1 Segmented gained v3's radio-group ARIA, arrow / Home / End keys, ariaLabel and per-option disabled. Its tokens had already shipped — see below.
app-local · apps/web/src/components/ui
relative
8 files
duplicate 22 files on 2026-09-11, of which only 2 were thin re-export shims. The 2026-09-12 collapse moved their importers onto @messai/ui; 8 files remain, each for a stated reason — badge and the shadcn-shaped tabs / dropdown-menu would change what a page renders if swapped, and icons.tsx (468 lines) should be promoted into the library rather than deleted.
The token swap landed; the component migration did not
Tokens: done, twice. The v3 palette was applied in place — the mes-* class names were kept and their hex values pivoted, so every page picked up the new values with no code change (old→new table: docs/ui-token-reconciliation.md). On 2026-10-05 the same mechanism moved the platform to warm monochrome: one near-black ink in three shades (#0C1638 / #33406B / #6B7593) on cream #FAFAF6 and white, rules #E6E3DA. The accent is the ink — buttons, active tabs and links are monochrome — and colour only means state (caution ochre, critical rust, positive moss) or data (the categorical set, charts only). Table and rules: docs/ui-conventions.md “Colour and type tokens”; the static decks and this atlas read the same values through libs/shared/ui/src/styles/deck.css.
Typography: one token system. Inter for UI and body, JetBrains Mono for labels and data, Source Serif 4 for titles (a webfont, so every OS draws the same face) — exposed as --messai-font-sans, --messai-font-mono and --messai-font-serif. The old split (DM Mono body, IBM Plex only through a v3 shell, Crimson Text titles) is gone; hard-coded family names are the thing to avoid.
The residue is the hard-coded colours. A page that mixes bg-mes-paper with text-blue-600 looks half-migrated, because the token moved and the literal did not. 2,823 such classes remained on 2026-09-11, down from 4,489 when the v3 branch opened; the lint ratchet above means that number can only fall.
Where the site is inconsistent today
Zone
Hard-coded palette
Native select
rounded-*
Read
apps/web
2,345
25
4
Carries essentially all of the debt, and all 21 allowlist paths.
apps/lab
374
4
1
Mostly clean; the 3D surfaces are the exception.
apps/site
100
3
0
Astro islands, where Radix context is unavailable, take a documented inline disable.
apps/api
3
0
1
No UI bundle; these are incidental strings.
libs/shared/ui
277
8
3
The library itself breaks its own rules. Fix here first — a primitive that hard-codes a colour re-exports the problem to every consumer.
Adding or changing a component
The order that avoids re-doing it
Look in @messai/ui first, then /design-system. Most of what a surface needs already exists under a name you would not have guessed — Segmented, MetricWithProvenance, AnchoredCard, TrustBadge, Eyebrow.
A new primitive belongs in the library, not the app. That is the rule apps/web/src/components/ui broke twenty times. Shared UI goes in libs/shared/ui; if you need it in a second zone later, it is already there.
Compose from tokens. No hex literals, no stock Tailwind palette classes, no rounded-*. If a token is missing, add it to the preset — one edit that every zone inherits — rather than reaching for #3A6FA0 at the call site.
Tailwind by default; SASS only where Tailwind is ugly. Multi-step keyframes, deep pseudo-element chains, @supports queries, or a component whose class chain would exceed ~6 classes and will not be reused. The module ships beside its component as <Component>.module.scss; shared variables live in libs/shared/ui/src/styles/.
Prove it on a page./design-system renders the library tier. A component with no example is a component the next person re-implements.
The two decisions this section cannot make for you
Who empties the colour allowlist? The rule got its linter on 2026-09-12 (a 183-file ratchet). A ratchet only stops the count growing; it shrinks when someone migrates a file and deletes its line. Run pnpm tsx tools/stock-palette-allowlist.ts to list entries that are already clean.
Who finishes apps/web/src/components/ui? The 2026-09-12 collapse took it from 22 files to 8. What is left changes rendering when swapped (badge, tabs, dropdown-menu) or belongs in the library (icons.tsx), so each needs a visual before/after, not a find-and-replace.
11Acquisition tooling · Six generations of scrapers, five stages, ~120 files
Every scraper, downloader, resolver and parser that built the corpus, surveyed 2026-09-07. Two download lineages coexist: lineage A walks a 9-provider chain per paper (download_from_db.py); lineage B runs tiered batch passes built to defeat the ~11k publisher 403s (scripts/acquisition/). Free and official providers only, never Sci-Hub or LibGen. Full per-file table with status and dates: docs/onboarding/acquisition-tooling-inventory.md; visual companion: the Scraper Atlas.
6
eras 2025-07 research agents → 2026-09-03 gap-driven discovery
git first → last commit
5
stages discover · resolve · download · store · parse
all inside pipeline stage 1
~120
files inventoried active · superseded · dead · one-shot
135 paths, all present 2026-09-08
9
providers in download_from_db.py
the mes-paper-retrieval skill still lists 6
Era
From
What
Today
0
2025-07
PubMed / CrossRef / arXiv clients + pdf-parse in the research-agents lib
dead
1
2025-08
arXiv + PubMed scrapers, seven "final" collection rounds, Nougat OCR, quality-tier PDF store
Retrieval is a batch job by rule, never a page load. The one live acquisition-adjacent route is admin/effects/gap-search, candidate-only. Admin import routes (admin/import, import/manual, import-priority-papers, data/process) are active.
The BullMQ layer (apps/api/src/lib/jobs/processors/paper-processing.ts) never ran in production: embeddings write Math.random(), extract returns a hardcoded 1250, no worker host exists. admin/papers/bulk-process front-ends it, dormant.
docs/corpus-refresh-architecture.md designed a discover → acquire → extract → sync → embed → refit GitHub Actions DAG on 2026-05-30; the workflow file never landed. An earlier weekly-acquisition.yml (2026-05-11) was archived then deleted.
No Zotero importer exists; the two mentions are aspirational. Sci-Hub and LibGen are excluded by rule, so a paper that fails every provider stays unreachable.
Text extraction went through three generations
Nougat (2025) → marker (April 2026) → reading BioC-PMC XML directly (May 2026). The XML path keeps tables intact and yields about 10% more values while skipping OCR entirely. Marker replaced Nougat because it handles tables and multi-column layout better and runs roughly ten times faster, and it pulls from R2 on a cache miss. Value extraction downstream is the separate v2 extractor. The whole 2025 Nougat stack — batch runner, FastAPI queue server, URL extractor, “research-grade” variant, PyMuPDF fallback, plus five TypeScript clients — is superseded or dead but still in the tree, with run_extraction.sh still wired to pnpm nougat:*. Do not restart from it.
Two cautions that cost time. papers/staging/resolution.jsonl is dated 2026-04-29, so DOI matches will miss and stubs named Local PDF <sha8> will be proposed — fix the SHA→DOI map before accepting them into a 23k-row corpus. And marker-quality text is patent-only today: 22 marker text files exist on disk against 1,375 values_v2.json artifacts, so everything else is PyMuPDF output.
12Corpus run · The atomic unit is the experiment record, not the paper
Every layer of the corpus pipeline already has a working component. Each one is either not wired to anything, never run, or broken by a small bug. Nothing here needs to be built from scratch; the work is to connect what exists and run it in dependency order, with a measured gate at each step. Grading a paper as complete tells you almost nothing about whether any single experiment inside it can be modeled.
The interactive pipeline map and every stage in detail are in Part II · 00 Pipeline map, under the next tab.
The sequence, and why the order is not optional
Coupling hygiene. Collapse the 31,360 duplicate sets, add @@unique([paperId, label]), then reuse an existing set instead of creating one. About 4 h. Mutates staging, so it needs a stated go. Do not reach for the runId variant — it was considered and rejected, because it makes each re-run legitimately distinct, which is the behaviour being stopped.
Acquisition blockers. The 2.5 h list. Unblocks new papers reaching R2 and staging.
Extraction. Run v2 recency-first on the 1,405 papers from 2025–26, emitting ConditionSet rows at sync time. (The three-pass extractor’s two bugs are unfixed and stay that way: it is not the extractor of record.)
Vectorize. Abstract backfill, then the chunk table.
Gates, then automation. Wire coupling-completeness.ts and the fixture recall check as pass/fail, then land the GitHub Actions DAG.
The order is not optional because a large extraction run on the current backfill reproduces the 24,540 orphaned condition sets of the 807-paper run at ten times the scale.
The extractor of record
Backlog is the 8,743 legacy papers whose rows carry no inline conditions; no backfill can ever couple them, so they must be re-extracted. Decided 2026-09-10 (PR #902): arm B — v2’s flat transport with the v1.2 sub-prompt families ported onto it as separate flat calls — run recency-first so 2025–26 lands before the backlog. Measured on a 20-paper slice: 95% precision [92–98], 62% modelable, $0.05 per paper, and 0 of 109 values sourced from other papers’ reference lists, where v2’s current prompt sourced 99 of 214. The three-pass variant, CMA v3 for bulk and the v1.2 orchestrator are decision history, not options. One caveat could reverse it: the gold set is LLM-adjudicated, not human-verified.
Coupling: the one-line version
41,080 ConditionSet rows describe only 9,720 real (paperId, label) tuples, and 27,419 sets have no linked output at all (staging, 2026-09-08). The backfill re-mints a fresh generation on every run because the unique key names a runId it never sets. The approved fix, in order: collapse the duplicates, add @@unique([paperId, label]), then reuse an existing set at sync time instead of creating one — about 4 h, mutates staging, so it needs a stated go. Setting runId was considered and rejected: it makes each re-run legitimately distinct, which is the behaviour being stopped.
The measured table, the coupling diagram, the five-step fix table and both root causes with their file and line numbers are in Part II · 07 Coupling.
Two systems share the word “experiment”
The platform is really about one thing: a complete experiment record — a design, a full set of conditions, and a co-measured outcome — not a paper. But the schema holds two separate systems under that name, and conflating them is the fastest way to misread this section. The corpus-derived half is ConditionSet plus ExtractedParameterData, everything measured above: one row per condition a paper reports, extracted at scale, coupled by conditionSetId. The user-authored half is Experiment, Run, and Measurement — a personal lab notebook for a signed-in researcher, entirely unrelated to paper extraction, with no shared code path. Everything above this point in this section is the first system.
The shape of that coupling — one paper, many condition sets, each carrying zero or more extracted values — is drawn once, in Part II · 07 Coupling.
The user-facing surfaces: real, but a different feature and hard to find
apps/web/src/app/[lang]/experiments/[id]/page.tsx and apps/web/src/app/[lang]/runs/[id]/page.tsx are genuine server components — they call prisma.experiment.findUnique / prisma.run.findUnique directly, with force-dynamic, and render real rows, not mocked data. But they read the user-authored trio above, not ConditionSet. There is no listing page for either route, and the only inbound link anywhere in apps/web/src is one card on /projects/[id], which itself requires a signed-in session scoped to that user's own projects. There is no page anywhere in apps/web that lets a visitor browse the corpus's coupled experiment records — that story lives only in coupling-completeness.ts script output and the onboarding docs.
prisma.run.findUnique + Experiment; dumps inputs/outputs as raw JSON
cards on /experiments/[id]
real, no schema-aware rendering
The corpus-wide coupling story on this page — 1,760 complete records, the two bugs above, the class-median result at 14 — has no dedicated UI at all today.
13Priors & predictions · Hierarchical, log-scale, routed through a physics family
The priors turn a pile of comparable measurements into a defensible expectation with honest uncertainty. They are hierarchical, fitted on the log scale, and sampled with NUTS. A prediction is not a prior look-up: it routes to a physics family, draws the base estimate from the hierarchical prior, then passes through a calibration layer.
Power density, current density and resistance are log-distributed across orders of magnitude, so their arithmetic mean is dominated by a few large values and is not a sensible estimate. The earlier v0 approach — analytic method-of-moments — was retired in May 2026 as mathematically wrong for these metrics, not merely imprecise. Everything is now fitted on the log scale.
Partial pooling: sparse classes borrow strength
A shared hyper-prior sits above every system-type estimate. Classes with abundant data stay close to their own evidence; sparse classes are shrunk toward the global expectation rather than over-fitting three noisy points, and the amount of shrinkage is learned from the data, never assumed. Full pooling would erase real between-class differences — an MFC and an MEC are not the same device. No pooling would hand each sparse class a model built on too little data to trust. The hierarchy interpolates by the evidence, so priors degrade gracefully on rare classes instead of returning confident nonsense.
The three prediction steps
Step 1
Route
Dispatch by system class into one of the 5 physics families (02). Subtypes are features, not branches; combinations are coupling rules, not new predictors.
Step 2
Draw
Take the base estimate from the hierarchical log-normal prior for that metric in that class.
Step 3
Calibrate
A split-conformal layer widens or tightens the interval until stated coverage matches observed coverage on held-out data. It makes no distributional assumption — it measures its own errors and adjusts.
What a prior record contains
Field
Meaning
mu_log, tau_log
Fit-scale location and precision on the log scale
mu
Back-transformed central estimate
ci95_low / ci95_high
Back-transformed 95% credible interval
scale
log or linear — how the metric was modelled
R-hat, ESS, divergences
MCMC health diagnostics, per stratum
Read via GET /api/parameters/[slug]/hierarchical-prior. Always check the diagnostics on sparse strata: a wide interval with R-hat ≈ 1.0 is trustworthy uncertainty; a tight interval built on three data points is not. A condition fitted as an outcome produces R-hat ≈ 3 and ESS 2 — the failure mode the July modeler agent found (15).
The output contract
Every numeric output ships this shape
{
"value": 512,
"unit": "mW/m^2",
"ci_low": 180,
"ci_high": 1450,
"confidence": 0.62,
"source": "hierarchical_prior_v2",
"data_status": "ok"
}
Including where it came from. Two refusal states are deliberate: insufficient_inputs means the routed class does not have enough evidence to answer; awaiting_artifact means a computed input is missing. A fabricated confident number is worse than an honest gap, so the engine returns the gap.
Two live priors artifacts coexist — refit them together
v2, a Student-t per-class stratified fit, is the served production model behind the main prediction API.
v1, a pooled log-normal fit, still backs the parameter-detail pages, the wastewater overlay and the DB-mirrored prior path.
Refitting only one leaves the other stale — the fifth harmonization hard rule in 08. The 2026-07-21 batched refit produced 102 params, 202 strata, 58 converged, 89 LOO-reliable; 8 large-N slugs timed out at 180 s each and are omitted from served v2. The v1 parameter-detail path still has no serving gate.
The published coverage figure was computed on a split that does not hold
The public methodology page reports 97.98% out-of-sample coverage across seven strata (n = 940), MFC + MEC only. That number was computed on the stored fit_validation_role split, which 14 Held-out error shows a classifier can separate from design covariates alone — so it is not a held-out result. Treat it as unmeasured until the benchmark is re-run. The audit itself, its adversarial AUCs, and what every model scores on a paper-disjoint split are in 14.
Treat a prediction as a prior to be updated by your own data, not as ground truth. For a novel design the interval will often span an order of magnitude — and given a corpus CoV near 1,285%, anything narrower would be dishonest. Stated limitations from the public page, worth carrying here: extraction success is not currently measured; the Gemini fallback over-assigns OTHER (about 52% versus about 14% on Haiku); holdout validation covers MFC + MEC only; canonical mapping sits near 51.6% on that page’s count against 45% measured on staging 2026-09-07 (08); the physics layer is a 0-D mean function and the calibration is plain split-conformal.
14Held-out error · What every predictor scores on paper-disjoint data
Measured 2026-09-02 on the local corpus, read-only, branch feat/bes-benchmark-v1 (not merged into development or main as of 2026-09-08; the package lives at services/ml-engine/training/benchmark/ on that branch only). The first paper-disjoint, leakage-audited held-out set for BES performance prediction. The result is a clean negative. Markdown port: docs/onboarding/held-out-benchmark.md; visual companion: the bes-benchmark-v1 artifact.
×6
typical held-out error on power density, every model and baseline alike
0.80 dex median |error|
0 of 4
targets where any model passes the ≥10% RMSE-reduction gate vs the class median
M1 −3.2% · M2 −6.0% · M4 −21% on power
96.7%
rows the served physics predictor cannot score — it needs an HRT the paper never reported
3,463 of 3,593 · HRT alone missing on 959
0%
coverage of the served ±25% band on power density where it predicts at all
19% on COD removal
89–91%
coverage of the served priors' 90% band — the one honest interval
4.1 decades wide on power
Target
Transform
Rows
Papers
Within-paper SD
Between-paper SD
B1 class×domain median (the bar)
Best model
power_density_areal
log10 W/m²
1,037
305
0.61 dex
1.10 dex
0.80 dex
M1 0.81 · M2 0.81 (fail)
current_density_areal
log10 A/m²
911
242
0.61 dex
1.16 dex
0.78 dex
B2 0.72 · M2 0.82 (fail)
coulombic_efficiency
logit
600
190
0.96
2.04
1.19
M2 1.10 (fail)
cod_removal
logit
1,045
291
0.86
1.35
1.06
B0 0.94 · B2 0.99 (fail)
3,593 rows from 590 papers after eight recorded filters (7,336 → 6,884 vintage v2/curated → 6,466 verifier not failed → 5,338 not cited from another paper → 5,281 no physics/dedupe flags → 5,023 BES not review → 4,965 physical bounds → 3,593 exact duplicates removed). Three splits pass the paper-level adversarial audit (hash 0.46–0.53, group 5-fold 0.41–0.62, temporal ≥2024 0.43–0.58); the stored fit_validation_role split leaks on every target (0.77–0.92). Between-paper spread is roughly twice within-paper, so there is explainable variance; the covariates the corpus holds (temperature 49%, pH 44%, anode material 74%, HRT 6%, inoculum 0%) do not explain it.
The claim versus the file
Artifact
What it says
What it actually is
calibration.json (live, 2026-07-22)
517 rows · 95.9% coverage · ECE 0.036
A random row-level 80/20 split of a 7-feature RandomForest. Papers straddle train and test. Its own power-density test R² is −3.7 × 10⁶. σ is re-estimated from the same held-out residuals, then pooled across volts, ohms and W/m², so the coverage is close to tautological.
“372 held-out, ECE 1.96%”
quoted on 6 surfaces
No such file. The lab app bundled a third vintage (377 rows) at build time, so lab and web showed different numbers for the same concept.
fit_validation_role split
97.98% OOS coverage · 940 obs
Not exchangeable. A classifier on design covariates alone tells fit papers from validation papers at AUC 0.77–0.92 against a permutation null ≈ 0.50. Every May coverage, conformal and PSIS-LOO number was computed on it.
Served 95% interval /api/ml/predict
“calibrated”
A hard-coded ±25% band multiplied by a conformal q̂ fitted to a different model’s residuals. The version-drift warning fires on 100% of responses, correctly.
The split audit — adversarial AUC per target
A LightGBM classifier on design covariates, one vector per paper, 5-fold. 0.5 is exchangeable; above 0.65 the split leaks. The stored split leaks on every target; the three benchmark splits sit at the null, which is what makes them usable.
Split
power
current
CE
COD
Verdict
stored fit_validation_role
0.899
0.920
0.770
0.845
leaks on all four
hash split
0.519
0.470
0.464
0.531
at the null
group 5-fold
0.600
0.618
0.412
0.602
passes
temporal ≥ 2024
0.429
0.524
0.580
0.491
passes
The scorecard: every model ties the class median
Gate: a ≥10% RMSE cut against B1 (the median of training papers in the same system class and application domain), with disjoint CIs, on both paper-disjoint splits, direction-correct on 2024+. Median absolute error, group 5-fold out-of-fold, paper-grouped bootstrap CIs.
Model
power
current
CE
COD
M1 · LightGBM, 35 design covariates
−3.2%
−1.5%
−4.0%
+1.5%
M2 · class median + residual GBM
−6.0%
−4.0%
−2.8%
−0.9%
M4 · RidgeCV, one-hot + imputed
−21%
−33%
−24%
−8%
Same gate, one peak value per paper
fail
fail
fail
fail
B1 · class×domain median (the bar)
0.795 dex
0.784 dex
1.194
1.056
B2 · served priors v2
0.831
0.719
1.199
0.989
B3 · served physics, where it can predict
0.462 n=15
—
1.953 n=22
1.306 n=58
Top GBM gain features are substrate concentration, publication year, reactor volume and electrode area at 9–18% each — no physical driver dominates, and publication year appearing at all is a tell. The covariates the corpus holds for these rows are thin: temperature 49%, pH 44%, anode material 74%, HRT 6%, inoculum 0%.
Intervals: only the priors’ band is honest, and it is four decades wide
Interval
coverage: power
current
CE
COD
mean width (power)
B2 · served priors v2
0.894
0.901
0.915
0.822
4.10 decades
B1 · residual band
0.882
0.846
0.867
0.856
4.02
M3 · conformal quantile regression
0.913
0.919
0.895
0.873
4.43
served ±25% band
0.000
—
0.000
0.190
0.22
Target coverage is 0.90. Coverage is bought with width: a 4-decade band on power density spans 0.0001 to 10 W/m². M3 is never narrower than the class-median band. The served band is narrow and wrong.
The served predictor abstains on 3,463 of 3,593 rows
predictForSystem requires temperature, pH, HRT and COD. It predicted on 118 rows (3.3%); 3,463 returned insufficient inputs and 12 were an unroutable class or unit. The top missing-input combinations: HRT alone on 959 rows, all four on 482, pH + HRT on 453, temperature + HRT on 412, temperature + pH + HRT on 344, HRT + COD on 247 — 15 combinations in all. HRT is the binding one, and batch reactors do not have one. The old skill harness filled the gaps with 30 °C, pH 7, 12 h and 1000 mg/L; the benchmark does not, which is why the abstention is visible for the first time.
What “state of the art” means from here
Published R² of 0.95 to 0.997 for MFC power density come from within-lab random splits of one dataset — the same artefact this platform diagnosed in its own trainers, where train R² was 1.000 and out-of-fold below zero.
On a paper-disjoint benchmark the field’s number, measured here for the first time, is a ×6 typical error and R² ≈ 0 for any covariate model.
Accuracy will not move with another model. It moves when complete design → conditions → outcome tuples exist for enough papers — a targeted re-extraction, not a fit. That is the whole argument for the coupling work in 12.
The benchmark itself is the contribution; the honest product claim is calibration, not accuracy. 34 offline tests and the leakage audit ship in manifest.json; the handoff is docs/handoffs/2026-09-02-bes-benchmark-v1.md.
Next, as of 2026-09-02 (none landed by 2026-09-08)
Rewire the MFC interval: serve the priors' predictive band instead of σ = 25% of the point (conformal-apply.ts:417), and return insufficient_inputs instead of the 46-paper heuristic when design covariates are absent. The 2026-09-08 MFC commits (bf69e8a49, 4aa9cb2e3, 6a81c5840) fixed material-slug resolution and the null contract, not the interval.
Re-run run_benchmark_v1; the served band should then cover ~90% instead of 0%.
Score the four expert datasets tagged holdout_set as an external test.
Smoke a targeted re-extraction of full tuples on 20 papers before spending on the corpus (decision taken in streamlined-corpus-run.md stage 7; not yet run).
Since 2026-09-02 on the same branch: a within-study contrast census (2026-09-07, staging, read-only) found 18 factor × outcome pairs clearing 10 papers; continuous vs batch operation raises current density ~0.47 dex and power ~0.40 dex in 80–83% of papers, and raising R_ext lowers current density in 8 of 9 papers — the physics direction cross-paper models never recovered. Do not conflate with the separate cohort benchmark export (scripts/derived/build-benchmark-export.ts, regenerated as schema 2.0 from staging in PR #862 on 2026-09-08), which feeds /methodology#schema.
15The week the diagnosis moved upstream
Three Claude Managed Agents ran for the first time, then at corpus scale. Each proved from its own direction that the platform's problems sat upstream of everything being tuned. Click any dot for the detail; bold-ringed dots are the ones to know.
Observations coupled to a condition set
13.6%100%
1,343 of 1,343 · overnight sweep d4fa68922
pH values physically impossible
80.8%0
4,630 of 5,732 → 0 of 60 papers
Outcome priors converged, real gate
12 / 120 / 71
the modeler corrected its own brief
Strata served as "95% CI"
13527
75 withheld · serving gate #736
Product-source type errors
862395
gate was false-green before #735
Cost of the overnight sweep
$70.68
60 deep-extracted · 1,400 screened
Corpus agentsCorpus dataServing & priorsGates & hygieneknow this one
The causal chain (CORPUS-DIAGNOSIS.md §4)
regex extraction (86%) + no layout model (99.5%)
→ conditions indistinguishable from outcomes (63% of "observations" are conditions)
→ condition_set_label 13.6%, uncertainty 2.4%, replicates 1.1%
→ no within-paper contrasts → 9/10 effect targets non-viable
→ conditions modeled as outcomes → 11 degenerate priors (R-hat ~3, ESS 2)
→ /meta-analysis renders nearly every forest row "not converged"
→ /collab/korth ships 135 priors, 1 converged, to an external collaborator
The schema was never the problem.conditionSetId, uncertaintyPlus/Minus/Type, derivationMethod, bbox all existed. They were unpopulated.
every outcome tied to the condition set it was measured under; chases reference-electrode convention and substrate basis
orphan outcomes declared, never guessed; writes drafts, never the DB
modeler
outcome vs condition vs context; merge slugs onto the 687-row vocabulary; serve / withhold
"do not soften the gate"; found omnibus_pass rewards vacuity
Sessions run server-side; IDs in EXTRACTION-LEDGER.csv; outputs under docs/corpus-screening-agent/run-0N-*/. Agents hold no credential — presigned URLs only, because vault placeholders cannot sign SigV4.
16Roadmap · Twelve months, six pillars, one brewery
8 Sept 2026 to 27 Aug 2027, in three phases and eighteen workstreams, each with dated deliverables. The roadmap is organised around one first-of-a-kind brewery installation; every other pillar either feeds it or funds it.
Gate: funding event OR 2 paid feasibility studies signed · solo → first hire
P2
Build & validate · 3 May 2027 – 27 Aug 2027
Gate: wet-lab partner signed · 1–3 hires
Two dates are hard. The Villano meeting, with the ISMET president, sits at roughly 15 Oct 2026. The P1 gate, a funding event or two paid studies, falls on 19 Dec 2026.
F1 Funding + runway · F2 Legal / IP / data licensing · F3 Team + hiring
The crunch
The crunch is the five weeks to 10 Oct 2026: A1-M1, A1-M2, A1-M3, A3-M1, B1-M1, B2-M1, B3-M1, C1-M1, C1-M2, C2-M1, D1-M1, D2-M1, D2-M2, E1-M1, F1-M1, F2-M1. A1-M3 and B1-M2/M3 slip first if something has to.
Where this connects: 12 Corpus run above is workstream B1's ground truth. Its measured coupling and acquisition state is what B1's milestones are scheduled against.
17Open gaps · Ranked, dated, and what unblocks each
Two views of the same backlog. The first is by area, drawn from the onboarding docs; the second is the platform’s own P0 to P2 ranking — P0 blocks the corpus machine, P1 bounds what can be modeled or served, P2 is hygiene. Both are dated. Nothing here is a wish list: every row names what unblocks it.
The backlog, ranked
One register. P0 blocks the corpus machine, P1 bounds what can be modelled or served, P2 is hygiene; rows marked — are known gaps that have not been ranked against the others yet.
Sev
Area
Gap
Current state
What unblocks it
P0
acquisition
Acquisition stalled since 2026-05-09 (as of the 2026-09 audit)
Five blockers keep weekly_pipeline.sh from completing; of the 1,405 papers from 2025–26 only 322 are PDF-backed (23%). 2026-09-08
Fixes 5–7 landed 2026-09-10 (R2 push + hydrate, PDF triage, --input-format pmc-xml). Remaining: a real recency-first run with R2 and DB credentials.
P0
coupling
Coupling backfill mints duplicate ConditionSets
41,080 rows exist; only 9,720 are real. The backfill has no runId, so it re-mints sets it cannot recognise as present. 2026-09-08
Code landed (#893: collapse-duplicate-condition-sets.ts, unique-key migration, reuse at sync). Remaining: run the collapse and migration on staging, then prod. Do this before any large run.
P0
pipeline
Extraction and acquisition are not scheduled
weekly_pipeline.sh and simple_value_extractor.ts run by hand; corpus-refresh.yml is a 2026-05-30 design with no code. Only refits run weekly.
Land the GitHub job-DAG, or a scheduled routine step for discover → acquire → extract with the budget cap.
P1
ontology
Canonicalization coverage, not extraction, bounds modelability
55% of EPD rows have a NULL canonical slug on staging (80.7% when first measured on local). Modelable 31,924 against a ceiling near 40–50k.
Extend the alias maps and canonicalize-name.ts; re-run refresh-all steps 2–3.
P1
pipeline
Section-chunk vectors live on disk only
embed.py writes chunk vectors to disk; no DB table holds them, so nothing served can search full text. Abstracts cover 13,788 of 23,579 (58%; historic staging count of every paper row). 2026-09-08
The chunk table landed (migration 20260910120000_add_paper_chunk_vectors). Remaining: the embedding backfill.
P1
schema
Two geometry tables not unified
ReactorGeometry (~47 typed columns) feeds the resource-recovery demo and quality scripts; the paper 3D route reads ExperimentalContext + ConditionSet. 2026-09-08
Pick one as the source of truth and make the other a view over it.
P1
schema
Papers ↔ Materials / Microbes orphaned
anodeMaterials and cathodeMaterials are strings; the PaperMaterial and PaperMicrobe junctions are mostly empty.
Backfill the junctions from extraction. The read routes exist since 2026-10-02: /api/materials/[id]/papers and /api/microbes/[id]/papers (match on canonicalId; MaterialPaperCrossref is not merged in).
P1
pipeline
Unread corpus
1,444 BioC-PMC XML files parsed but never re-extracted (~$70–150); 2,075 no-DOI papers unreachable; MDPI, Wiley, ACS and Elsevier 403s.
A cost-gated v2 run over the XML; the curl_cffi path for no-DOI URLs.
P1
ui
Confidence and integrity caveats are not surfaced
The parameter detail page now carries an “Honest framing” block citing the CoV and SCIENTIFIC_INTEGRITY.md, and v1 prior intervals are gated (see below). The parameter API responses still carry no aggregate confidence.
Add confidence to the parameter responses; a collapsible callout on the parameter pages.
P1
priors
GP-SCM fits are data-limited, and can be silently dark in prod
12 of 27 MFC nodes fitted; new fits are interpolation artifacts (energy_efficiency flat at 43.02%), toc_removal has one joint observation. A blank GP_SCM_SERVICE_URL disabled the pillar for about seven weeks in July 2026 while it looked wired.
Targeted paid re-extraction for the biofilm and biomass nodes — do not lower --min-samples. Check the Vercel env on messai-api.
P1
pipeline
Weekly routine output never landed
No npe-health.json exists anywhere in the tree, so either the routine has never run with --commit or its commit step has not fired.
Run weekly-ml-audit.sh --commit once by hand, then confirm the scheduled session exists.
P1
schema
Prod FK under-population
About 33k ExtractedParameterData rows in prod lack parameterDefinitionId, which affects FK and DAG read paths, not the modelable count.
A feedback widget posting to the predictions route; weekly regeneration when drift exceeds 5%.
P2
chat
Chat tools missing for four packages
queryDatasets (catalog.json) and queryMethods (the hunter physics-violation flags) landed 2026-10-02. mess-hypotheses holds only synthetic generators and mess-learning holds unsourced figures, so neither is wrapped.
One tool per package in @messai/ai-chat.
—
infra
No rotation runbook for R2 keys or the Supabase service-role key. Rotating R2 revokes every presigned URL at once.
not yet ranked
a decision on cadence and owner
—
pipeline
~1,354 screened-in papers still unextracted; full backlog ≈ $929 Opus / $368 Sonnet vs a ~$100 envelope.
not yet ranked
an explicit go
—
pipeline
Agent drafts sit as PENDING; nothing promotes them. The review queue now reads and writes ExtractedParameterData.validationStatus (approve/reject, 2026-10-02); validation/[itemId], export, jobs, metrics and user-activity under admin/extraction still read the missing paper columns.
not yet ranked
a review-queue UI
—
extractor
The v2 system_class prompt taught the legacy 30 buckets while the enum was the canonical 17; 14 of 18 types got no per-class guidance (the lookup missed, and the prompt template printed the missing value as the word “undefined”). Fixed 3d89f2901, 2026-09-08, 5-paper smoke passed.
not yet ranked
re-extract the classes affected before the fix; the MEC smoke paper a5ccb99a still fails on both code paths
—
taxonomy
Screener verdicts (topic / doc_type / cull) never reach the DB; Tier 3 human review has columns but no writer; 688 papers flagged taxonomyNeedsReview.
not yet ranked
the loader exists (scripts/db/load-cull-manifest.ts, dry run by default); smoke 5 rows on staging, then apply
—
taxonomy
Three parallel system-type columns (primarySystemType, systemType with 8 indexes, v1_1_primary_system_type with no writer); benchmark export reads the frozen one first.
not yet ranked
a migration that collapses to primarySystemType
—
ontology
The pinned parameter-definitions-rich.json (825) is 10 definitions behind staging (835), so the per-slug fixtures, the npm package and the 826-node KG snapshot are stale. 29 slugs with no definition (membranematerial, cathodematerial, anodematerial, maxpowerdensity, mode, design …) carry over 10,000 rows with no unit, range or FK.
not yet ranked
re-export rich.json, regenerate fixtures + snapshot; add or alias the 29 orphan slugs
—
agents
Presigned-URL expiry blocks a scheduled v3 deployment.
not yet ranked
run-time minting or per-run attachment
—
acquisition
weekly_pipeline.sh now pushes new PDFs to R2 (2026-09-10) and the skill lists all 9 providers (2026-10-02); neither has run end to end on a fresh batch.
not yet ranked
fix 5 of the 2.5 h list; a one-line skill edit
—
priors
The v1 parameter-detail route now runs the same serving gate as /api/ml/predict (2026-10-02), but its validation never pairs with the served fit, so it gates on fit quality only. 8 large-N slugs omitted from served v2 at the 180 s timeout.
not yet ranked
named follow-ups from #736 / 1e77b1b3d
Resolved since the docs were written — verify before re-flagging
Type gate false-green: check-cross-package-imports.sh now fails on dangling node_modules symlinks, on a tsc that crashes or is missing, and on a run that loads too few app source files; each case was shown to fail (2026-10-02).
BullMQ scaffold archived to archive/2026-10-bullmq-scaffold/; bullmq/ioredis dropped from apps/api (2026-10-02).
Methodology pages describe the v2 extractor (203549b7, 70991c3c; the last lab metadata strings 2026-10-02).
NextAuth: only @next-auth/prisma-adapter is installed; @tanstack/react-query is only used by a test util, so devDependencies is correct.
fra1 region pinned in apps/api/vercel.json; the session-artifact backup script imports the apps/api R2 client (2026-10-02).
EXTRACTION-LEDGER.csv reconciled from disk by refresh-ledger.py: 178 extracted, 2 missing_output (2026-10-02).
bes-benchmark-v1 merged with the calibrated MFC interval (0ed50246, #891).
ProcessFlowDiagram.tsx is marked as deliberate deck artwork, not a P&ID; engineering drawings stay in @messai/pid-schematic.
Chat bifurcation: one canonical /api/chat (2026-05-12).
Priors JSON validity: v1 and v2 both parse cleanly (715b63e96).
Per-class ML routing: six non-MFC classes route to the analytical predictor (4778f8589, bef7acedd). The lab UI still passes proxy inputs.
Harmonization quick wins merged (PR #501): +434 modelable, propagated to staging and prod 2026-07-06/07.
Legacy extractors already read ANTHROPIC_MODEL with a sane default — that 2026-05 item is closed.
Source docs: docs/onboarding/README.md · infra-access-r2-staging-prod.md · paper-pipeline.md · docs/handoffs/2026-07-19-24-corpus-agent-work.md · docs/corpus-screening-agent/CORPUS-DIAGNOSIS.md. Generated 2026-09-07; section 17 re-verified against the code 2026-10-02.
18Glossary · Every term this page uses, in one place
Science terms are as defined on messai.io/learn/science; platform terms are as used in the repo. Where a term means two things, both senses are given — that ambiguity has cost time before.
BES
Bioelectrochemical system — the umbrella term for any device where microbes (or enzymes) catalyse redox reactions at electrodes wired to an external circuit.
MES
Two senses. As an umbrella: microbial electrochemical system, the whole field. In the extraction schema and primarySystemType: Microbial Electrosynthesis, cathodic CO₂ reduction — one of the 14 devices.
EET
Extracellular electron transfer — how bacteria move respiratory electrons onto an electrode, by direct contact, conductive nanowires, or soluble mediators.
DIET
Direct interspecies electron transfer — electrons passed directly between species through pili or conductive minerals; the basis of syntrophy and electromethanogenesis.
Anode / cathode
The oxidising electrode, where the biofilm gives up electrons, and the reducing electrode, where they are consumed.
Overpotential (η)
Voltage beyond the thermodynamic minimum needed to drive an electrode reaction at a useful rate. Split into activation, ohmic and concentration terms.
Exchange current density (j₀)
How intrinsically fast an electrode reaction runs at equilibrium — higher is better.
Tafel slope
The slope of overpotential against log-current in the kinetically-limited region; encodes the transfer coefficient.
Limiting current
The maximum current a diffusion-limited reaction can sustain, reached when surface reactant concentration falls to zero.
Coulombic efficiency
Fraction of the electrons available in the substrate that are actually recovered as current. Bounded 0–100% and diagnostic of electron leakage.
Power density
Power normalised to electrode area (areal, mW/m²) or reactor volume (volumetric, W/m³). Keep the two apart — they are separate canonical kinds.
Monod kinetics
Saturating relationship between substrate concentration and microbial growth or uptake rate, set by μ_max and the half-saturation constant K_s.
EIS / Randles circuit
Electrochemical impedance spectroscopy, and the equivalent-circuit fit that separates solution resistance, charge-transfer resistance, capacitance and diffusion.
Physics family
One of 5 groupings — anodic oxidation, cathodic reduction, ion transport, selective reduction, sensor/photo — that predictions route through. A calibration and out-of-distribution stratum, not a predictor.
Canonical slug
The normalised identity a free-text parameter name is mapped onto so values from different papers can be compared and pooled. Layer 2 of the five-layer value ontology (09).
Kind
Layer 3: the SI quantity a slug belongs to (SLUG_TO_KIND). A slug outside it is never SI-normalised and never modelable. This, not the category, is the modelable gate.
ConditionSet
The within-paper coupling record that binds an outcome to the operating point it was measured under. Without it a number has no context.
Experiment record
The atomic unit for modeling — not the paper. Grading a paper as complete says almost nothing about whether any single experiment inside it can be modeled.
Hierarchical prior
A Bayesian prior that pools information across system types so sparse classes borrow strength from data-rich ones, with the shrinkage learned rather than assumed.
Conformal calibration
A distribution-free method — here, plain split-conformal — that adjusts prediction intervals so stated coverage matches observed coverage on held-out data.
ECE
Expected calibration error — how far stated interval coverage drifts from observed coverage. Lower is better.
CoV
Coefficient of variation, standard deviation over mean. For power density it is ≈ 1,285%, which is why point estimates are meaningless without an interval.
dex
A decade on a log₁₀ scale. A median absolute error of 0.80 dex is a typical miss of about ×6.
Adversarial AUC
The score of a classifier trained to tell a train split from a test split using covariates alone. 0.5 means exchangeable; above 0.65 the split leaks and every metric computed on it is optimistic.
resolveDbTarget()
The only sanctioned way to resolve a remote database, gated on the Supabase project ref rather than the hostname — staging and production share a pooler host, so a hostname check proves nothing.
Physics families vs. system types
17 primary system types (14 devices + 3 meta classes) exist in the taxonomy; predictions route through 5 physics families. Branching on all 17 would train rare classes on a handful of papers each.
19Units & normalization · Every unit the corpus accepts, and what it becomes
A value keeps the unit its paper printed. Before it can feed the priors, scripts/quality/normalize-to-si.py routes its slug to a quantity kind, cleans the unit string and converts it to that kind’s one canonical unit — or holds it out and writes why. Everything below is generated from that script (pnpm generate:units-glossary, rerun on every commit that touches it), so it states what the pipeline does, including what it refuses to convert. The same reference is the last section of the Glossary tab on messai.io/methodology and /parameters.
The value in its kind's canonical unit, written by the normaliser, with whether the priors may use it and, if not, why.
How a value is normalised
Route. The canonical slug picks a quantity kind (SLUG_TO_KIND). A slug with no kind is not touched: it keeps its raw value and never reaches the priors.
Split by unit.route_kind() moves a density reported per volume (W/m³, A/m³, mA/L) to its volumetric kind, and a resistance reported per area (Ω·cm²) to the area-normalised kind. Areal and volumetric values are never pooled.
Clean the unit string. Case, superscripts, Unicode minus signs, µ and Ω are folded (examples below).
Convert. The cleaned unit is looked up in the kind's table and the value is multiplied by its factor; kelvin is the one offset. A unit missing from the table is not converted.
Gate. The row is marked modelable unless an exclusion reason applies. Held out is not deleted: the converted value stays queryable.
Unit-string cleanup
Before the lookup the unit string is trimmed, MΩ and MW are spelled out as megaohm and megawatt (lower-casing would turn mega into milli), and the string is lower-cased. Unicode minus signs and dashes become -, superscript digits become digits, µ and μ become u, Ω becomes ohm, a middle dot becomes a space, and every spaced negative exponent in a chain becomes a slash (mg L⁻¹ d⁻¹ → mg/l/d). The digit of -2 and -3 is kept, so areal and volumetric units stay apart.
Three limits remain. Case is folded for every other prefix, so ML (megalitre) would be read as mL. A dot between units is not a separator, so mA.m-2 converts only because that spelling is listed. And a unit written the wrong way round, such as Ω cm⁻² for Ω·cm², finds no factor and stays unconverted. megawatt has no factor on purpose: no MES reactor reports one, so such a value is held out.
Quantity kinds
Every kind with its canonical unit, each unit spelling it accepts (as matched after cleanup) with its factor, and the slugs routed to it. The field is named si_unit, but the canonical unit follows MES reporting practice: SI for most kinds, and °C, h, L, mg/L or kWh/m³ where the literature reports in those. A kind served in another unit (in API responses, pages and exports) says so under its canonical unit.
41 of 41 kinds
Kind
Canonical unit
Accepts
Slugs
power_densityareal power density
W/m²watts per square metrewatts per square metreServed in mW/m²
kWh/m³kilowatt-hours per cubic metrekilowatt-hours per cubic metre
kwh/m3 ×1
wh/m3 ×10⁻³
kj/m3 ×2.778·10⁻⁴
kwh/kg · not converted
j/m3 ×2.778·10⁻⁷
2 slugs
specific_energy_consumption, energy_consumption
iecion exchange capacity
meq/gmilliequivalents per grammilliequivalents per gram
meq/g ×1
mmol/g ×1
eq/kg ×1
1 slug
ion_exchange_capacity
power_density_volumetricvolumetric power densitySplit from power_density by unit
W/m³watts per cubic metrewatts per cubic metre
w/m3 ×1
w/m^3 ×1
mw/m3 ×10⁻³
mw/m^3 ×10⁻³
kw/m3 ×1,000
w/l ×1,000
mw/l ×1
uw/ml ×1
2 slugs
power_density_volumetric, volumetricPowerDensity
current_density_volumetricvolumetric current densitySplit from current_density by unit
A/m³amperes per cubic metreamperes per cubic metre
a/m3 ×1
a/m^3 ×1
ma/m3 ×10⁻³
ma/m^3 ×10⁻³
ka/m3 ×1,000
a/l ×1,000
ma/l ×1
1 slug
current_density_volumetric
resistance_area_normalizedarea-specific resistanceHeld out of the priorsSplit from resistance by unit
Ω·m²ohm square metresohm square metres
ohm m2 ×1
ohm m^2 ×1
ohm cm2 ×10⁻⁴
ohm cm^2 ×10⁻⁴
No slug of its own: reached only through route_kind()
The normaliser processes the v2 extraction cohorts, and the v1 ones on request. Rows it has not processed can carry si_unit strings left by older canonicalisers; the units in this table are the only ones it writes.
Rules that are not a factor
Rule
What happens
Areal vs volumetric
On a power or current density slug, a unit containing /m3, /m^3, /cm3, /cm^3, /l, /ml, /ul is volumetric. It converts to W/m³ or A/m³ under its own kind and is held out of the priors, which pool by slug. An areal unit on a volumetric slug is a basis conflict: neither converted nor re-slugged.
Area-normalised resistance
Ω·cm² and Ω·m² measure something different from Ω. They convert to Ω·m² under their own kind and are held out of the priors.
Percent and fraction
Efficiencies and removals are stored as a fraction from 0 to 1, not as %. A value above 1.5 whose unit is "", fraction, dimensionless, ratio is read as a percentage and divided by 100.
Temperature
The canonical temperature is °C, as MES papers report it, not kelvin. Kelvin (k, kelvin, °k, deg k) is the one offset: -273.15 is added, not multiplied.
Electrode potentials
For anode_potential, cathode_potential, applied_potential, appliedPotential, electrode_potential, redox_potential, oxidation_reduction_potential, oxidation-reduction_potential, standard_potential, a value stays modelable only on the SHE scale, stated in the unit, the parameter name or the extracted reference. Ag/AgCl, SCE, RHE and other references are not converted: no offset is applied until the offsets are signed off. A potential with no stated reference is held out.
Recognised, not converted
Some units are listed on purpose without a factor, because converting them needs something the row lacks: a molar mass for mM or mol/L, a basis for a per-gram or per-area rate. The kinds table marks them “not converted”.
Literature aggregates
Values whose derivation is meta_analysis_aggregate, literature_review_aggregate, cited keep their converted value but never feed the priors: a review median or a cited value is not a measurement made in the paper it was extracted from.
Exclusion reasons
Written to canonical.exclusion_reason when a row is held out; canonical.applicable_to_modeling is then false.
Reason
Meaning
unit_not_convertible:<kind>
The kind has no factor for this unit, or lists it as not converted. The si_value and si_unit keys are removed.
basis_conflict:areal_unit_on_volumetric_slug
An areal unit on a slug that names a volumetric basis. Whether the slug or the unit is wrong is still open.
kind_not_modelable:<kind>
Converted, but the kind is held out of the priors: electrode_potential, cv_potential_window, resistance_area_normalized.
potential_no_reference
An electrode potential with no stated reference electrode.
potential_reference_not_converted
An electrode potential against a reference other than SHE; no offset is applied.
derivation:<method>
A literature aggregate or a cited value; the derivation method follows the colon.
Where units are handled
File
Role
scripts/quality/normalize-to-si.py
Converts each value to its kind's canonical unit and gates modelability. The source of every table above.
libs/shared/units/src/units.generated.ts
This glossary's data, generated from the normaliser by pnpm generate:units-glossary. A test fails while it is stale.
ParameterDefinition.unit: the unit a parameter is usually reported in, shown in the parameter catalog. It is not the normaliser's canonical unit: power density is listed in mW/cm² there and stored in W/m².
libs/shared/ml/src/predictions/output-fields.ts
Maps each served prediction output to the slug and canonical unit the calibration layer uses: power from mW/m² to W/m², efficiencies from % to a fraction.
services/ml-engine/gp_scm/unit_normalizer.py
A separate normaliser for GP-SCM training, with other targets (mW/m², mA/m², % from 0 to 100). It reads a missing unit as its target unit and drops values it cannot convert.
An older canonicaliser, archived 2026-10-19. Its si_unit strings (raw units, K, words) are not the normaliser’s; scripts/quality/archive-legacy-canonical-si.py moves the ones it left to legacy_si_value / legacy_si_unit.
scripts/derived/lib/unit-normalizer.ts
Unit classes for the contradiction builder, so that an areal value is never compared with a volumetric one.
Reference-electrode offsets to SHE for the physics models. The corpus normaliser does not apply them.
These tables were written independently and do not share one canonical unit. Power density, for one, is W/m² in the normaliser, mW/m² in the predictions and the package audit, and mW/cm² in the parameter catalog. Compare values only after converting them to one unit.
Part II of VII · Running the corpus · 11 sections · ~80 min
samfrons/messai.ai · onboarding · written 2026-09-07 from source and staging counts
Corpus Run Playbook
How a batch of new papers should move from OpenAlex to modelable rows on staging, and what actually happens today.
~2.5 h
fix-first
8
runbook steps
across the 6 lifecycle stages
$10–20
per 200 papers, cheap path
00The pipeline in one page
Read this first. Every later section details one row of the table below.
The organizing fact. Every layer of the corpus pipeline already has a working component. Each one is either not wired to anything, never run, or broken by a small bug. Nothing here needs to be built from scratch. The work is to connect what exists and run it, in dependency order, with a measured gate at each step.
0a. Five layers, measured on staging 2026-09-08
These are architectural layers — where the machinery lives — not pipeline stages. The six lifecycle stages a paper passes through are acquire → screen → extract → sync → harmonize → promote; each layer below serves one or more of them.
0b. The sequence, and why the order is not optional
Each layer's output is the next one's input. Coupling hygiene comes first because a large extraction run on the current backfill reproduces the 24,540 orphaned sets of the 807-paper run at ten times the scale.
Coupling hygiene (§7): collapse the 31,360 duplicate sets, add @@unique([paperId, label]), reuse an existing set instead of creating one. About 4 h. Mutates staging, so it needs a stated go. The runId variant is the rejected fix; §7 says why.
Acquisition blockers (§2): the 2.5 h list. Unblocks new papers reaching R2 and staging.
Extraction (§3 stage 7, §5): fix the 3-pass extractor's two bugs, then run recency-first on the 1,405 papers from 2025–26, emitting ConditionSet rows at sync time.
Vectorize (0f): abstract backfill, then the chunk table.
Gates, then automation (§4d, §6): wire coupling-completeness.ts and the fixture recall check as pass/fail, then land the GHA DAG.
0c. What makes it intelligent rather than merely running
Each of these already exists in the repo. None is wired in.
Gap-driven acquisition.scripts/acquisition/search-gaps-openalex.ts reads gaps[] from within-paper-effects.json and searches for exactly the evidence the models lack.
Value-of-information ordering.scripts/quality/voi-covariate-priority.ts ranks what to extract next by expected information gain, instead of oldest first.
Experiment-centric extraction. Pass 1 of the 3-pass extractor enumerates a paper's distinct experimental conditions and emits one ConditionSet per condition with a verbatim snippet. On the two papers where it worked it found 7 and 9 conditions.
Free invariants before paid verification. On 2026-09-08 the identity μmax = ln 2 / doubling time validated three values the paid LLM verifier had rejected. Run the verifier only where a cheap invariant fails.
Canonicalize at extraction. Give the extractor the alias index so canonical_slug is proposed during extraction and verified offline, instead of matched afterwards by a script plateaued at 45%.
0d. The one decision that is yours: extraction budget
For the 8,743 legacy papers whose rows carry no inline conditions, no backfill can ever couple them. They must be re-extracted.
Extractor
Per paper
Backlog cost
Coupling
v2
$0.05
about $440
inline per-value fields
3-pass, after fixes
$0.12
about $1,050
one experiment record per condition
CMA v3
$0.93
about $8,100
100%, measured on run-03
Recommendation: the 3-pass for bulk with CMA on a 20-paper benchmark slice, recency-first so 2025–26 lands before the backlog.
0e. Agent onboarding: load these before touching the pipeline
An agent starting cold should read, in this order, before running anything.
The memory index ~/.claude/projects/-Users-samfrons-repos-messai-ai/memory/MEMORY.md, then these four entries: feedback-corpus-lives-on-staging-not-local (local Supabase is empty), feedback-grade-experiment-records-not-paper-completeness (the atomic unit is the experiment record, not the paper), feedback-dangling-node-modules-symlinks-false-green-typecheck (46 root node_modules links are dead; a passing tsc proves nothing until you have seen it fail), and project-acquisition-path-status-2026-09-07.
The skills mes-paper-retrieval, mes-parameter-extraction, mes-data-harmonization under .claude/skills/.
docs/extraction/extractor-contract-and-gaps.md for what the extractor really emits versus what the public methodology page claims.
Gates an agent must run and report before claiming a cohort is done: scripts/quality/coupling-completeness.ts (read-only, Q4 per class), scripts/extraction/audit-disk-vs-db.ts, pnpm verify:science.
Rules an agent must not cross: every remote DB write goes through resolveDbTarget() and is gated on the Supabase project ref, never the hostname; no paid extraction without a 3-paper smoke; archive, never delete; never quote a corpus number older than the last re-measurement.
0f. Vectorization, the layer no other section covers
ResearchPaper.abstract_embedding is a pgvector column written by services/ml-engine/training/embed_papers.py (BAAI/bge-large-en-v1.5) and read by apps/api/src/app/api/research/semantic-search/route.ts. On staging 2026-09-08: 13,788 of 23,579 papers carry one, 10,497 of them visible. 13,251 papers have an abstract over 50 characters, so coverage tracks abstract availability and the remaining gap is mostly papers with no abstract to embed.
Section-level chunk vectors are a different story. The open-source pipeline's embed.py writes chunks.jsonl and vectors.npy per paper to disk, and no table in the database holds them, so nothing served can search full text. Closing this is two steps: run the abstract backfill for new cohorts as part of stage 8, then add a chunk table and a promote script so the on-disk vectors become queryable. The corpus-refresh design already calls the abstract backfill the highest-value, lowest-risk first move, because it hardens the RAG layer behind the lab agent with no queue and no new infrastructure.
01State strip
Written 2026-09-07 from source and from read-only counts on staging (the canonical staging project; ref in docs/staging-access.md). Local Supabase is empty and the local PDF cache is empty; R2 holds the bytes. Re-measure before quoting any number here.
The corpus thins exactly where it should be growing. 2023 has 2,000 papers and 521 PDFs; 2025 has 1,249 and 225.
02Fix-first checklist, about 2.5 hours
Do these before the first cohort. Each one removes a manual workaround from §3. The rule for all of them: resolve the database through resolveDbTarget() in scripts/lib/db-target.ts (TypeScript) or add_target_argument() / resolve_or_exit() in scripts/quality/db_target.py (Python), gate on the Supabase project ref rather than the hostname, and make --target staging the default.
#
Fix
File
Min
Unblocks
1
Route the four fake---target scripts through resolveDbTarget(). They read DATABASE_URL_STAGING, which no env file sets, and fall through to whatever DATABASE_URL is loaded.
Add a --target passthrough to refresh-all.sh steps 2 to 5. Its four Python stages now require --target and exit 1 without it, which is why --apply is broken.
Remove --source-tag from stage 3 of the per-source pipeline. It's passed to download_curl_cffi.py, which accepts only --limit, --dry-run and --workers. Argparse exits 2 and || echo swallows it.
Make download_curl_cffi.get_database_url() consult os.environ first. Today it reads .env.development.local, then .env.local, then .env, so it cannot be pointed at staging. It is the only MDPI, Wiley, ACS, Elsevier and IWA path.
Give the PyMuPDF text stage the R2 hydrate fallback. The stage is an inline Python heredoc; marker_pipeline.py already fetches on a cache miss — copy that.
Two follow-on tweaks. Add --since and sort=publication_date:desc to scripts/discover-papers-via-openalex.ts, which hardcodes currentYear - 10 at line 253 and sorts by relevance. Make scripts/acquisition/search_openalex_underrepresented.py --insert-to-db append to papers/staging/papers-to-download.csv, so the weekly path can download what it discovers.
The resolveDbTarget() rule. Every fix above reduces to the same instruction: gate database resolution on the Supabase project ref, not the hostname — staging and prod share a pooler host — and default to --target staging.
03The run, in eight runbook steps
Eight runbook steps, not a different pipeline: they are the operational expansion of the six lifecycle stages (acquire → screen → extract → sync → harmonize → promote) named on the onboarding overview. Point the shell at staging once, explicitly, before anything else.
Point the shell at staging, once
set -a; source .env.local; set +a          # SUPABASE_STAGING_DIRECT_URL, R2_*, AI_GATEWAY_API_KEY, OPENALEX_API_KEY, UNPAYWALL_EMAIL, CROSSREF_MAILTO
export DATABASE_URL="$SUPABASE_STAGING_DIRECT_URL"
export DIRECT_URL="$SUPABASE_STAGING_DIRECT_URL"
export DATABASE_URL_STAGING="$SUPABASE_STAGING_DIRECT_URL"
unset DATABASE_URL_LOCAL                   # db_target.py refuses a non-local value here
export PAPERS_ROOT="$(pwd)/papers"
echo "$DATABASE_URL" | grep -q "$STAGING_REF"   # the staging project ref, from docs/staging-access.md || echo "ABORT: not staging"
Do not source .env.development.local or .env.production.local in this shell. Preconditions: papers/.venv with curl_cffi, paperscraper, psycopg2, pymupdf and boto3 (all present 2026-09-07; playwright and snakemake are missing), and rclone on the path.
Stage 1 — Discover
Find recent BES papers on OpenAlex and write a reviewable manifest.
Hits blocker 2: the mutation flag does not resolve a URL, so the writes land wherever DATABASE_URL points. The env block above is what makes it staging. Broad-term discovery needs scripts/discover-papers-via-openalex.ts:253 edited by hand first; it has no --since.
The third hits blocker 4 and cannot see staging. Either patch get_database_url() or temporarily point .env.development.local's DATABASE_URL at staging.
After fix 4: the same three commands, run in sequence, with no env juggling.
Cost / time
$0, 20 to 60 minutes for 100 at 0.5 s per host and 4 workers.
Proof it worked
Every cohort DOI has a line in papers/staging/download-attempts.jsonl. Read it before calling any paper unavailable. A 403 from a publisher is a TLS fingerprint block, not closed access. No Sci-Hub, no LibGen.
Stage 4 — Store
Content-address the PDFs, get the bytes into R2, register them against staging rows, then set the R2 keys.
Hits blocker 1 (no pipeline uploads to R2) and blocker 2 on the sync. Two cautions: papers/staging/resolution.jsonl is dated 2026-04-29, so DOI matches will miss and stubs named Local PDF <sha8> will be proposed — fix the SHA to DOI map before accepting them into a 23k-row corpus. And the two key-backfill scripts disagree about provenance: backfill-r2-keys.ts sets pdfSource='r2' while backfill-r2-source.ts preserves the acquiring provider. Pick one per cohort and record which.
target
After fixes 1 and 5: promote, upload and key-backfill run inside run-pipeline-for-source.sh; only the sync dry-run stays a deliberate human step.
Cost / time
$0 compute, about $0.015 per GB-month of R2 storage, 2 to 5 minutes for 100.
Proof it worked
SELECT count(*) FROM "ResearchPaper" WHERE source='<tag>' AND "r2Key" IS NOT NULL equals the downloaded count, and the sync's stub counter is 0 or explained.
Stage 5 — Text
Turn PDFs into the full.md the extractor reads. No text means no error, no output and no cost, so this stage failing is silent.
today
pnpm papers:hydrate --dry-run                     # only if reprocessing older papers
pnpm papers:hydrate
bash scripts/acquisition/run-pipeline-for-source.sh --tag recent-bes-$(date +%F) --skip-ingest --skip-acquisition
Hits blocker 5: stage 3 inside that script fails harmlessly on the bad --source-tag. Papers get PyMuPDF, not marker; marker-quality text is patent-only today, and 22 marker text files exist on disk against 1,375 values_v2.json artifacts. pdf-triage.ts classifies nothing in this path.
After fixes 3, 6 and 7: the same one-line invocation, with the R2 fallback covering an empty local cache and triage routing low-printable-ratio PDFs to needs_ocr instead of into the extractor.
Cost / time
$0, 2 to 5 minutes for 100.
Proof it worked
papers/extracted/<aa>/<sha>/marker-v1/full.md (or the legacy v0-legacy/text/full.md) exists for every cohort SHA.
Stage 6 — Screen and classify
Decide relevance and system type before paying for value extraction. A row classed OTHER or unknown is an acceptance failure, not a result.
today
pnpm tsx scripts/extraction/classify-title-abstract.ts --limit 200 --apply --i-understand-this-mutates-staging
# optional higher-resolution screen, about $1.02 per 100 on Sonnet
python3 scripts/storage/mint-presigned-urls.py --shas /tmp/new-200.txt --out /tmp/presigned.json
cd docs/corpus-screening-agent && ./launch.sh && ./poll.sh
pnpm tsx scripts/classify-system-taxonomy.ts --apply --limit=200
Hits blocker 2 on the first command. The title and abstract classifier only touches rows where primarySystemType IS NULL, so run it first and let the free regex classifier mop up the rest. Use Cerebras, not Gemini: on a 21-paper sample Gemini put papers with "microbial fuel cell" in the title into OTHER about 38 points more often than Haiku.
target
pnpm tsx scripts/extraction/classify-title-abstract.ts --limit 200 --apply --target staging
# optional higher-resolution screen, about $1.02 per 100 on Sonnet
python3 scripts/storage/mint-presigned-urls.py --shas /tmp/new-200.txt --out /tmp/presigned.json
cd docs/corpus-screening-agent && ./launch.sh && ./poll.sh
pnpm tsx scripts/classify-system-taxonomy.ts --apply --limit=200
After fix 1: the same sequence with --target staging.
Cost / time
$0 and about 8 minutes per 100 on Cerebras, plus $1.02 per 100 and one overnight if you run the CMA screener.
Proof it worked
Zero cohort rows with primarySystemType IS NULL, and papers/staging/classify-attempts.jsonl has one line per paper.
Stage 7 — Extract
Approved decision. Run the cohort through v2 Haiku in bulk, and run a 20-paper benchmark slice through the CMA Opus extractor so the quality gap is measured rather than argued.
today
pnpm tsx scripts/extraction/phase6-smoke-test.ts --n 3                          # about $0.15, do this first
pnpm tsx scripts/extraction/simple_value_extractor.ts \
  --sample-from papers/staging/recent-bes-$(date +%F)-extraction-manifest-markdown.json \
  --input-format markdown --provider gateway
pnpm tsx scripts/extraction/sync-values-v2-to-db.ts --apply --only-missing
pnpm tsx scripts/extraction/audit-disk-vs-db.ts --fail-on-gap
# benchmark slice, 20 papers on CMA Opus v3
cd docs/corpus-screening-agent && ./launch.sh && ./poll.sh
The extractor writes no DB rows; the sync does, against DATABASE_URL. Pass --only-missing on an already-harmonized corpus, because the sync otherwise delete-and-reinserts every paper it walks and resets canonical_slug, si_value and conditionSetId. The CMA loader docs/corpus-screening-agent/load-all.py writes only to LOCAL_DATABASE_URL, so the benchmark slice lands locally and is compared, not promoted.
target
Unchanged for the bulk path. The benchmark path becomes one command once load-all.py grows a ref-gated --target.
Cost / time
200 papers on v2 Haiku is $10 to $20 and 100 to 220 minutes. The 20-paper CMA Opus slice is about $19 at the measured $0.93 per paper, overnight at 12 parallel.
Proof it worked
audit-disk-vs-db.ts exits 0 with zero disk-only artifacts. Compare the two runs on rows per paper, condition coupling and reactor geometry before choosing the extractor for the next cohort.
Stage 8 — Harmonize and analyze
Make the new rows modelable, then refresh everything derived from them.
$0, about 15 minutes per 100 with --skip-priors, 1 to 4 hours with the priors refit.
Proof it worked
epd_total is unchanged across the run (harmonization is pure jsonb_set), pnpm verify:science is green, and /admin/observability shows the cohort.
Cost and time, per 100 papers
Stage
Path
Cost
Wall time
Discover
OpenAlex
$0
< 2 min
Download
paperscraper + unpaywall + curl_cffi, 0.5 s per host, 4 workers
$0
20–60 min
Store
hardlink + migrate-local-to-r2 + key backfill
$0 (storage ~$0.015/GB-month)
2–5 min
Text
PyMuPDF
$0
2–5 min
Screen
classify-title-abstract on Cerebras · CMA Sonnet
$0 · $1.02
8 min · overnight
Extract
v2 Haiku 4.5 · CMA Opus v3
$5–10 · $93
50–110 min · overnight, 12 parallel
Harmonize
quality stages + derived + priors
$0
15 min with --skip-priors, else 1–4 h
200 papers end to end: the cheap path is $10 to $20 and 4 to 6 hours mostly unattended. The high-fidelity path is about $188 and one overnight.
04Ontology and taxonomy duties per cohort
4a. Paper axes
Six TEXT or TEXT[] columns on ResearchPaper, none guarded by a Postgres enum. The taxonomy lives only in apps/web/src/lib/taxonomy/system-types.ts (TAXONOMY_VERSION = 2), so the writers are the only enforcement.
EXPERIMENTAL, REVIEW, MODELING, META_ANALYSIS, PERSPECTIVE, OTHER, plus 2 patent
OTHER 11,644 · EXPERIMENTAL 9,859 · REVIEW 1,216
Three writer tiers, and the order matters. Run regex first, then the title and abstract classifier, then let full-text extraction fill the rest.
Regex, free.classifyByRegex() via scripts/classify-system-taxonomy.ts, also at OpenAlex ingest. Writes all 16 taxonomy columns. Skips taxonomyVersion = 2 unless --force. 7,822 papers carry taxonomySource = regex.
LLM on title and abstract, free on Cerebras.scripts/extraction/classify-title-abstract.ts. Only where primarySystemType IS NULL; Zod-validated, a parse failure never writes. 175 papers.
LLM on full text, paid. The v2 extractor's paper_header pass, landed by scripts/extraction/sync_taxonomy_to_db.ts, matched by DOI then pdfHash, COALESCE(new, existing) so nothing is wiped. 833 papers.
Two ordering traps.scripts/classify-paper-type.ts nulls primarySystemType when it is REVIEW or FUNDAMENTAL, treating them as leakage, and both other writers put them back, so the result depends on execution order. And three parallel system-type columns exist: primarySystemType (canonical), systemType (free text, 8 indexes, OpenAlex writes "BES"), and v1_1_primary_system_type (no writer, but read first by the benchmark export). They agree on 5,855 papers and differ on 1,572.
What you run per cohort: tier 1, then tier 2, then extraction. What you review: the 688 papers with needsReview = true, the 14,443 with a NULL confidence, and the 735 recent visible papers still untyped. Tier 3 human review has columns (taxonomyReviewedBy, taxonomyReviewedAt) and no writer, so nothing drains that queue. A minimal writer would be a script that takes a reviewed CSV of paper id, primarySystemType and reviewer, writes the two review columns plus taxonomySource = 'human', and refuses to run without a ref gate.
fixed 3d89f2901
Fixed 2026-09-08 in 3d89f2901; the mechanism is kept here because it is the pattern to watch for. In scripts/extraction/simple_value_extractor.ts the Zod enum for system_class was the canonical 17 plus not_BES, but the .describe() text the model actually read enumerated the legacy 30 buckets, and .catch('OTHER') coerced every legacy answer silently. SYSTEM_CLASS_GUIDANCE was keyed by the 30 legacy names, so 14 of the 18 valid values (everything except MFC, MEC, MDC and not_BES) received no per-class guidance: the lookup missed and the prompt template printed the missing value as the word “undefined”. An as [string, ...string[]] cast collapsed the inferred type to string, which is why Record<SystemClass, string> never caught it. Three further copies of the same defect sat in Rule 7 of the header prompt and in the cited_from_system_class example. The fix removed the cast, so the map is now exhaustive-checked; re-keyed the guidance to the canonical 18; rewrote the three prompts; and raised the output cap to 64k because real per-class expectations made a data-dense paper exceed 32k. Smoke on five papers: the MES paper f9ba8929 went from OTHER to MES; MDC and MFC unchanged; the MEC paper fails on old and new code alike.
Physics families (anodic_oxidation, cathodic_reduction, ion_transport, selective_reduction, sensor) are a calibration and out-of-distribution grouping described only in docs/system-class-aware-predictor-architecture.md. There is no TypeScript constant. Do not treat them as a code-level axis.
4b. Value ontology
Five stacked layers. A value must clear all of them to be modelable.
#
Layer
Vocabulary
Size
Lives in
1
Category
ParameterCategory enum + free-text subcategory
18 values, 15 used; 179 subcategories
ParameterDefinition.category
2
Canonical slug
snake_case plus legacy camelCase
835 definitions; 492 seen in rows
EPD.canonical->>'canonical_slug' (JSONB, not a column)
A raw name becomes a slug through four tiers: unit-aware rules first (bare "current" with /m² becomes currentDensity, "cod" with % becomes cod_removal, "cod" with mg/L becomes cod_concentration), then exact match on the alias index, then token-set ratio at or above 90 ("confident"), then token-sort ratio at or above 87 with a token-count ratio of 0.6 or more ("likely"). A single-word name with no exact hit is refused.
Your recurring jobs per cohort.
Run backfill-canonical-slugs.py --apply --confident-only --target staging, then the same without --confident-only, then normalize-to-si.py --apply --target staging.
Add ParameterDefinition rows for the 29 slugs that appear in rows with no definition. membranematerial, cathodematerial, anodematerial, maxpowerdensity, mode, design and _provenance_metadata alone exceed 10,000 rows. A slug with no definition has no unit, range, category or foreign key, so it is invisible to the catalog and ungated by validation.
Two rules that prevent specific corruptions. Split a canonical slug only when the SI units differ (the Logan basis test); same unit with different context is a metadata axis, not a new slug. And never re-add a volumetric unit such as ("power_density", "w/m3") to UNIT_FACTORS; route_kind() splits volumetric out on purpose, and re-merging contaminates the power-density posterior by roughly 1000×.
4c. Acceptance criteria per cohort
✓
Criterion
☐
audit-disk-vs-db.ts --fail-on-gap exits 0 with zero disk-only artifacts.
☐
100% of cohort papers have a non-NULL primarySystemType and a taxonomySource, with zero OTHER or unknown left unexplained.
☐
New numeric rows carrying a canonical_slug are at or above the corpus mean of 45%, targeting 60% or better.
☐
Every new row has derivationMethod and the uncertaintyPlus / uncertaintyMinus / uncertaintyType columns populated where the extractor found them. These are columns, not JSONB (Rule §8).
☐
phase6-smoke-test.ts --n 3 passed before any bulk extraction spend.
☐
pnpm verify:science is green against scripts/science-baseline/priors-v2.json.
☐
/admin/observability shows the cohort, and epd_total did not move during harmonization.
4d. Experiment-coupling duties per cohort
The atomic unit for the platform's goal is the experiment record: a ConditionSet carrying a populated input vector AND at least one linked output, not the paper. scripts/quality/coupling-completeness.ts states this in its own header — the objective is conditional models P(outputs | inputs, system_type) per class. Papers are specialists, not generalists, so per-paper field fill-rate is the wrong metric, and scoring against a universal schema punishes exactly the diversity the corpus needs.
Per-cohort checklist.
✓
Criterion
☐
Run coupling-completeness.ts before and after the cohort; record Q4 (complete records per class).
☐
Every new v2 paper ends with at least one ConditionSet and its outputs linked.
☐
No paper gains more ConditionSets than it has distinct reported operating conditions; flag anything over about 10 as fragmentation.
☐
epd_coupled rises by at least the number of new numeric rows the cohort added.
☐
The four sanity slugs (powerDensity, cod_removal, current_density_areal, power_density_areal) stay above 80% linked.
How to read the numbers. Thin coupling (low Q1, tiny Q4, near-zero Q5) means the constraint is coupling, not volume — fix coupling before extracting more. Healthy coupling means the data was fine and the modeling was using marginals — build the conditional model instead. Full decision tree: docs/handoffs/2026-07-10-data-coupling-diagnostic.md.
05The extraction schema: three extractors, one public doc
Public doc vs reality
As of 2026-09-08 the public methodology tab still documents the v1.2 orchestrator; the refresh is tracked under roadmap B1/A3. Its component, apps/web/src/app/[lang]/parameters/components/methodology/ExtractionMethodologyTab.tsx (a near-duplicate lives at apps/lab/src/app/methodology/components/ExtractionMethodologyTab.tsx), says in its own header comment that it documents "every field the v1.2 LLM extractor produces." That schema is apps/api/src/lib/extraction/v1-schema.ts (1,025 lines of Zod), driven by scripts/extraction/orchestrator.ts and the nine sub-prompts in scripts/extraction/prompts/v1/. Per the root CLAUDE.md that stack has been parallel-deprecated since 2026-05-08. The active extractor, scripts/extraction/simple_value_extractor.ts, emits a different and much smaller shape. A new engineer who reads the methodology page and then opens a real values_v2.json file will not find most of what the page describes.
5.1 What each extractor emits
Field group
v1.2 (deprecated)
v2 (active)
CMA v3
Why it matters
Classification gate
yes
no
no (separate screening stage)
Filters non-BES papers before spending on extraction.
Primary system type
yes
yes (system_class)
yes (system_type)
The 17-type taxonomy axis; every downstream router keys off it.
System variants
yes
no
no
Architecture sub-variants within one system class.
Application domains
yes (full-text LLM)
no (relies on the separate title/abstract classifier)
no
"What works for X application" filtering.
Geometry (topology, volumes, areas, distance)
yes
partial (anode_projected_area_cm2, cathode_projected_area_cm2, membrane_area_cm2; no topology_class, volumes, or inter-electrode distance)
partial (reactor_geometry object with ~40 fields, no topology_class enum)
Drives 3D template selection and area-vs-volume normalization.
Materials (id + as_reported + treatments + catalyst)
yes
partial (catalyst present, no treatments[], no canonical id / as_reported split)
partial (material name strings, no treatments[])
Same material with different pre-treatment can span a 25× performance range.
partial (see 5.2 — phase, value_kind, derivation_method, normalization_basis, section_source, snippet, confidence, uncertainty, replicates_n, measurement_technique all present; no page)
yes (all present, including page)
Prevents pooling a peak value with a steady-state value, or an anode-area density with a volume density.
Polarization curves
yes (digitized point series)
no
no (curve peaks land as individual observation rows, not a digitized series)
Internal resistance and peak power come from fitting the curve, not one number.
EIS spectra
yes
no
no
Nyquist-intercept resistances.
Microbial kinetic constants
yes
no
no
Monod/Contois growth-kinetics inputs.
Electrochemical kinetics
yes
no
no
i0/alpha/Tafel-slope inputs to the Butler-Volmer fit.
Author limitations / concept tags / cited models
yes
no
no
Audit trail and cross-paper concept linking.
5.2 Correction to scope this section against: three of the four assumed gaps already exist
The obvious hypothesis is that value_type, is_normalized_to, reference_electrode + voltage_reporting_convention, and per-observation condition binding are missing from v2 and need adding. Grepping the schema shows that is only true for one of them.
value_type (peak vs steady-state) is already in v2 as three fields shipped 2026-05-08: phase (startup/steady_state/degradation/transient), value_kind (point/mean/peak/min/max/range_low/range_high/…), and derivation_method (polcurve_pmax, steady_state_at_rext, ocv_at_zero_current, tafel_backfit, …). The extractor's own prompt notes derivation_method coverage was under 7% before a 2026-community rule aggressively defaulted it — this is a fill-rate problem, not a schema gap.
is_normalized_to (area basis) is already in v2 as normalization_basis (anode_projected_area / cathode_projected_area / membrane_area / reactor_volume), same rule family, same fill-rate caveat.
reference_electrode is half-present: reference_electrode_type exists on the paper-level paper_header. voltage_reporting_convention (is a value vs Ag/AgCl, vs SHE, or a whole-cell voltage) is genuinely absent from v2 — this is the one real net-new Zod field.
Condition-set binding on every observation is already in v2 as inline per-value fields (temperature_c, ph, substrate, hrt_hours, cod_mg_l, external_resistance_ohm) plus an explicit "Rule 2b COUPLING" prompt instruction shipped 2026-07-11 to fill them on every outcome row. The measured 27 full-tuple rows in the corpus (memory/project-extraction-coupling-gap-2026-07-11.md) is a fill-rate / extraction-reliability gap against a schema that already has the fields, not a missing field.
The one confirmed multiplier evidence in the repo: the methodology page's own "why" lines say conflating peak and steady-state values "produces 2-3× errors" and that area-basis mismatches run "1.5-3× to 10-1000×." The voltage-prior contamination incident (memory/project-include-v1-harmonization-2026-07-08.md) is a related but distinct failure — a non-MES cohort mis-canonicalized to voltage pushed the fitted mean to 53.9 V against a correct value near 0.5 V; that is a canonicalization defect, not a value_type / is_normalized_to schema gap. The 45% canonical-slug coverage figure is in the state strip in §1.
What this changes for effort estimates. Adding voltage_reporting_convention is a genuine schema change: one field on the per-value schema, one prompt line, a 5-paper smoke. Raising fill-rate on phase / value_kind / derivation_method / normalization_basis / hrt_hours / cod_mg_l is prompt reinforcement plus a fill-rate audit on a recent extraction batch — cheaper than a schema change, but it is real, ongoing work, not a solved problem.
1. Extend v2 with the one real Tier A gap plus a fill-rate push
Cheapest, keeps the active path. Add voltage_reporting_convention (~1 day incl. a 5-paper smoke) and audit + reinforce fill-rate on the fields already shipped. No new pipeline to maintain.
2. Adopt CMA v3 as the extractor of record
Already measured at $0.93/paper with 100% outcome-condition coupling on run-03 (docs/corpus-screening-agent/CORPUS-DIAGNOSIS.md). load-all.py writes only to LOCAL_DATABASE_URL today — needs a ref-gated --target before it can promote past local. About 12x the per-paper cost of v2 Haiku.
3. Resurrect the v1.2 orchestrator
The schema and nine prompts already exist, so it looks free. It was deprecated 2026-05-08 for cost (nine sub-prompt calls per paper) and reliability, not for missing fields. Do not do this without re-litigating why it was dropped.
Recommendation: Option 1 now, plus Option 2 on the existing 20-paper benchmark slice. This matches the extractor decision already taken in §3 Stage 7 (v2 Haiku bulk, CMA Opus on a 20-paper benchmark so the quality gap is measured, not argued). Add one more item to that comparison: fix the public methodology page to say which extractor it describes, or regenerate it from the active v2 schema, so the claim/reality gap in this section closes instead of confusing the next engineer who reads it.
5.5 What a new engineer must not assume
The methodology page is not a contract with the active extractor — it describes the deprecated v1.2 orchestrator, not simple_value_extractor.ts.
values_v2.json rows are not schema-blind on value type or normalization basis (phase/value_kind/normalization_basis exist), but fill rate on those fields is uneven — check the unit string and these fields by hand before comparing power densities across papers.
The v1.2 prompt files under scripts/extraction/prompts/v1/ are live, working code, but the path is deprecated. Do not extend them.
CMA output lands in a different shape (condition_sets + observations arrays keyed by condition_set_label, plus reactor_geometry, figures, unresolved) and its loader, docs/corpus-screening-agent/load-all.py, is local-only today.
06Beyond the 2.5 hours
Item
Why
Effort
Unblocks
GitHub Actions corpus-refresh job-DAG, staging-default and budget-capped
1,444 files idle, about $70–150; the parser scripts/extraction/lib/pmc-xml-to-text.ts works and the extractor takes --input-format pmc-xml, but run-pipeline-for-source.sh hardcodes markdown
1 d + $
Full text without a PDF download
Promote the four JSONB harmonization keys to columns
canonical_slug, si_value, si_unit and applicable_to_modeling sit in JSONB while 88 code sites filter on them (Rule §8)
3–5 d
Query plans, Prisma types, ML reads
Gap 18 four-value relevance enum, plus screener verdicts into the DB
is_bes_paper is binary; the screener's topic and verdict axes reach no column
2–3 d
Prior weighting by relevance
Retire one of backfill-r2-keys.ts / backfill-r2-source.ts
They disagree about pdfSource, so provenance depends on which ran last
2 h
One provenance story
Archive the BullMQ mock (done 2026-10-02, moved to archive/2026-10-bullmq-scaffold/)
taken v2 Haiku in bulk plus a 20-paper CMA Opus benchmark slice, so the quality gap is measured on this corpus rather than argued from run-03.
Where CMA output lands
give load-all.py a --target with a ref gate, or keep a local staging area and promote later
BioC-PMC XML
1,444 files, ~$70–150, parser exists at scripts/extraction/lib/pmc-xml-to-text.ts; the per-source script's markdown hardcode is the only thing in the way
07Experiment coupling: the state of it, and what to fix first
Coupling is not wired into any gate today — coupling-completeness.ts is referenced only by a July 2026 handoff and a spec doc, and is run by hand. Nobody measures it during the corpus run. The two bugs below make every re-run worse.
Coupling is a shape before it is a number. One paper carries many ConditionSet rows — one per experimental condition it reports — and each set couples zero or more extracted values through conditionSetId:
One paper carries many condition sets (A, B, …); each couples zero or more extracted values by conditionSetId. Green boxes are linked outputs — the best-coupled rows in the corpus. The rose box is the real gap: an unlinked input row, not a missing output.
Green boxes are linked outputs, the best-coupled rows in the corpus. The rose box is the real gap: an unlinked input row, not a missing output. Two systems share the word “experiment” in this schema — the corpus-derived ConditionSet + ExtractedParameterData pair measured below, and the user-authored Experiment / Run / Measurement notebook trio, which has no shared code path with extraction. Everything in this section is the first.
Measured against canonical staging (the canonical staging project; ref in docs/staging-access.md), 2026-09-08:
Metric
Value
EPD rows, total
199,896
EPD rows, numeric
125,498
EPD rows coupled to a ConditionSet
68,139
ConditionSet rows
41,080
Distinct (paperId, label) pairs
9,720
Duplicate ConditionSet copies
31,360 (up to 24 copies of one label)
Papers with any ConditionSet
1,022 of 23,579
ConditionSets per such paper
median 28, mean 40, max 307
Deduped sets with ≥1 linked output
2,720 of 9,720
Deduped sets complete at inputs≥3
1,760
Deduped sets complete at inputs≥5
825
Sets with zero linked EPD and zero PolarizationPoint
Two intuitions are wrong here, and both cost time if assumed. Outputs are NOT the unlinked side — they are the best-linked rows: powerDensity 91.8%, current_density_areal 86.0%, power_density_areal 83.3%, cod_removal 83.1%. The unlinked side is inputs: substrate 0.7%, ph 5.9%, temperature 8.5%. And this is NOT primarily a backfill problem — only 807 of 9,550 papers with extracted rows carry v2 rows (63,514 rows, 100% linked); the other 136,382 rows are legacy-extractor output carrying no inline conditions, 0% linked by construction. The free recovery pool caps at 3,678 rows (2,064 from v2-opus-max-2026-05-11, 1,127 from the llama v1.0 batch) — an estimated yield of low hundreds of complete records.
Two root causes.
scripts/quality/backfill-condition-sets.ts:210 calls createMany({ skipDuplicates: true }) against @@unique([paperId, label, runId]) at prisma/schema.prisma:3742, but never sets runId. Postgres treats NULLs as distinct, so the constraint never fires and every re-run mints a new generation.
scripts/extraction/sync-values-v2-to-db.ts:497 deletes a paper's v2 rows and re-inserts them (payload at :557) with conditionSetId unset, stranding the previous generation of sets.
Fix order.
#
Fix
Effort
Result
1
Collapse the 31,360 duplicate sets, repointing child FKs to the survivor
1h
Unblocks the constraint and corrects every downstream count
2
Add @@unique([paperId, label]) plus a migration
1h
Duplicates MUST be collapsed first (fix 1) or CREATE UNIQUE INDEX fails. Setting runId instead is the wrong fix — it makes each re-run legitimately distinct, which is the behavior we want to stop
3
Reuse an existing (paperId, label) set instead of creating one
2h
Reattaches the 27,419 orphans
4
Route the three writer scripts through resolveDbTarget()done (a8875ecd1)
done
Was the bare-PrismaClient footgun. All three now gate on the Supabase project ref; a non-local URL without an explicit --target hard-refuses
5
Broaden the extractor-version filter at backfill-condition-sets.ts:131 from = to a version set
3h
Unblocks the 3,678-row recovery pool
Defects.
Severity
Defect
Fix
high
skipDuplicates no-ops on a NULL-bearing unique key
Make the key NULL-free
high
Re-sync orphans sets it deletes and re-inserts without relinking
Re-link after insert in the same script
high
Bare new PrismaClient() in all three writer scriptsfixeda8875ecd1
resolveDbTarget(), ref-gated
med
continue on a failed batch skips the link update and still exits 0fixeda8875ecd1
Counts failed batches, exits 1
medium
NULL hashed as a distinct tuple value splits one run across sets
Hash only the stated keys
low
No index on ConditionSet(paperId, label)
Supplied by the unique index in fix 2
Fixes 1-3 remain prerequisites for any large v2 run, not optional cleanup (fix 4 landed in a8875ecd1). The 807-paper run produced 37,043 sets for 8,435 real tuples and orphaned 24,540 of them; running v2 over ten times the papers without these fixes reproduces that at ten times the scale.
Source: docs/onboarding/streamlined-corpus-run.md. Numbers measured on staging (canonical staging) 2026-09-07.
The user-facing surfaces: real, but a different feature and hard to find
apps/web/src/app/[lang]/experiments/[id]/page.tsx and apps/web/src/app/[lang]/runs/[id]/page.tsx are genuine server components — they call prisma.experiment.findUnique / prisma.run.findUnique directly, with force-dynamic, and render real rows, not mocked data. But they read the user-authored trio above, not ConditionSet. There is no listing page for either route, and the only inbound link anywhere in apps/web/src is one card on /projects/[id], which itself requires a signed-in session scoped to that user's own projects. There is no page anywhere in apps/web that lets a visitor browse the corpus's coupled experiment records — that story lives only in coupling-completeness.ts script output and the onboarding docs.
prisma.run.findUnique + Experiment; dumps inputs/outputs as raw JSON
cards on /experiments/[id]
real, no schema-aware rendering
The corpus-wide coupling story on this page — 1,760 complete records, the two bugs above, the class-median result at 14 — has no dedicated UI at all today.
08How a paper becomes a modelable row
Measured 2026-09-07 on staging: papers with extracted rows already exceed papers with a PDF, and 55% of extracted rows have no canonical slug (45% do). The binding constraint is harmonization, not extraction. "Run more extraction" is usually the wrong lever.
7,598
papers with a PDF
STAGING · 2026-09-07 · pdfHash set
9,550
papers with extracted rows
exceeds the PDF count · 807 of them v2
55%
EPD rows with NULL canonical slug
109,378 of 199,896 · STAGING 2026-09-07 (80.7% was LOCAL 2026-06-30)
31,924
modelable rows
STAGING · 2026-09-07 · applicable_to_modeling
Commands and flags verified on feat/corpus-derived-recommendations. Full invocations with env prefixes: docs/onboarding/paper-pipeline.md.
The one command per stage
Stage
Run
Cost gate
Skill
acquire
cd open-source/mess-parameters && PAPERS_ROOT=$REPO/papers pnpm papers:all
free providers only; never two downloaders at once
alias classifier ~$5–7 per 15k names; DB only via deterministic backfill
mes-data-harmonization
promote
re-run the script with --target=staging --apply · then pnpm backup --target=prod and the same script with --target=prod --expect-ref=<ref> --apply · prisma migrate deploy for schema
backup first; staging verifies before prod
mes-db-migration-sync
The five layers, and where each one stands (staging, 2026-09-08)
One home for this table. The five-layer state table — what exists at each layer, what it measured on staging, and the fix — lives in Part II · 00, section 0a, where it is actually used to plan a run and where each row links to the section that details it. It used to be restated here and in section 07 Platform map as well; three copies drift, and two of them did.
Order is not optional: coupling hygiene first (a large v2 run on today's backfill reproduces the 24,540 orphaned sets of the 807-paper run at ten times the scale), then the acquisition blockers, then extraction recency-first on the 1,405 papers from 2025–26, then vectorization, then gates and automation. Full sequence: docs/onboarding/streamlined-corpus-run.md §0b.
$0.05
v2 Haiku per paper · inline per-value conditions
backlog of 8,743 legacy papers ≈ $440
$0.12
3-pass, after fixes · one experiment record per condition
backlog ≈ $1,050
$0.93
CMA v3 Opus · 100% coupling, geometry, figures (run-03)
backlog ≈ $8,100
taken
Extractor decision v2 Haiku in bulk + a 20-paper CMA Opus benchmark slice
streamlined-corpus-run.md §3 stage 7
Harmonization hard rules
Never pool areal with volumetric. W/m² and W/m³ are separate kinds; re-merging contaminates the posterior ~1000×.
Logan basis test. Split a slug only when SI units differ; same unit, different context is a metadata axis.
Never lower the single-word fuzzy guard. "Current" matches a dozen slugs at 100.
Molar → mg/L needs the species mass. Leave unconverted; do not invent a factor.
Refit both v1 and v2 priors. Never ship a FAST-mode v2 artifact.
The methodology page describes the deprecated v1.2 extractor, not v2. Only one of the four assumed schema gaps is real (voltage_reporting_convention); phase, value_kind, derivation_method, normalization_basis and inline conditions already exist and are fill-rate problems. Only the header+values two-call merge is open; the other three LLM passes are blocked for real reasons.
What "done" means for a row
Non-NULL canonical_slug mapped to a real ParameterDefinition
si_value + si_unit, volumetric routed to its own kind
applicable_to_modeling true, verifierPassed true
system_class one of the 17 canonical types, not OTHER
199,896 EPD rows · 125,498 numeric · 68,139 coupled to a ConditionSet · 41,080 ConditionSet rows for 9,720 distinct (paperId, label) pairs · 31,360 duplicates, up to 24 copies of one label.
Outputs are the best-linked side (powerDensity 91.8%, current_density_areal 86.0%); inputs are the unlinked side (substrate 0.7%, ph 5.9%, temperature 8.5%).
Only 807 of 9,550 extracted papers carry v2 rows (63,514 rows, 100% linked); the other 136,382 rows are legacy output with no inline conditions, 0% linked by construction. Free recovery pool caps at 3,678 rows.
Root causes: backfill-condition-sets.ts:210 createMany({skipDuplicates}) against @@unique([paperId, label, runId]) with runId never set; sync-values-v2-to-db.ts:497 deletes and re-inserts a paper's rows with conditionSetId unset. Writer scripts ref-gated in a8875ecd1.
The same pipeline, as the public page describes it
messai.io/learn/science presents five stages — discover → resolve → extract → harmonise → sync — where the six-stage view above splits categorization out and carries promotion to the end. Same machine, different cut. Two properties it states that are worth holding on to: each stage is idempotent and resumable, so adding one PDF only triggers downstream work for that paper; and nothing is asserted that cannot be traced back to a sentence in a paper.
Design choice 1
Gate before you spend
A cheap classification gate runs before any expensive extraction, so off-topic PDFs are rejected for a fraction of a cent instead of contaminating the corpus. This is the screening stage in the table above.
Design choice 2
Two-tier extraction
A paper header plus one row per measurement, so a paper reporting peak and steady-state values yields two comparable rows rather than one ambiguous average. It is also why the header and values calls are separate.
Design choice 3
Provenance on every write
A number you cannot trace is a number you cannot defend. Every stored value carries extractorVersion, extractedAt, a confidence, the conditions, and the source snippet.
How a paper enters. Candidates come from CrossRef, PubMed, ArXiv, Unpaywall and OpenAlex, plus curated admin imports. Each PDF is fingerprinted by SHA-256, its DOI resolved, and it is hardlinked into a hash-keyed store. Deduplication runs at three layers — byte-identical SHA-256, DOI, and canonicalised title — so the same paper arriving from three sources becomes one record. The v2 extractor then makes its LLM call, Anthropic Haiku primary with Gemini or Groq fallback when the gateway is throttled — and the Gemini fallback is exactly the one that over-assigns OTHER at about 52% against about 14% on Haiku, so a throttled run silently degrades classification.
Trust is stratified by section: tables > methods > results > discussion, with a ±200-character window kept back to the source. A run is not “complete” until the disk→DB sync lands the rows with full provenance and the disk-vs-DB audit is clean — the same gate as audit-disk-vs-db.ts --fail-on-gap above.
The quality gate that decides what enters the training pool
Passing extraction is not the same as being trained on. Five conditions decide, and a paper failing any of them stays in the corpus with needs_review = true — visible, but out of the training set until cleared.
Check
Condition
Relevance
is_bes_paper = true and not retracted (the retraction sweep is check-retractions.ts, 11)
Typed
primary_system_type set, and not a review or modelling paper
Confidence
At least one value at confidence ≥ 0.7
Internal arithmetic
P ≈ V·I within 15% · CE ≤ 100% · mass-balance closure
Cross-paper
No cross-paper consistency flag
Tier-1 verification currently returns FLAG, not PASS
Five checks run: snippet grounding, literature cross-check, unit audit, noise floor, duplicate consistency.
The current overall verdict is FLAG. The public page says so plainly — the checks surface real weaknesses rather than rubber-stamping the data — and this Atlas agrees: 198,229 of 199,896 rows still sit at validationStatus PENDING (09), and 6,449 rows carry verifierPassed = true.
Stated caveats, unchanged: overall extraction success is not currently measured; sparse buckets (MERC, MMRC, MBES) have thin coverage; roughly a quarter of raw values are not yet canonicalised.
Public counts against measured counts
The public page carries dated snapshots; the numbers elsewhere in this Atlas are re-measured on staging. They are close, and the gaps are all explainable — but quote the measured column, with its date.
Quantity
Public page
Measured (staging)
Why they differ
Papers in the corpus
23,568+
23,579 2026-09-08
Snapshot drift at the time. Both counted every paper row; since 2026-10-25 the public page quotes the /research count, which leaves out stub rows and merged duplicates.
Papers with ≥ 1 extracted value
9,518
9,550
Same drift.
Extracted value rows
195,846
199,896 2026-09-07
Same drift.
Canonical mapping rate
51.6%
45% 2026-09-07
The one worth checking. 90,518 of 199,896 rows carry a canonical slug on staging. The public figure may be computed over numeric rows only, or predate the last re-measurement. Either way it is a ceiling on modelability, not a cosmetic number.
Canonical slugs / definitions
825
835
Exactly the known gap: the pinned parameter-definitions-rich.json is 10 definitions behind staging, which is why the fixtures, the npm package and the KG snapshot are stale (17).
Parameter-graph edges
2,812
2,792 KG snapshot
The snapshot is regenerated separately from the live graph; nine wastewater edges were also dropped by an invalid edgeType in July (09).
09Six axes, three writer tiers, five ontology layers
Two different things hide under "categorization". A paper is classified on six axes (which reactor, which subtype, which coupling, what kind of study, which application, what document). A value extracted from that paper is classified through five stacked ontology layers before it can be modeled. All counts below are staging, ref , measured 2026-09-07.
The corpus funnel
Bars are to scale within each band. "Visible" = not hidden. Only ~1,230 of the 4,896 hidden papers carry a rejection_reason (910 unverified_stub). 198,229 of 199,896 rows still sit at validationStatus PENDING.
Six axes on a paper
All six are plain TEXT or TEXT[] columns on ResearchPaper. No Postgres enum guards any of them; the 17-type taxonomy lives only in apps/web/src/lib/taxonomy/system-types.ts (TAXONOMY_VERSION 2), so the writers are the only enforcement.
axis 1primarySystemType17 values · colour = physics family · bar = non-hidden papers
anodic_oxidationcathodic_reductionion_transportselective_reductionsensornot a reactor classNULL on 10,286 visible papers
MFC generic has 21 values (single_chamber_air_cathode … algae_cathode). MES splits into by_product (acetate, methane, ethanol, butyrate, MCFA, mixed) × by_carbon_source (pure_co2, flue_gas, bicarbonate, direct_air_capture). Regex writes a flat array; the LLM writes an object. Both land in the same column.
Combinations are coupling rules, not new predictors. Regex resolves two anchors by SPECIALIZATION_RANK (MES 13 … MFC 2): the more specialised type becomes primary, the other becomes combinationPartner.
Dotted chips are values outside the canonical 8, written by an earlier writer. Two writers (LLM classifier, regex backfill) share the column with no provenance marker. This axis is the most specific stratum key in prior lookup, so a missing domain silently falls back to a coarser prior.
OTHER 11,644EXPERIMENTAL 9,859REVIEW 1,216MODELING 632PERSPECTIVE 57META_ANALYSIS 38PATENT_APPLICATION 18PATENT_GRANTED 4
The extractor emits 11 classes (methods, theoretical, review_narrative …); the DB keeps 6. "methods" folds into OTHER and is unrecoverable. REVIEW and FUNDAMENTAL also exist as system types; classify-paper-type.ts nulls them out and classifyByRegex puts them back.
Who writes the class, in what order
Decision order read from apps/web/src/lib/taxonomy/regex-patterns.ts; counts from staging taxonomySource / taxonomyConfidence.
The screening agent's axes never reach the DB
The July screener classifies every PDF on four axes: route (born_digital | needs_ocr, by printable ratio), topic (core | peripheral | off_topic, judged by what the paper is about, not keyword count), doc_type (primary_research | thesis | review | proceedings | reference_work | other) and verdict (keep | keep_flagged | cull). No column on ResearchPaper holds any of them. topic is the higher-resolution version of is_bes_paper; cull is the same action as is_hidden; nothing carries either across.
run-02 · 200 papers
primary
thesis
review
other
total
core
62
1
11
3
77
peripheral
15
0
21
3
39
off_topic
59
1
16
7
83
Verdicts: keep 59 · keep_flagged 17 · cull 123. The 1,400-paper Sonnet sweep culled 10.8%, not 61.5%, because a free term-density pre-filter had already removed ~2,780 zero-mention documents. Do not average the two runs.
Legacy 30-bucket: retired from the schema, but still the vocabulary inside the v2 extractor's prompt (see below).
v1.1: 12 values in v1_1_primary_system_type. No writer; read first by the benchmark export and the physics skill.
Screener: topic × doc_type × verdict × route. Never reached the DB.
Reproducibility: 14 study types × 4 weighted axes × 95 criteria. No mapping to canonical.
Plus systemType, a free-text legacy column with 8 indexes that OpenAlex ingest fills with "BES". It agrees with primarySystemType on 5,855 papers and differs on 1,572.
Highest-severity finding (fixed 2026-09-08) · the v2 extractor's system_class prompt contradicted its own schema
In scripts/extraction/simple_value_extractor.ts the Zod enum for system_class was the canonical 17 + not_BES, but the .describe() text the model actually read still enumerated the legacy 30 buckets (MFC_dual_chamber, photo_MFC, MES_acetogenic …). The field was .catch('OTHER'), so a model that followed the prompt was silently coerced to OTHER. SYSTEM_CLASS_GUIDANCE was keyed by the same 30 legacy names: twelve canonical types (MSC, MEFS, MESNORK, MERC, MNRC, MMRC, MRB, MBES, MREC, MCDI, REVIEW, FUNDAMENTAL) and bare MES had no entry, so the values prompt printed the missing lookup as the word “undefined” for them. The type check that should have caught this was disabled by an as [string, ...string[]] cast. Fixed 2026-09-08 in 3d89f2901. The cast is gone (the map is now exhaustive-checked against PRIMARY_SYSTEM_TYPES + not_BES), SYSTEM_CLASS_GUIDANCE is keyed by the canonical 18, the describe text, Rule 7 and the cited_from example were rewritten, the fallback is OTHER with a stderr warning, and the output cap rose 32k → 64k. The commit measured 14 of 18 types without guidance. Smoke on 5 papers: MES paper f9ba8929 OTHER → MES; MDC, MFC unchanged; MEC a5ccb99a fails on old and new code alike. Every extraction before the fix remains suspect for system_class.
The parameter ontology: five stacked layers
A raw string like "Power Density" with unit "mW/m2" passes through five independent layers. They are not one taxonomy and they do not nest. Layer 1 is for browsing; layer 3 is the physics; the modelable gate lives at layer 3, not layer 1.
Definitions from ParameterDefinition (835). Row counts join EPD.canonical→'canonical_slug' to ParameterDefinition.slug; 4,902 slugged rows match no definition. temperature is ENVIRONMENTAL in definitions but lands PHYSICAL on extracted rows: the two category systems were never mapped (SCIENTIFIC_INTEGRITY.md §5.0.1).
A slug outside SLUG_TO_KIND is never SI-normalized and never modelable. Also held out by derivation: meta_analysis_aggregate and literature_review_aggregate (a review's median over 1,073 articles is not a reactor).
voltage 329 · cod_concentration 150 · bod_concentration 56 · anode_potential 42 · cell_voltage 37 (role depends on system: applied in MEC, produced in MFC)
A condition has no population mean to estimate, so conditions fitted as outcomes produce R-hat ≈ 3, ESS 2. The rich 25-value ParameterClassification.primaryRole (bulk_observable 219, tunable_operating_param 145 …) covers 706 of 835 definitions, 220 at low confidence, and is independent of pclass.
volumetric patterns listed first so /m³ is not stolen by /m²
1
exact match on normalized text against the alias index (ParameterDefinition slug+name → YAML dag-node aliases → parameter-aliases-extended.json 6,721 aliases in 438 groups → rich definitions)
100
earlier sources win via setdefault; YAML overrides because it carries semantic warnings
2a
single-word raw name with no exact hit → refuse
—
"Current" token-matches a dozen slugs at 100; never lower this guard
2b
multi-word, rapidfuzz token-set ratio ≥ 90
≥90
"confident" tier, applied first with --confident-only
2c
multi-word, token-sort ratio ≥ 87 and token-count ratio ≥ 0.6
≥87
"likely" tier; a 2-word name cannot match a 5-word slug
The LLM alias classifier (classify-raw-names-with-catalog.ts, Haiku via the Gateway) only edits the alias data file; the DB changes solely through the deterministic backfill. The extended file's 79 pending_review entries include "th" → ph, "it" → ph, "which" → ph: exactly the edit-distance false positives behind the pH incident (79.4% implausible, ISBNs scraped as pH, fixed on LOCAL only in PR #750). ph is the largest slug in the corpus at 12,280 rows.
Ontology rules, each one a past incident
Import the taxonomy, never redefine it. A file that declares its own SystemClassEnum or accepts only MFC/MEC/MDC coerces 14 types to MFC-shaped output.
Physics families are for calibration strata and OOD, not predictors. anodic_oxidation (MFC, MSC, MRB, MESNORK) · cathodic_reduction (MEC, MES, MEFS) · ion_transport (MDC, MREC, MCDI) · selective_reduction (MERC, MNRC, MMRC) · sensor (MBES). There is no TypeScript constant for this mapping yet; it lives in prose.
Logan basis test. Split a slug only when SI units differ. Anode-area vs cathode-area normalization at W/m² is a metadata axis.
Never pool areal with volumetric. route_kind() sends W/m³ to its own kind on purpose.
Conductivity is two slugs. electrical_conductivity is the umbrella; electrolyte_conductivity is ionic only. The YAML warning blocks encode this.
ParameterEdge.edgeType outside mechanistic | empirical | deterministic | constrains | confounds is written and then silently dropped from the snapshot. Nine wastewater edges vanished this way on 2026-07-05.
MES with one S is Microbial Electrosynthesis, one of 17 types. MES as the field name is the codebase namespace. audit-non-bes-candidates.py uses the second sense throughout.
The catalog file, and its sync pipeline
open-source/mess-parameters/data/parameter-definitions-rich.json is a flat array of 825 entries (measured 2026-09-08; package.json's own description still says “704 parameters”, stale, ignore it). Each entry carries 23 fields: identity (id, slug, name, category, subcategory), typing (unit, data_type, min_value, max_value, allowed_values, is_required), and prose (definition, typical_values, measurement_methods, affecting_factors, performance_impact, limitations, cost_analysis, related_parameters, references, compatible_systems, priority, usage_count). It is a generated artifact, not a hand-edit target — the database has been the source of truth since e0f66f500 (07), which is what the 825-vs-835 gap two tables up (09) actually is: rich.json waiting on its next regeneration.
Step
Script
Produces
1
sync-from-database.js
parameter-definitions-rich.json
2
generate-parameter-fixtures.ts
one public/data/parameters/<slug>.json fixture per parameter, DAG-role annotated; prunes fixtures on disk but absent from rich.json, archived (never deleted) under a 10% stale-ratio safety ceiling
3
generate-parameters-optimized.ts
parameters-optimized.min.json — what the catalog UI actually fetches
Step 3 is wired into apps/web's prebuild, so every local or Vercel build regenerates the catalog from whatever rich.json happens to be on disk at build time. Step 2's 10% ceiling is a safety refusal, not a cleanup convenience: a truncated rich.json fails loudly instead of silently archiving hundreds of fixtures.
The real /parameters/* route map
Route
What it is
/parameters
Server shell + client page, 5 in-page tabs (catalog, correlations, global, sweep, methodology) switched by query string — most of the routes below are thin redirects into this one page
/parameters/[slug]
Per-parameter detail — the same component the catalog embeds inline as an expand-to-full-screen panel
/parameters/knowledge-graph
The d3-force KG renderer: evidence, causal structure, correlations, gaps in one view
/parameters/dag
Deprecated redirect (2026-07-18) → /parameters/knowledge-graph; the old AntV G6 DAG explorer is archived
/parameters/correlations · /global · /methodology
Redirect stubs → /parameters?tab=…, no UI of their own
/parameters/sweep
Also a redirect stub in apps/web — but the multi-zone rewrite intercepts this exact path to apps/lab's real Logan-grade sweep UI first, whenever LAB_ZONE_URL is set
/parameters/dag, /parameters/correlations, /parameters/global, /parameters/methodology, and apps/web's own copy of /parameters/sweep are not standalone pages — all five redirect into /parameters?tab=…. apps/web's /parameters/sweep stub is additionally dead in any zoned environment: the multi-zone rewrite sends that exact path to apps/lab instead. Run pnpm dev alone, with no LAB_ZONE_URL set, and the dead apps/web stub is what actually serves — use pnpm dev:zones to see the real sweep UI locally.
Protocols — a separate, much smaller ontology
/protocols, shipped July 2026, is a second knowledge graph that is easy to mistake for a corpus-mined companion to the parameter DAG above. It is not: it is a hand-authored reference ontology of experimental procedure steps (prepare growth medium, heat-treat the anode, set electrode spacing, …), with edges of type precedes / requires / alternative_to / produces between them. Four lenses share one data substrate behind a single shell — method graph, an ordered protocol DAG, a drag-and-build protocol builder, and a method→outcome overlay — switched via ?view= with a shared ?step= selection.
53
curated steps
generated 2026-07-06, unchanged 2026-09-08
68
curated edges
all hand-authored
8 / 53
steps with any corpus grounding
a borrowed parameter paper-count, not a per-paper match
10
curated method→outcome links
direction only, no effect size or CI
Every one of the 68 edges carries learnedFromData: false, paperSupportCount: 0, and coOccurrence: 0; all 53 nodes carry provenance.basis: "curated", though the type system allows corpus and hybrid nodes that don't exist yet. No Prisma model backs any protocol node, edge, or step, and there is no /api/protocols* route — the client fetches a static protocol-snapshot.json directly, regenerated by hand via pnpm protocols:snapshot, not by the web prebuild. Vocabulary (10 process stages, 6 categories, 4 edge types) is defined once locally and never imported from the canonical system-types.ts taxonomy — the cost shows up in the corpus-evidence file's system histogram, which contains an unvalidated code, “MESNORK”, leaking straight through from raw corpus data.
Reference ontology, not reproduction data — and its evidence wording is stale on this branch
No protocol node or edge links to an Experiment, ConditionSet, or ExtractedParameterData row (12) — there is no join from a paper to a protocol path, so /protocols cannot be used to reproduce a specific paper's method. The detail drawer currently reads “Reported in N papers” for a grounded step, which overstates what the number means: it is the underlying parameter's corpus paper count, not evidence the step itself appears in N papers. A fix for that wording, plus corrected and higher coverage counts (e.g. power_density 157→166, cod_removal 76→107), was written in August 2026 but sits on an unmerged branch, fix/site-science-errors — the live surface still shows the stale numbers.
As of the 2026-09 audit, acquisition had been stalled since May 2026. The last OpenAlex discovery cursor was 2026-05-09, the last PDF landed 2026-08-06, and no paper row had been created since July. The 2025–2026 literature in staging is mostly metadata: 1,405 visible papers, 322 with a PDF. Twelve steps get new papers all the way to analysis today; four of them need a workaround and one is broken.
2026-05-09
last discovery run OpenAlex cursor in papers/staging/last-sync.json
nothing since; no cron exists
2026-08-06
last PDF acquired one file; 3,192 in May, 2,167 in April
pdfAcquiredAt · staging
23%
2025–26 papers with a PDF 322 of 1,405 visible
1,069 of the rest have a DOI to fetch
52%
2025–26 papers untyped primarySystemType NULL on 735
classify-title-abstract on Cerebras is free
0
PDFs in the local cache everything is in R2; 22 marker text files on disk
pnpm papers:hydrate before any disk-walking step
Papers by publication year on staging. Thin bar = rows, solid bar = rows with a PDF. 4,805 rows have no publication date (not shown). The corpus thins exactly where it should be growing.
The twelve steps, and which ones work as written
Green works as written. Amber works with the stated workaround. Red is broken or missing. Every step is read-only or dry-run by default; `--apply` plus the mutation flag is required to write.
worksworkaround neededbroken or missing
Five things block an unattended run today
No pipeline uploads to R2. weekly_pipeline.sh and run-pipeline-for-source.sh both stop at the local hardlink. A newly downloaded PDF exists on one laptop until someone runs migrate-local-to-r2.ts by hand.
`--target staging` resolves to nothing in the acquisition scripts. They read DATABASE_URL_STAGING, which no env file sets, and fall through to whatever DATABASE_URL is loaded. Commit 1122e53a0 fixed this for scripts/quality only.
refresh-all.sh --apply is broken. Its Python stages now require --target and exit 1 without it, which also kills weekly step 7 and both sync post-hooks.
download_curl_cffi.py cannot be pointed at a remote DB. It reads dotenv files before os.environ. It is the only MDPI / Wiley / ACS / Elsevier / IWA path.
run-pipeline-for-source.sh stage 3 has never run. It passes --source-tag to a script that has no such flag; argparse exits 2 and the error is swallowed.
200 recent papers end to end: cheap path $10–20 and 4–6 h mostly unattended; high-fidelity path about $188 and one overnight. CORPUS-DIAGNOSIS.md is the case for the second: the cheap corpus is why 4.1% of papers are modelable and 1 of 135 priors converged. Measured CMA cost is $0.93/paper (run-03), not the $0.63 sometimes quoted.
Smallest set of fixes for an unattended run (~2.5 h)
Route the four scripts that fake --target staging (sync-papers-to-db, classify-title-abstract, ingest_doi_list, search_openalex_underrepresented) through resolveDbTarget(). 30 min.
Add a --target passthrough to refresh-all.sh steps 2–5. 15 min.
Drop the bogus --source-tag from run-pipeline-for-source.sh stage 3. 5 min.
Make download_curl_cffi.py read os.environ before dotenv. 5 min.
Insert an R2 upload stage (migrate-local-to-r2 + backfill-r2-keys) between promote and sync in both pipelines. 30 min.
Give the PyMuPDF text stage the hydrate-from-R2 fallback that marker_pipeline.py already has. 20 min.
Wire pdf-triage.ts into the text stage so scanned PDFs are flagged, not extracted as empty. 30 min.
Decisions only you can make: which extractor for the 2025–26 cohort; whether CMA output may land on staging (load-all.py writes only to LOCAL_DATABASE_URL); whether to spend ~$70–150 on the 1,444 idle BioC-PMC XML files; which of backfill-r2-keys (sets pdfSource=r2) or backfill-r2-source (preserves provenance) survives.
Scripts that silently target whatever DATABASE_URL is loaded
gate on project ref, refuse :6543, --expect-ref for prod
the reference implementations to migrate onto
Full runbook with every command, the env block that points a shell at staging safely, and the per-step DB target: docs/onboarding/acquiring-recent-papers.md.
Part III of VII · Platform map · 11 sections · ~50 min
One repo, four Vercel zones, nine open-source packages, one Postgres.
Every surface MESSAI ships, what feeds it, and what is still dark. Requests enter apps/web and are rewritten to site, lab and api by URL path. Only apps/api writes to Postgres. Everything to the left of the zones is a person or a script; everything to the right is state or a model.
First drawn from feat/corpus-derived-recommendations on 2026-09-03; that branch has since merged into development. The October update was measured on development (5d01c782e) on 2026-10-07. main (production) can lag development, so prod may not show every change here yet.
Verified vs. quoted
Page, route, model, enum, migration, relation, lib, rewrite-entry and ISR counts were re-measured from the tree on 2026-10-07. Package file and reference counts are from 2026-09-03. Corpus row counts, PDF counts, HF Hub sizes and the GP-SCM fit status come from dated docs and were not re-measured against a database.
00Architecture · one model, eight views
Eight UML views over one model of the whole platform. C1 is the altitude everything else
hangs from: three kinds of actor, four Vercel zones, sixteen shared packages, the state layer, and
the external systems. Every box with a + corner opens its own
diagram — the four zones, the package graph, the persistence model and the corpus pipeline
— and Esc comes back up.
Notation is UML 2 kept to the marks that carry meaning at this altitude:
«stereotypes» above every name; the component icon, tabbed package, cylinder and
dog-eared artifact shapes; a dashed open arrow for a dependency, a solid one for a call over the
wire, a filled diamond for composition, dotted for wired-but-dormant. Colour matches the Platform
Map legend below, so the two agree.
C1System contextComponent / deployment diagram
100%
One repository, four Vercel projects, one Postgres. Everything a browser touches enters through apps/web, which owns the rewrite table; everything that writes to the database goes through apps/api. Click any node to open it.
actor Vercel zone / route group shared package state batch script external system dormant
ML engine «service» — Docker · local/batch · :8001
GitHub · Google OAuth «external» — identity providers
Sentry «external» — @sentry/nextjs · apps/api
Resend «external» — transactional email
Structural counts (routes, pages, packages, Prisma models, rewrite paths) were measured against
this repository on 2026-09-09; each view names the command that produced them. Corpus and science
numbers deliberately do not appear in the diagram — those are dated per tile in Parts I–III,
and a diagram is the easiest place for a stale number to hide.
Three rules the diagram is really about
One writer. apps/web and apps/lab read the database in server components; every write
is a fetch('/api/…') that the rewrite forwards to apps/api.
No cross-zone imports. Shared code becomes a @messai/* package,
and the old path keeps a re-export shim — never a copy.
Batch has no host. Acquisition, extraction and the refits run from an operator machine
or the weekly routine. The queue scaffold that sat in apps/api was archived on 2026-10-02;
background work uses Next after().
Batch work has no worker host: scripts run on an operator's machine or in the weekly Claude routine. The BullMQ queue scaffold was archived on 2026-10-02 (archive/2026-10-bullmq-scaffold/); background work uses Next after() or Vercel Queues, and the Upstash store that remains holds rate-limit buckets. Blue cards are Vercel zones, green are shared libraries or live services, amber are scripts, dashed are dormant.
The same map, from the same data, is the deck at /decks/platform-map. The figure below draws its nodes and paths; every node it draws is a card further down this section.
live request path server-component / build-time read batch or script
The four Vercel zones and the one Postgres behind them. Only apps/web carries rewrites, so it is the entry point; only apps/api writes. Dashed boxes are dormant. Node detail is in the cards below.
Clients
Researcher browser
client
messai.io
HTTPS
Every request enters through the messai-ai Vercel project (apps/web), which owns / and rewrites everything else to the other three zones.
entry
apps/web/next.config.js
rewrite map
apps/web/multi-zone-rewrites.json
blocks
api 76 · lab 11 · site 24 entries (2026-10-07)
AI chat & agents
client
/api/chat · tool registry
One canonical RAG chat endpoint with the full tool registry (chat bifurcation resolved 2026-05-12). Tools read the DB and the computed JSON artifacts.
lib
@messai/ai-chat
embeddings
HF Inference Router, live
Local dev stack
developer machine
dev DB = staging · since 2026-10-01
pnpm dev:zones · 3000/3002/3003/4321
Local dev reads and writes the staging Supabase project since 2026-10-01: every .env.development.local points DATABASE_URL and DIRECT_URL at it, so pnpm dev:*, build:local, pre-deploy and db:migrate:local all touch staging. The Supabase CLI stack on :54322 (2026-05-07 → 2026-10-01) is retired. Docker compose for the ML engine on :8001. PDF store on disk is a cache of R2 since 2026-08-14 (pnpm papers:hydrate).
Vercel · 4 projects, one repo
apps/site · messai-site
Vercel zone · marketing
Astro 7 + Vite · 32 pages
/about /learn /solutions /manual …
live · ~8s build
Marketing and docs surface, in English at bare URLs and in German under /de/ (Astro i18n fallback, 2026-09-29). Reads the DB only for the server-rendered /methodologies pages; no API routes.
pages
32 .astro (measured 2026-10-07; 25 @ 2026-09-03)
dev port
4321
rewrite block
site · 24 entries
apps/web · messai-ai
Vercel zone · product
Next.js 16.4.6 · Turbopack
108 page.tsx under [lang]/ · 0 route.ts
live · entry zone
Owns /, /research, /papers, /parameters, /protocols, /admin, /dashboard, /hunter, /insights, /datasets, /experiments, /runs, /survey. The only zone with rewrites. Every page lives under src/app/[lang]/ and is served in English at /x and in German at /de/x (2026-09-29). Reads the DB in server components; every write is a fetch to /api.
Turbopack — plain next build; the May 2026 wedge was the layout import graph, not the bundler
build
~5 min
dev port
3000
apps/lab · messai-lab
Vercel zone · lab simulator
Next.js 16.4.6 · --webpack
17 page.tsx · R3F + Three.js
live · 3D
/lab/*, /lab/dac (electrochemical DAC workspace, 2026-08-25), /models/*, /predictions/*, /methodology, /parameters/sweep. Owns the heavy 3D tree; the seven wastewater unit-process models moved to @messai/process-3d on 2026-09-08 so other zones render the same geometry (apps/lab keeps re-export shims).
pages
17 (measured 2026-10-07; docs said 10 @ 2026-07-06)
dev port
3002
rewrite block
lab · 11 entries
apps/api · messai-api
Vercel zone · API
Next.js 16.4.6 · Turbopack
247 route.ts · only DB writer
live · writes
All /api/* handlers. Heavy server deps live here: Sentry, AI SDK, AWS SDK (R2), pdf-parse. Only zone that writes to Postgres. Background work runs in Next after(); the BullMQ scaffold and its bullmq / ioredis deps were archived on 2026-10-02.
/api/wiki/* — entries, revisions, moderation; every edit stays PENDING until a MODERATOR or ADMIN approves (2026-09-25)
next-auth
auth
GitHub · Google OAuth
NextAuth v4 with the Prisma adapter (two adapters installed — a known P1 cleanup). Sessions, accounts and verification tokens are Prisma models.
Shared code · libs/
@messai/* shared libs · 22
Nx libraries
ui · i18n · database · auth · ml · ai-chat
electrochemistry · dac · polymer-kinetics
electrode-3d · mes-3d · process-3d · testing
render-quality · pid-schematic · lab-cad
component-catalog · use-case-specs · wiki
rate-limit · platform-health · platform-map
Anything used by more than one zone lives here; apps never import each other's src/. Wired via tsconfig paths, transpilePackages, and workspace:* deps.
libs/shared/ui @messai/ui — design system + Tailwind preset, sharp corners only
libs/shared/i18n @messai/i18n — English and German message bundles (German under /de/ since 2026-09-29) and the scientific-notation normalizer
libs/shared/dac — electrochemical DAC model (2026-08-25)
libs/shared/electrode-3d, component-catalog — electrode recipes + catalog data
libs/shared/mes-3d @messai/mes-3d — shared MES R3F parts (reactor parts, particle flows, labels, studio lighting), promoted out of apps/site on 2026-08-10; used by apps/lab, apps/web and apps/site
libs/shared/process-3d @messai/process-3d — the seven wastewater unit-process models and <ProcessModelScene>, promoted out of apps/lab on 2026-09-08 so non-lab zones render the same geometry
libs/shared/pid-schematic @messai/pid-schematic — ISA-5.1 P&ID sheets from a declarative PidSpec, checked by a lint pass; one sheet per catalog reactor model via getModelPidSpec, shown in the lab catalog, /lab/schematic and /demo/resource-recovery
libs/shared/wiki @messai/wiki — the parameter wiki: typed sections, section diff, three-way merge, role rules; every edit waits for a moderator (2026-09-25)
libs/shared/platform-map @messai/platform-map — this map: the /decks/platform-map deck and the onboarding atlas render the same data
libs/feature/lab-cad @messai/lab-cad — parametric MES design graph, validators and preview compiler
@messai/database
data-access lib
libs/data-access/database
Prisma 6.11 · server-only entry
Single Prisma client. Server contexts import @messai/database/server; there is no db export. Client-safe Zod schemas only outside server modules.
models
126 · 88 enums · 69 migrations (2026-10-20)
schema
prisma/schema.prisma
Computed JSON artifacts
build-time artifacts
apps/web/public/data/computed/*
priors v1+v2 · calibration · dag-snapshot
Prebuilt outputs of the quality/ML scripts, committed to git and served statically. API routes under research/* and parameters/[slug]/* read DB-first with these as fallback (60s ISR).
hierarchical-priors-v2.json — served by /api/ml/predict
All corpus acquisition, extraction, quality refresh and model refits are standalone scripts run by hand or by the weekly Claude routine. There is no worker host.
gate
resolveDbTarget() · scripts/lib/db-target.ts
targets
staging (default for reads) | prod (--expect-ref) | local (stack retired 2026-10-01)
Weekly Claude routine
scheduled job · no run evidence in tree
scripts/routines/weekly-ml-audit.sh
6 steps · Monday · commits npe-health.json
batch · weekly
Replaced two GitHub Actions crons (npe-nightly, ml-retrain) that burned ~1,350 min/month. Runs in a Claude remote environment; commits only npe-health.json when it changed. No npe-health.json exists in the repo, so no committed run has landed yet; the 2026-09-03 commit that added step 5b was a dry-run.
No lint/test/build CI. Validation is local via husky pre-commit/pre-push and pnpm pre-deploy. Three workflows remain, all hand-triggered.
changesets.yml — version PRs
sync-public-mirrors.yml — push open-source/* to Messai-io/MESS-*, publish npm/PyPI via OIDC
fit-priors-v2.yml — OOM-safe priors refit
State · storage & rate limits
Supabase Postgres 17 + pgvector
primary store
prod · ref in env file
staging · ref in env file
live · prod
One schema, two live environments, staging and prod; local dev points at staging since 2026-10-01 (the :54322 local stack is retired). Pooled DATABASE_URL :6543 for the app, DIRECT_URL :5432 for migrations and bulk. Staging and prod share the pooler host — writes gate on the project ref.
pdfs/ · 8,445 papers with a PDF (staging, 2026-09-10)
source of truth for PDF bytes
live · since 2026-08-14
Local papers/pdf-storage/objects/ is only a cache. Hydrate before any job that reads PDFs off disk.
hydrate
scripts/papers/hydrate-pdfs-from-r2.ts
verify
scripts/storage/r2-verify-backups.ts
column
ResearchPaper.r2Key
Upstash Redis · messai-ratelimit
rate-limit store
@messai/rate-limit · token buckets
apps/web proxy · apps/api routes
live · per request
Token buckets for every /api/* request in the apps/web proxy, and per-route budgets in apps/api (chat, sweep, MCP tools). The store is the Marketplace database messai-ratelimit, connected 2026-10-01 (libs/shared/rate-limit/src/limiter.ts); with no store configured the limiter lets every request through, as in local dev. Whether the prod env is set was not checked from this machine. This box used to be the BullMQ queue scaffold: it never enqueued a job, its processors were unfinished stubs and no worker host existed. It was archived on 2026-10-02 (archive/2026-10-bullmq-scaffold/).
Inference & models
AI Gateway + model providers
external LLM APIs
Chat: Sonnet 4.6 via AI Gateway (default) · Gemini 2.5 Flash · Groq GPT-OSS 120B
Extraction: AI Gateway (default) · Claude CLI · Gemini · Groq · Ollama (local) · Cerebras
Chat goes through the Vercel AI Gateway (Sonnet 4.6 by default) with provider fallback gateway → gemini → groq. Extraction runs on the AI Gateway by default, or per run on Claude CLI, Gemini, Groq, Ollama (local) or Cerebras. Extraction costs ~$0.05–0.10 per paper.
Semantic search embeds the query live via router.huggingface.co, then pgvector cosine on abstract_embedding. Batch backfill uses the Docker TEI service instead.
call site
libs/shared/ai-chat/src/lib/embed.ts
env
HUGGINGFACE_API_KEY
GP-SCM on Fly.io · messai-gp-scm
inference service · deployment not verified
services/ml-engine/Dockerfile.gpscm · :8002
12/27 MFC nodes fitted (2026-07-31)
batch · env-gatedlive · ?hybrid=true
Gaussian-process structural causal model over the named parameter DAG. Reached from /api/ml/predict behind the hybrid opt-in via GP_SCM_SERVICE_URL. A blank value darkened it for ~7 weeks in 2026-07; the client now names that case in its fallback reason. Whether the Fly app is up and the prod env is non-blank was not checked from this machine. Trains with scikit-learn, not torch. Served pickle carries zero non-zero physics means, so no redeploy was warranted after the 2026-07-31 fit.
served pkl
gp-scm-fitted-named-db-2026-06-07.pkl
trainer
services/ml-engine/train_gp_scm.py
ML engine (Docker, local/batch)
batch services
services/ml-engine · :8001
embed · nougat · pgmpy · npe · training/
batch · pnpm ml:dev
FastAPI + Python: batch embeddings (HF TEI), Nougat OCR, pgmpy fitted posteriors (cached JSON, no live server), NPE simulator, hierarchical priors trainers, conformal calibration. Runs from docker-compose.ml.yml with its own postgres/redis/mlflow for experiments.
dockerfiles
Dockerfile · .gpscm · .nougat · .npe
Request and batch paths · 26 edges
From
To
Path
Kind
Researcher browser
apps/web
HTTPS messai.io
live request path
apps/web
apps/site
rewrite /about /learn …
live request path
apps/web
apps/lab
rewrite /lab /models …
live request path
apps/web
apps/api
rewrite /api/* · all writes
live request path
AI chat & agents
apps/api
POST /api/chat
live request path
apps/web
@messai/database
server reads
server-component / build-time read
apps/lab
@messai/database
server reads
server-component / build-time read
apps/api
@messai/database
reads + writes
live request path
@messai/database
Supabase Postgres
Prisma · pooled :6543
live request path
apps/api
Cloudflare R2
PDF bytes
live request path
apps/web · api
Upstash Redis
rate-limit buckets
live request path
apps/api
AI Gateway
chat + tools
live request path
apps/api
HF Inference Router
embed query
live request path
apps/api
GP-SCM on Fly.io
?hybrid=true
live request path
apps/api
Computed JSON artifacts
JSON fallback · ISR 60s
server-component / build-time read
apps/web · lab · api
@messai/* shared libs
imports @messai/*
server-component / build-time read
apps/api
next-auth
sessions
live request path
Operator scripts
Supabase Postgres
sync scripts · DIRECT_URL :5432
batch or script
Operator scripts
Cloudflare R2
hydrate / migrate
batch or script
Operator scripts
AI Gateway
extraction LLM calls
batch or script
Weekly Claude routine
Computed JSON artifacts
refits → commits JSON
batch or script
Weekly Claude routine
GP-SCM on Fly.io
GP-SCM fit
batch or script
GitHub Actions
Computed JSON artifacts
fit-priors-v2
batch or script
GitHub Actions
ML engine
workflow_dispatch
batch or script
ML engine
Supabase Postgres
batch embed → pgvector
batch or script
Computed JSON artifacts
apps/web
static /data/*
server-component / build-time read
02Site map & data flow · Every page, the zone that answers it, and the tables behind it
Every page MESSAI serves at messai.io, by product area, the zone that answers it, and the API
handlers and database tables behind it. It is read off the source when the site builds, so it
cannot drift from the code: a page added to any zone shows up here on the next deploy, a page
that builds but never serves is called out rather than listed as live, and a call that cannot
work is flagged where it is made. All 178 URLs are also served in German under
/de/.
178
URLs with a page
web 122 · lab 22 · site 34
21
record templates
[id] · [slug] — one page per row
28
behind sign-in or admin
proxy.ts · requireAdmin()
37
in the header or footer
@messai/ui nav-data.ts
223
API handlers
apps/api · not pages · see 01
135/136
answered as expected
live probe · 2026-10-19
How each page reaches the database
The same pages, followed through the code: which /api/* handler each one calls,
which Prisma models that handler reads or writes, and which models a server component reads
itself. Pick a page to see everything behind it, or a table to see every page that depends on
it. A call to an endpoint that does not exist, a method the handler does not export, a link to a
page nobody serves, or a diagnostic handler left open is marked where it happens.
246
page → API links
66 pages call apps/api
37
pages read Postgres directly
server components · reads only
72/128
Prisma models in use
42 written · 56 only scripts touch, or nothing
74
handlers nothing calls
of 218 · public v1 API, diagnostics, unused
0
broken interactions
listed under “What the map surfaces”
Loading the flow map…
Every page, by product area
messai.ioapps/web is the entry · /lab, /api and the marketing paths are rewritten to their zones
live 122 sign-in 7 admin 20 redirect 16 feature flag 6 dev only 7 broken 0 bar = a section's pages by status · number = pages
200 live probe: the page rendered307 a hop, refusal or 404 its status predicts200 · 2.4 s over the 2 s budget404 not what it should answer probed https://www.messai.io on 2026-10-19 · [id] templates are not probed
The whole site on one board: messai.io, its product areas, and every top-level section with
its pages coloured by status. Click a section for its pages, each with the zone that serves
it and the code messai.io answered. Statuses are read from the route trees at build on
2026-11-20; the codes are as fresh as the last probe.
Platform · the corpus
13 sections · 36 pages
Search, read and interrogate the paper corpus and what was extracted from it.
Computed with the map, so this list is as current as the build. A defect is a
page that cannot be reached, a chrome link that sends the reader somewhere it should not, or an
interaction that cannot work: a call to an endpoint nobody answers, a method the handler does not
export, a link to nothing, a diagnostic handler left open to anyone. The by-design overlaps are
listed so nobody “fixes” them.
No defects at build.
1 route answered unexpectedly at
the live probe (2026-10-19)
/papers · redirect — messai.io answered 200
6 latent — in code no page, layout or
chrome imports
No page, layout or chrome imports these files, so nothing a reader does can hit them — some
are dead code, some are run only by a script (a seed, a backfill). They break the day a page
imports them: fix the call, or delete or move the file.
database write outside apps/api — Writes Experiment from apps/web; the write belongs behind an apps/api route. apps/web/src/lib/server/seed-dashboard-ontology.ts
database write outside apps/api — Writes MethodologyPreset from apps/web; the write belongs behind an apps/api route. apps/web/src/lib/server/seed-dashboard-ontology.ts
database write outside apps/api — Writes MFCDesign from apps/web; the write belongs behind an apps/api route. apps/web/src/lib/server/seed-dashboard-ontology.ts
database write outside apps/api — Writes Project from apps/web; the write belongs behind an apps/api route. apps/web/src/lib/server/seed-dashboard-ontology.ts
database write outside apps/api — Writes Run from apps/web; the write belongs behind an apps/api route. apps/web/src/lib/server/seed-dashboard-ontology.ts
database write outside apps/api — Writes User from apps/web; the write belongs behind an apps/api route. apps/web/src/lib/server/seed-dashboard-ontology.ts
URL
Overlap
Why it is fine
/
zone root
apps/lab/src/app/page.tsx answers only at the lab zone’s own deployment; messai.io/ is apps/web’s home page.
/
zone root
apps/site/src/pages/index.astro answers only at the site zone’s own deployment; messai.io/ is apps/web’s home page.
/parameters/sweep
local-dev fallback
apps/web/src/app/[lang]/parameters/sweep/page.tsx forwards to /parameters?tab=sweep under next dev; in production messai.io hands /parameters/sweep to apps/lab.
Retired URLs
Old addresses that 308 to a live page, so inbound links keep working. They are redirects in
config, not page files, so they are not on the board.
How it is built.apps/site/src/lib/site-map.ts walks
apps/web/src/app/[lang], apps/lab/src/app and
apps/site/src/pages, decides the serving zone from
apps/web/multi-zone-rewrites.json, the sign-in gate from proxy.ts, the
admin aliases and retired URLs from next.config.js, and nav membership from
nav-data.ts. A new top-level section lands in “Unfiled” until it gets a one-line
description there. tools/lint-multi-zone-paths.ts warns about the same shadowing at
commit time.
apps/site/src/lib/data-flow.ts then follows each page’s imports — its nested
layouts, components and the @messai/* libs they use, minus what the zone’s root
layout already loads — and collects every /api/… URL, the method of the
fetch() carrying it, and every prisma.<model> call and raw-SQL
table. It reads each apps/api handler’s methods, guard and models the same way, and
every model from prisma/schema.prisma. It is static analysis: a URL assembled
wholly at run time is invisible to it, so the links it draws are a floor and a missing link is
not proof of absence. A new API namespace lands in “Other” until it is filed in
API_FAMILIES there.
Four lanes, read top to bottom. Every script is dry-run by default and needs --apply --target to write. The scheduled part is lanes 3 and 4: the weekly Claude routine refits priors, effects, calibration and GP-SCM. Discovery, download and LLM extraction are still hand-run; the GitHub job-DAG that would automate them is a design, not code.
A paper enters as a DOI, becomes a PDF in R2, becomes text, becomes extracted values, becomes canonical SI rows, and finally becomes a prior or an embedding that a route can serve. Every arrow drawn dashed below is a script someone runs by hand.
live request path server-component / build-time read batch or script dormant script store external
Four lanes, top to bottom: acquisition, parsing and extraction, quality and embeddings and refits, then serving. Every dashed arrow is a script an operator runs by hand.
1 · Acquisition — scripts/acquisition/weekly_pipeline.sh (7 steps, dry-run by default)
OpenAlex
external API · discovery
from_updated_date cursor
papers/staging/last-sync.json
The only stage nobody pushes to you, so it is poll-based. Weekly step 2 discovers new DOIs since the cursor; search-gaps-openalex.ts (2026-09-03) runs gap queries into papers/acquisition/gaps-<date>.json and the admin route records a GapSearchRun.
Bounded to 2,000 per tier per run. curl_cffi impersonates Chrome to get past MDPI/Wiley/ACS/Elsevier 403s. 2,075 no-DOI papers remain unreachable by this path.
Content-addressed by pdfHash. Since 2026-08-14 the bytes live on R2 and the local store is a cache; migrate-local-to-r2.ts / backfill-r2-keys.ts keep ResearchPaper.r2Key populated.
R2 · messai-papers
object store
8,445 w/ PDF · staging 2026-09-10
Source of truth for PDF bytes.
Sync papers → DB
script · DB write
sync-papers-to-db.ts
pdfHash link · taxonomy · gated
batch · gated
Creates or links ResearchPaper rows. Mutation gate mirrors the whole pipeline: dry-run unless --apply --target {local|staging|prod}; prod requires --expect-ref.
ResearchPaper
table
23,568 rows (local 2026-07-06)
86 relation edges in schema (2026-10-07)
Hub of the schema. Carries pdfStoragePath, r2Key, aiSummary, taxonomy columns (primarySystemType TEXT), demo content, and the pgvector abstract_embedding.
Pulls the needed PDFs from R2 into the local cache before any extraction cohort runs.
Parse
OCR / parse
Nougat OCR (Docker) → .mmd
PMC XML → text (pmc-xml-to-text.ts)
batch · manual
Nougat runs as an overnight batch via pnpm nougat-batch. 1,444 BioC-PMC XML files are parsed by an existing parser but not yet re-extracted (cost-gated ~$70–150).
server
services/ml-engine/nougat_server.py
out
papers/nougat/<doi>.mmd
v2 value extractor
LLM extraction
simple_value_extractor.ts → values_v2
Haiku → gemini → groq → ollama
batch · $0.05–0.10/paper
The active extractor (v1.6 orchestrator deprecated 2026-05-08). Writes JSON under papers/extracted/<aa>/<sha>/; every run must end with its sync exiting 0 (Rule §7). 9,511 papers done as of the last full run.
fallback
docs/extraction/provider-fallback-2026-05-09.md
smoke
scripts/extraction/phase6-smoke-test.ts
Overnight jobs A–E
orchestrator
pnpm overnight:run
XML→v2 · equations · figures · overview
batch · manual
Five sequential jobs against the local corpus, ending in job E which syncs all four artifact types to the DB. Ollama-backed with provider fallback; manifest survives SIGTERM.
runbook
docs/runbooks/overnight-pipeline.md
Legacy Claude/Gemini scripts
older extractors
extract-tables-claude.py
digitize_figures_gemini.py · …
dark · ad hoc
Still present and runnable; hard-code claude-sonnet-4-6 (P1 cleanup). Populate ExtractedTableData / ExtractedFigureData / ExperimentalContext.
Sync extractions → DB
script · DB write
sync-values-v2-to-db.ts · sync-*-to-db.ts
with extractorVersion · snippet · confidence
batch · gated
Lands rows with full provenance. audit-disk-vs-db.ts fails pre-deploy on disk-only drift. Launch-blocker fields (derivationMethod, uncertainty±, catholyteBuffer) are proper columns, not JSONB.
ExtractedParameterData
table
196,522 rows · 25,988 modelable
80.7% NULL canonical_slug (local, 2026-06-30)
Per-paper extracted values with conditions, canonical slug, SI-normalized numericValue, verifierPassed. Staging measured 55% of rows with a NULL canonical_slug (109,378 of 199,896) on 2026-09-07. The binding constraint on modelability is canonicalization coverage, not extraction.
Extracted{Table,Figure,Paper}Data
tables
ResearchPaperEquation · ConditionSet
ExperimentalContext · ReactorGeometry
Typed sidecar tables linked by paperId. ConditionSet carries phAnolyte/phCatholyte/reference electrodes as columns; ReactorGeometry has ~47 typed columns.
Idempotent, dry-run by default. Volumetric densities route to their own kinds so they never pool with areal values in priors. Propagation order is staging → prod (local dev reads staging since 2026-10-01), additive and ref-checked.
normalizer
scripts/quality/normalize-to-si.py
canonicalize
canonicalize-name.ts
Priors & calibration refit
ML training
hierarchical_priors_v2.py (served) + v1 (pages)
split-conformal calibration · PPC on held-out
batch · weekly routine
Steps 6–9 of refresh-all. v2 is Student-t, per-class stratified, nutpie sampler; the full fit must use the OOM-safe batched runner. Never ship a FAST-mode artifact. Both v1 and v2 must be refit together.
batched
training/run_priors_v2_batched.py
benchmark
bes-benchmark-v1 (paper-disjoint, 2026-09-02)
Within-paper effects + KG
derived research
two-tier effect fit, DB-fed (2026-09-03)
build-correlations-db.ts · LearnedDagEdge
batch · routine 5b
Effects now fit from the DB, not just the table CSV, with gap records feeding the OpenAlex gap search. KG correlation matrix is slug-keyed Pearson + Spearman.
embed_papers.py
embedding backfill
bge-large-en-v1.5 → abstract_embedding
HF TEI Docker :8001
batch · manual
Batch backfill of the pgvector column. If the service is down the embedding is silently skipped and nothing retries.
GP-SCM fit
ML training
train_gp_scm.py → .pkl → Fly image
batch · weekly
12/27 MFC nodes fitted after the present-parent fix; binding constraint is joint-data coverage.
runFullPrediction reads priors v2, conformal calibration, OOD detection and runtime physics validation. Non-MFC classes route to the analytical predictor; MFC keeps the data-tuned path.
UI · apps/web · apps/lab
surfaces
/research · /parameters · /protocols · /lab
live · browser
Semantic search: live query embedding → pgvector cosine → hydrate rows. New extractions appear instantly; prebuilt artifacts need a redeploy or pnpm regenerate.
corpus-refresh.yml (proposed, not landed)
proposed automation
GitHub job-DAG · cron 0 2 * * 1
discover→acquire→extract→sync→embed
dark · design 2026-05-30
The design in docs/corpus-refresh-architecture.md. Not implemented: the workflows directory holds only changesets, sync-public-mirrors and fit-priors-v2. Acquisition and extraction remain manual; only refits are scheduled (weekly Claude routine).
Pipeline edges · 26 edges
From
To
Path
Kind
OpenAlex
Acquire PDFs
new DOIs
batch or script
Acquire PDFs
Promote to canonical store
downloaded/
batch or script
Promote to canonical store
R2
upload · r2Key
batch or script
R2
Sync papers → DB
manifest
batch or script
Sync papers → DB
ResearchPaper
insert / link
batch or script
R2
Hydrate PDFs
pull cache
batch or script
Hydrate PDFs
Parse
PDFs
batch or script
Parse
v2 value extractor · Overnight jobs
.mmd / text
batch or script
Parse
Legacy Claude/Gemini scripts
ad hoc
dormant
v2 value extractor
Sync extractions → DB
values_v2.json
batch or script
Overnight jobs A–E
Sync extractions → DB
job E
batch or script
Legacy scripts
Extracted{Table,Figure,Paper}Data
tables · figures · context
dormant
Sync extractions → DB
ExtractedParameterData · sidecar tables
rows + provenance
batch or script
ExtractedParameterData
refresh-all.sh
reads EPD · writes slug, SI value, verifierPassed
batch or script
refresh-all.sh
Priors & calibration refit
steps 6–9
batch or script
Priors & calibration refit
Within-paper effects + KG
then
batch or script
Within-paper effects + KG
GP-SCM fit
then
batch or script
ResearchPaper
embed_papers.py
abstracts
batch or script
Priors & calibration refit
Computed artifacts (git)
priors · calibration
batch or script
Within-paper effects + KG
Computed artifacts (git)
effects · dag
batch or script
GP-SCM fit
apps/api routes
pkl → Fly
batch or script
Computed artifacts (git)
apps/api routes
JSON fallback
server-component / build-time read
ExtractedParameterData
apps/api routes
DB-first reads
live request path
apps/api routes
UI · apps/web · apps/lab
fetch /api/*
live request path
embed_papers.py
UI · apps/web · apps/lab
pgvector cosine
live request path
Within-paper effects + KG
OpenAlex
gap records → gap search (5b)
batch or script
The order is not optional
Coupling hygiene comes first. The 807-paper run left 24,540 orphaned condition sets behind it. A large run started before the backfill is fixed reproduces that at roughly ten times the scale, and no later cleanup recovers which values belonged together.
04Corpus, extraction, ontology · Four extractors, and one open decision
A paper is classified on six axes by three tiers of writer, so the same field can be set by the extractor, by a rule, or by a human, and the tier is what decides who wins. A value passes five ontology layers before it is modelable: raw name, alias, canonical slug, SI unit, and the verifier. The atomic unit for modeling is the experiment record, not the paper. Grading a paper as complete tells you almost nothing about whether any single experiment inside it can be modeled.
Four extractors
Extractor
Status
What it does, and what bites
v1.2
deprecated
Deprecated 2026-05-07 by c1804deb2. Its nested schema does not emit on tool-use models, which is why it was retired. The public methodology page still documents it as current, and ships that description twice.
v2
active
Flat schema, about $0.05 per paper. Header and values are fetched in two separate calls because Haiku emits a two-key response unreliably when asked for both at once.
3-pass extract-with-conditions
never run
Experiment-centric, which is the shape modeling actually needs. Pass 1 hits the same nested-schema bug as v1.2; pass 3 over-rejects. On 2026-09-08, computing the growth rate as ln2 divided by doubling time validated three values the verifier had rejected.
CMA v3
measured
About $0.93 per paper, with 100% coupling measured on its sample. Its loader is local-only, so nothing it produces reaches a shared database yet.
The one open decision
All three live options extract the same papers. They differ by an order of magnitude in cost and in whether the output can be coupled into experiment records at all.
Option
Per paper
8,743 legacy papers
What it buys
v2
$0.05
~$440
Values with provenance. Coupling stays as poor as it is today.
3-pass
$0.12
~$1,050
Experiment records, once the pass-1 schema is flattened and pass 3 stops over-rejecting.
CMA v3
$0.93
~$8,100
Full coupling as measured, but the loader has to land first.
For the 8,743 legacy papers, no backfill can recover coupling. The information about which values belonged to the same experiment was never captured at extraction time, so it has to be re-extracted or given up.
Each figure is drawn once, where its subject lives, and mirrored here by the page at load so this section reads as one sheet. The source section is named under each.
05Open source · 9 packages · edit inside the monorepo
9
packages in open-source/
workspace:*
835
parameters · 15 categories
mess-parameters v0.3.0
349
refs to mess-parameters
apps/libs/scripts
$0
Actions spend
dispatch-only
Since the 2026-04-25 consolidation every package lives in this repo; the public Messai-io repos are read-only mirrors pushed by hand at release time. mess-parameters is the heavyweight: the product reads its ontology at build time and the DB syncs extracted values back into it. Dataset blobs never enter git or npm: the catalog ships manifests, the bytes live on Hugging Face Hub.
live request path server-component / build-time read batch or script
The nine packages in open-source/ are the source of truth; the Messai-io repos, npm, PyPI and the Hugging Face Hub are downstream, reached only through the workflow_dispatch mirror.
open-source/ · 9 packages · workspace:*
Package
Version · license · files
What it is
Mirror · refs
mess-parameters
v0.3.0 · CC-BY-4.0 · 1,444
Standardized parameter ontology and analysis tools: 835 parameters across 15 categories. data/parameter-definitions-rich.json (pinned v0.2.0 for fixtures) plus SCIENTIFIC_INTEGRITY.md (power density CoV ≈1,285%).
parameters/*.md ontology
data/paper-parameter-values.csv — mirror of DB extractions
The product reads packages at build time (fixtures), at seed time (materials, microbes), and at runtime (datasets manifests → HF Hub).
Supabase Postgres
store
ParameterDefinition · Material · Microbe
ExtractedParameterData
ParameterDefinition is edited in the DB and synced back to mess-parameters; materials and microbes are seeded from their packages.
Releases · pnpm changeset
release mechanism
.github/workflows/changesets.yml
tools/lint-package-shape.ts
batch · dispatch
Changesets version PRs; canonical package shape enforced by the linter. Rollback = git revert in open-source/* then re-run the mirror.
sync-public-mirrors.yml
GitHub Action
workflow_dispatch · package input
pnpm publish + PyPI via OIDC
batch · manual, $0
Pushes open-source/<pkg> to its Messai-io repo with a tag, then publishes. Kept on GitHub because OIDC trusted publishing only works there. Auto-triggers were stripped to hold Actions spend at $0.
Public · downstream, read-only
github.com/Messai-io/MESS-*
public GitHub org
9 public mirror repos
read-only downstream
MESS-Parameters, MESS-Materials, MESS-datasets, MESS-Agents, MESS-Hypotheses, MESS-Learning, MESS-Microbes, MESS-Methods, MESS-Simulations. Contributions from the public flow back via docs/contributing-from-public.md.
npm · @messai-io/*
registry
8 packages · pnpm publish
PyPI · mess-methods
registry
OIDC trusted publishing
Hugging Face Hub
blob host
datasets/messai-io/mess-datasets
108 files · 27 MB · 23 records (2026-04-25)
Large dataset blobs (PDFs, CSVs, images) referenced by download_url in each manifest; consumers verify the md5 checksum after download.
ResearchPaper (86 relation fields) is the hub; User (46), Experiment (34), Microbe (26), ParameterDefinition and ConditionSet (22 each) follow (counted 2026-10-07). ResearchPaper.abstract_embedding and PaperChunk.embedding are the two pgvector columns. Schema rule §8: any field that a UI filter, ML feature or WHERE clause touches is a typed column, never JSONB.
The plate below was frozen from the original Platform Map artifact when the schema had 117 models; it has 126 today, and the domain table under the plate lists every one.
The 117 Prisma models present when this layout was frozen, and their related pairs, coloured by domain; node radius is the relation-field count. ResearchPaper is the hub. The layout comes from the original artifact's force simulation; the deck shows the same models as a table.
073D modeling · A recipe DSL, a parts library, and four registries that must agree
27
built-in electrode recipes
@messai/electrode-3d · 2026-09-08
32
reactor scene files
apps/lab · components/models/
4
registries a new model must join
guard test cross-checks them
3
geometry tiers from a paper
full · partial · none
The 3D surface is not one system. It is a small declarative recipe language for electrodes, a parts library for reactor vocabulary, thirty-two hand-authored reactor scene files, and two independent consumers that render them. Most 3D bugs reported as "the model is broken" are really a registration miss or a missing recipe entry, and the tell differs by consumer.
electrode-recipes.ts with getBuiltInElectrodeRecipe, validated by GeometryRecipeSchema from @messai/ai-chat/geometry-recipes.
Parts and renderer
same lib
recipe-builders.tsx with RecipeRenderer, parts.tsx, electrode-canvas-pool.ts (a WebGL context pool bounded by POOL_LIMIT), ElectrodeViewer3D.tsx, and ElectrodeFallback2D.tsx.
Promoted out of apps/site on 2026-08-10. Holds reactor-parts.tsx, flows.tsx for particles, configurations.tsx, label.tsx, and rig.tsx for studio lighting.
Reactor scenes
apps/lab/src/app/lab/components/models/
32 model component files plus shared/, which holds MESSModel, the electrode anchor, MESSFlows, the flow physics, and the industrial process parts.
Consumers
apps/lab and apps/web
The lab catalog and /lab; the Atlas 3D view and the paper 3D tab in apps/web. Runtime peers are react, three, @react-three/fiber and @react-three/drei, and every consuming app must list the lib as a workspace:* dependency or the build cannot resolve three.
Five rendering layers, and the separate paper-specific path that turns extracted conditions into a scene. Measured 2026-09-08.
b · The recipe DSL
31 built-in recipes cover seven kinds: cloth, brush, plate, foam, mesh, gdl-stack, and granular. A recipe is data, not code, so a new electrode material is usually one object rather than a new component.
AI-generated recipes land in the AiGeometryRecipe model at prisma/schema.prisma:4060 and are validated by the same GeometryRecipeSchema before they render. LabConfigurationSnapshot at prisma/schema.prisma:4113 stores aiRecipeSlugs, aiMaterialSlugs, and aiMicrobeSlugs, so reopening a saved configuration hydrates the exact recipes it used without re-scanning anything.
c · Adding a reactor model touches four registries
Miss one and the failure is silent, which is why there is a guard test. The easiest to miss is the second row.
The guard test at apps/lab/src/app/lab/model-registration.test.ts cross-checks all four registries and baselines six models that render but have no catalog entry. Shrink that list; do not grow it.
Testing these registries is not free: React 19 throws on PascalCase R3F intrinsics (<cylinderGeometry>, <meshStandardMaterial>) inside jsdom, so a geometry tree cannot be mounted in a Jest test — only lowercase host elements (<group>, <mesh>) are tolerated. model-registration.test.ts above works around this by asserting on the registration contract, not the rendered scene; do the same and assert on pure helpers elsewhere. The one check that actually renders the geometry is pnpm --filter messai-lab build (webpack).
d · Two consumers, one tell
The catalog and Atlas viewer goes through ElectrodeViewer3D, which renders a recipe via RecipeRenderer and getBuiltInElectrodeRecipe. It is reactor-independent: it draws the electrode and nothing else. Reactor models render the same electrodes either through RecipeRenderer driven by electrode slots, or through older per-material switch cases inside the model file. The tell tells you where to look: a fallback blob in the catalog means a missing entry in the built-in recipes; a fallback blob inside a reactor means a missing case or slot in that model file.
e · Paper-specific 3D is real
The 3D config route reads ExperimentalContext and ConditionSet for a paper and returns chamber and electrode dimensions, materials with a colour hint, baseline conditions, and a recommended template, at one of three tiers: full geometry, partial geometry, or no geometry. Alongside it, scripts/extraction/digital_twin_matcher.ts is a deterministic post-extraction matcher that emits a V1DigitalTwinSpec for each condition set, so the mapping from extracted numbers to a scene is reproducible rather than model-generated.
Two geometry tables, not unified
ReactorGeometry at prisma/schema.prisma:830 carries roughly 47 typed columns and feeds the resource-recovery demo and the quality scripts. The 3D config route reads ExperimentalContext and ConditionSet instead. Two tables describe reactor geometry, each has its own consumer, and nothing reconciles them.
f · Particle and flow rules
Follow these or the animation reads as wrong
Reset rising particles at the liquid surface derived from the current liquid level, never at a hard-coded constant.
Scale every translation inside useFrame by delta, or the animation speed follows the monitor's refresh rate.
Fluidized beds recirculate, with the core rising and the annulus settling. They never teleport particles back to the bottom.
Tie particle speed to a clamped physical driver, so an extreme input slows or saturates rather than producing a blur.
March inline particle arrays inside useFrame; do not rebuild the array each frame.
Shared industrial parts live in shared/process-parts.tsx: FlangedPipe, GateValve, AccessLadder, GearedMixer, DiffuserHeader, BlowerSkid, and RakeBridge, among others.
g · Parametric CAD
The schema-driven CAD layer is @messai/lab-cad at libs/feature/lab-cad, and it is reachable two ways. It is opt-in per model through ?cad=1 on /lab, and it has a standalone route at /lab/cad-preview, backed by apps/lab/src/app/lab/cad-preview/page.tsx. That page is the Phase 1.5b smoke surface: it renders a default H-cell Design through DetailedMFCModel with a single chamber-length slider, end to end from Design through applyPatch and compilePreview to Three.js. Three families are implemented: h-cell, single-chamber-air-cathode-mfc, and wastewater-unit-process. Eight models are CAD-wired, five are dual-prop-ready, and 17 are unmigrated. The layer is additive: the legacy JSX scene is preserved and still renders when the flag is off.
Flagged this pass · 2026-09-08
libs/shared/mes-3d/README.md is cited by that library's own index.ts as the authoritative aesthetic specification, and it does not exist on disk. It was most likely lost in the 2026-08-10 promotion out of apps/site.
The apps/site scroll-driven 3D homepage, roughly 5,600 lines, is unreachable because / is not in the site rewrite block.
Older switch-case electrode rendering still coexists with RecipeRenderer, so the same material can be drawn by two different code paths.
Two model families look alike and are not. MESSModel-wrapped electrochemical scenes and standalone process or wastewater scenes share a visual language but not a contract, and MESSFlows does not apply to a digester.
08Process flow and P&ID · A real library, and one deck that ignores it
25
ISA-5.1 symbols
@messai/pid-schematic · on main
19
model sheets
MODEL_SHEETS · getModelPidSpec(id)
341
hand-placed lines in the deck diagram
ProcessFlowDiagram.tsx · imports nothing
Read this first · corrected 2026-09-08
There is a P&ID system, and it is on main: @messai/pid-schematic, with an ISA-5.1 symbol set, a declarative spec, a lint pass, tests, and two live consumers in the lab. It is not on the feat/corpus-derived-recommendations branch, which is why an inventory taken against a working tree reports it missing. Check your ref before concluding a subsystem does not exist.
What is genuinely disconnected is the deck artwork. ProcessFlowDiagram.tsx is still 341 hand-placed lines and imports nothing from the library. Two things that draw process flows exist side by side and share no code.
The P&ID library, on main
Landed in commits d219764d7 and 887428acf, the second of which added a sheet for every 3D model and a P&ID tab on the model page. The sheet is data: a PidSpec goes in, a drawing comes out, and a linter checks it. That is the property the hand-drawn diagram lacks.
lintPid and formatLint. A sheet reports tagged-item and instrument counts and its own problems, so a wrong drawing fails loudly instead of just looking plausible.
MODEL_SHEETS covers 19 models, reached through getModelPidSpec(id). Two worked examples ship alongside: dual-chamber MFC and MEC hydrogen.
Consumers
apps/lab
The per-model P&ID tab in the catalog detail panel, and the standalone /lab/schematic gallery which renders every example with its lint report.
Four test files guard it, including model-sheets.test.ts, which is what stops a catalog model shipping without a sheet. The library is wired into apps/lab and apps/web through transpilePackages, workspace dependencies and tsconfig paths, documented in CLAUDE.md, and has a companion skill at .claude/skills/mes-pid-schematic/ carrying the ISA-5.1 and blueprint-style references.
DiagramPane.tsx is where the two systems above — the reactor scenes and this P&ID library — actually meet in one component. It renders a View switch labelled 3D / P&ID / Split, plus a Blueprint / Classic sheet theme, both persisted so a researcher’s pick follows them from the catalog detail tab (DiagramTab.tsx) to the lab workbench (CanvasFrame.tsx). It deliberately renders no toggle at all when getModelPidSpec(modelId) returns nothing — just the 3D scene and a note that no sheet has been drawn for the model yet, never a Split view with an empty pane.
Hand-authored SVG on a 0 0 1000 400 viewBox. Two lanes, waste-to-value and DAC, converge on a MESSAI core box and emit product chips. Carries role="img" with a full aria-label. Not data-driven: every rect is placed by hand.
DAC physics and techno-economics, with zero diagram output. The deck that draws the DAC lane imports none of it.
Nothing in the diagram.
As drawn in the deck: illustrative, no live values. Redrawn here from ProcessFlowDiagram.tsx, 2026-09-08.
What is actually left to do
The three things the old version of this section asked for already exist: the symbol set, the data-driven renderer, and a second consumer. What remains is connective work.
Get the branch current. The library is on main and absent from feat/corpus-derived-recommendations, so anyone working from that branch cannot see it and will build a fourth diagram by hand.
Decide the deck's fate. Either redraw the DAC lanes as a PidSpec and render it through PidSheet, or keep it as deliberate marketing artwork and say so in a comment. What it must not be is an undeclared third rendering path.
Feed the sheets real numbers. MODEL_SHEETS is static per model; the Process TEA stream table is the obvious source for stream values, and wiring the two would turn a concept sheet into something a process engineer can check.
Close the 19-of-32 gap. Nineteen models have a sheet and there are 32 model files, so the catalog fallback still renders for the rest.
Decide placement in the lab. A P&ID tab, the /lab/schematic gallery, and ArchetypeViewer3D now show overlapping views of the same archetype in three idioms. That is one more than a reader needs.
Do not extend ProcessFlowDiagram.tsx in place, and do not start a new symbol set. The library is the vocabulary now; a one-off that grows is how a codebase ends up with two of everything.
The ranked gap register lives in one place:Part I · 17 Open gaps, on the platform's own P0 to P2 scale (P0 blocks the corpus machine, P1 bounds what can be modeled or served, P2 is hygiene), kept current. The deck at /decks/platform-map lists the platform map's own shorter set, from the same data as this part. What this section keeps is what has been resolved since the source documents were written.
Resolved since the docs were written (verify before re-flagging)
Chat bifurcation — one canonical /api/chat (2026-05-12).
BullMQ queue scaffold archived (2026-10-02, archive/2026-10-bullmq-scaffold/): it never enqueued a job and had no worker host; background work uses Next after() or Vercel Queues.
Sources: docs/platform/00-architecture.md (verified 2026-07-06) · 05-data-flow.md (2026-05-06) · 06-infrastructure-gaps.md · docs/corpus-refresh-architecture.md (2026-05-30) · docs/routines/weekly-ml-audit.md · archive/2026-10-bullmq-scaffold/ARCHIVE_NOTE.md · docs/agent-guide/stack.md · CLAUDE.md · CLAUDE.local.md · prisma/schema.prisma. Page, route, model, lib and rewrite counts re-measured from the development tree on 2026-10-07 (first measured 2026-09-03); related pairs and relation fields are counted from prisma/schema.prisma the way the artifact counted them (146 pairs on 2026-09-03). Corpus counts carry their own dates — re-measure before quoting (scripts/check-actual-database-stats.ts). Live surfaces referenced by the deck: /admin/observability · /parameters/knowledge-graph · /decks/bes-benchmark
10Roadmap and sequence · Dependency order, not preference order
Each step below unblocks the next. Doing them out of order does not just waste money, it destroys information that no later step can recover.
Coupling hygiene. Collapse the duplicates, add @@unique([paperId, label]), emit condition sets at sync time, delete the backfill, then re-measure. (Setting runId on the backfill is the rejected fix.) Until this lands, every extracted value is at risk of being orphaned from the experiment it belongs to. Part II · 07 Coupling.
Acquisition blockers. The five fixes, about 2.5 hours, that restart a pipeline that, at the 2026-09 audit, had been stalled since 2026-05-09. Nothing downstream can improve while only 23% of recent literature is PDF-backed. Part II · 02 Fix first.
Extraction, recency first. Run the 1,405 papers from 2025–26 before the legacy backlog. They are the papers a reviewer will ask about, and they are the ones whose PDFs you just recovered. Part II · 03 The run and Part II · 05 Extraction schema.
Vectorize. Backfill the 42% of abstracts that have no embedding, then add the chunk table so section vectors stop living only on disk. Part II · 00, section 0f.
Gates, then automation. Make coupling-completeness.ts, the disk-to-database audit, and pnpm verify:science pass on a real run before wiring the GitHub Actions workflow. Automating an unverified pipeline just produces bad data faster. Part II · 06 Beyond.
Part IV of VII · Operators & public claims · 5 sections · ~25 min
Operators, economics & public claims · read from the tree 2026-09-09
The second front door: what the corpus is worth, and what we have promised in public.
Parts I to III end at a modelable row and a prediction. This part follows that prediction two steps further — into the techno-economic and life-cycle numbers an operator buys on, and onto /proof, the public dashboard where the platform’s accuracy claims and its nine honest gaps are published side by side. It also carries the two runbooks those claims rest on: the literature backtest that gates the Butler–Volmer closure, and the multi-class validation work that is still owed. Every number here was read from the working tree on 2026-09-09; re-measure before quoting.
01Operator economics · what a curated paper is worth in dollars
Parts I to III follow one user: the researcher. The platform has a second front door. The homepage sells an operator track — “if you operate a waste stream” — whose deliverable is not a parameter but a number with a currency sign on it: CapEx, OpEx, LCOE, cost per m³ treated, payback, NPV, and a global-warming-potential offset. This section is the pipeline that turns the corpus into those numbers, and the places where that pipeline is honestly still a stub. Read from the tree on 2026-09-09.
2
front doors, one corpus
researcher · operator
6
influent presets · 6 system archetypes
demo/resource-recovery/constants.ts
7
TEA archetypes in the Python registry
services/biosteam-tea
stub
the live simulator route, until Modal lands
/api/lab/wastewater/simulator
The two front doors
Both tracks are declared in one file, apps/web/src/app/[lang]/home/components/AudienceTracks.tsx. The researcher track promises the corpus, the canonical parameter DAG and per-class predictors with conformal bounds. The operator track promises something the rest of this page never explains: “six industrial archetypes + custom influent characterisation”, “honest TEA + LCA per archetype — CapEx, OpEx, LCOE, LCO-water scaled with flow; GWP + fossil energy from peer-reviewed baselines”, and five-physics-family routing. If you are changing anything in the extraction or modeling stack, that second promise is downstream of you.
The chain, end to end
InfluentSix presets — brewery, municipal, dairy, landfill, blackwater, pharma — plus custom COD / N / P / flow / temperature / pH. apps/web/src/app/[lang]/demo/resource-recovery/constants.ts.
RoutingInfluent characteristics pick a system archetype: mfc-ad, mec-ad, mfc-struvite, side-nh3, side-ec, cas (SYSTEM_ARCHETYPES + _lib/recommend.ts, _lib/route-family.ts).
PerformanceThe prediction layer of Part I · 13 supplies power / current density, COD removal and coulombic efficiency — the same {value, unit, ci_low, ci_high, confidence, source} contract, with the interval caveats of Part I · 14 attached.
Process modelservices/biosteam-tea/src/mes_ww/ — a Python package over BioSTEAM / QSDsan. Seven archetypes in registry.py: ad, cas, mfc-ad, mec-ad, side-ec, side-struvite, side-nh3. Each exposes a build (live BioSTEAM system, raises if BioSTEAM is not installed) and a quick straight-line function.
Artifactspython -m mes_ww.run_all --out apps/web/public/data/computed/wastewater/ writes seven *-baseline.json files. The quick path is the production path — the MVP simulator serves the straight-line computation, not a live BioSTEAM simulation.
Surfacesapps/web reads all seven baselines at build time for /demo/resource-recovery (MiniTEA, IOAnalysis, SensitivityLadder, ArchetypeDossier); apps/lab renders the Process TEA tab of the ModelingPanel, which POSTs /api/lab/wastewater/simulator.
The output contract
Every archetype returns one ArchetypeResult (services/biosteam-tea/src/mes_ww/types.py, hand-mirrored in TypeScript at apps/lab/src/app/lab/components/modeling/process-tea/types.ts). Two of its blocks are the operator-facing ones.
discounted_payback_yr and lcoe_usd_per_kwh are nullable by design: a plant with negative net cash has no payback, and a non-generating archetype has no LCOE. Render the null, never a zero.
Both are signed: a negative GWP is a credit for displaced grid electricity (USA average 0.371 kg CO₂e/kWh in the current baselines). The credit basis lives in notes[] and must travel with the number.
The mass-balance rows behind the Sankey on the demo. This is where a COD-removal prediction becomes an effluent concentration.
The direct-air-capture ladder is a separate stack
Do not confuse the wastewater TEA with libs/shared/dac (@messai/dac), which costs an electrochemical DAC plant through its own ordered ladder: cell → stack → module → plant → capex → opex → levelized cost of capture, composed once in src/tea/pipeline.ts so no call site rediscovers the order. Every input beyond the design document is required and explicit; the three literature reference sets (LITERATURE_BPMED_INPUTS, LITERATURE_PLANT_GEOMETRY, REFERENCE_COST_BASIS) exist so the presets run, and passing one is a recorded choice rather than a default. Missing inputs return insufficientInputs instead of a number — the same refusal contract the predictors use.
What the economics layer does not yet do
The performance inputs are literature midpoints, not corpus predictions. The mfc-ad baseline says so in its own tea.notes: “Performance inputs are stub literature midpoints — wire to a sweep export for real numbers.” Closing that wire is the single highest-value piece of work in this section: it is what makes an operator number a corpus number.
The live route is a deterministic stub./api/lab/wastewater/simulator calls runSimulatorStub and returns a manifest with a null trust verdict, by design, until the Modal compute migration (SP-1) replaces the function body. The replay endpoint depends on it staying bit-identical, so do not “improve” the stub in place.
Flow scaling in the demo is linear.MiniTEA scales a baseline from its reference influent flow to the user’s. Real CapEx scales with an exponent well below one; the linearity is a known simplification, not a modelling claim.
The baselines are not automatically flattering. At defaults mfc-ad returns NPV −$92.0 M and LCOE $5.15/kWh over a 15-year life at a 10% discount rate. That is the honest answer for the assumed electrode CapEx ($1,200/m², carbon cloth, Logan 2008 inflated), and it should stay visible. If a change makes an archetype suddenly profitable, find the assumption that moved before shipping it.
No LCA beyond two indicators. GWP and fossil energy only. There is no water, eutrophication or toxicity indicator, and no uncertainty on either number.
02The public trust surface — /proof and the nine honest gaps
The gaps ranked P0 to P2 in Part I · 17 are the internal list. Nine of them are also published, with the same visual weight as the accuracy numbers, on /proof — a live dashboard built for investors, reviewers and partners that reads Prisma counts and on-disk computed artifacts at request time. Every entry there is a public commitment. Fixing one is not only an engineering task; it retires a stated liability, and the statement has to be retired with it.
Rule
A gap fix is not done until HONEST_GAPS in apps/web/src/app/[lang]/proof/constants.ts is updated in the same pull request. A stale gap card is worse than no gap card: it says we do not know our own state.
Never quote /proof’s headline accuracy numbers as fresh evidence. 97.98% out-of-sample coverage and the calibration ECE come from artifacts that Part I · 14 audits and finds not exchangeable — the stored fit_validation_role split is separable at AUC 0.77–0.92 against a permutation null of about 0.50. When you fix the split, fix the dashboard in the same change. Part I · 14 is canonical where the two disagree.
The nine published gaps, and where the work lives
Gap
Published
What it is
Where you fix it
cov-power-density
1,285%
Power density spans about four orders of magnitude; point estimates mean nothing unconditioned.
Not a bug — a standing rule. Report per-stratum intervals; see Part I · 05 and SCIENTIFIC_INTEGRITY.md.
canonical-coverage
19% raw
19% of raw parameter names map straight to a canonical slug; about 58 high-frequency aliases are unmapped.
Withdrawn. The “~75%” that stood here carried no cohort, denominator or date, so it was not a number. Per-extractor row and paper counts are measured and dated on the Atlas; a success rate is not.
843 half-cell (vs-SHE) polarization points and 19 of 30 BVM-posterior-ready cells, but only about three genuine potential-sweep curves, so the transfer coefficient α stays under-identified. We make no mechanistic Butler–Volmer prediction claims.
Data-gated, not code-gated: it needs three-electrode / cyclic-voltammetry papers, which means targeted acquisition (Part II · 10) or a lab partnership. Meanwhile the validated within-design direction skill is what we surface.
ml-predict-uq-heuristic
±25% band
Per-class routing is live, but the non-MFC predictors emit a flat ±25% heuristic band (uncertaintyBasis="heuristic_fixed_fraction"), not propagated or calibrated uncertainty.
Of five attempted PySR fits, two succeeded; three were skipped for insufficient data.
Downstream of extraction volume — re-run once per-pair n clears the sufficiency threshold. Part II · 03 The run.
Metrics as published in apps/web/src/app/[lang]/proof/constants.ts, read 2026-09-09. Several were measured months earlier; the dashboard shows what it last measured, which is exactly why re-measuring before quoting is a rule and not a preference.
What /proof reads
Live Prisma counts for the data-moat panel; and on disk, holdout-coverage-2026-05-21.json, calibration.json, symbolic-regression-laws.json, the learned DAG edges and the parameter prior-trust artifact, all through readComputedArtifact. It runs no training and no validation of its own. So a refit that lands a new artifact changes the public dashboard on the next deploy, silently, with no review step in between — check /proof after any refit named in Part II · 03.
03The literature retrospective backtest — the runbook
Separate from the held-out benchmark of Part I · 14, which scores models on paper-disjoint corpus rows, the backtest re-predicts a small set of hand-encoded canonical papers at each paper’s own experimental configuration and compares against the number that paper reported. It is the regression gate on the Butler–Volmer closure, and it is the claim /proof publishes as “literature retrospective”. Anyone touching resolveBVParams, the sweep closure or the calibration constants runs into it.
The bands
From apps/lab/src/lib/sweep/backtest-utils.ts, following Logan & Regan 2006 lab-to-lab reproducibility: green |Δ| ≤ 25% · amber 25% < |Δ| ≤ 50% · red |Δ| > 50%, a genuine model gap to investigate. The platform’s retrospective-validation score is that pass-rate; there is no other summary statistic behind it.
What is actually encoded, measured 2026-10-07
20
preset files in presets/
one paper each
20
registered in LOGAN_PRESETS
the set the gate iterates — all of them
14
holdouts in HOLDOUT_PRESETS
the Track 9 falsification set
3
out-of-fit MBES_HOLDOUTS
plus 3 unregistered MBES records in _holdout/
The last five presets were registered on 2026-10-07: izadi-2020-mes, rodziewicz-2022-mnrc-high-p, spiess-2023-mmrc, wang-2024-mmrc and yuan-2017-mnrc-low-cod. A merge had dropped them from the registry in May, and they had been written under the wrong first authors (philips-, rusanowska-, beck-, zhao- and almatouq-); each id now follows its DOI’s Crossref record. They add 10 rows to the backtest: 8 green, 1 amber, 1 red. They are calibration rows, not independent validation: the MES, MMRC and MNRC closures were fitted to these papers, so agreement is in-sample. backtest-presets.test.ts now fails when a preset file is not registered.
The /proof panel quotes 20 encoded papers, 7 of 10 MFC rows green, a 6.5% median |Δ| across those rows and 44 of 44 anchor cases passing, from a run on 2026-10-07; across all 50 rows the backtest gives 39 green, 8 amber and 3 red. Those are a snapshot hard-coded in proof/constants.ts (LOGAN_BACKTEST), not a value read from a run — the backtest produces its numbers in Jest output, not in a persisted artifact. apps/lab/src/lib/sweep/__tests__/holdout-anchor-emit-json.ts writes both registries’ rows as JSON when run with npx tsx; a scripts/research/snapshot-backtest.ts that feeds /proof from it is a known, unbuilt follow-up. Until it exists, re-derive the numbers from a run before quoting them.
The two Jest gates
apps/lab/src/lib/sweep/__tests__/backtest-presets.test.ts asserts the aggregate: every preset file in presets/ is registered, every preset has at least one reported result, ids are unique, every prediction is finite, all Liu & Logan 2004 anchor rows land green, the MFC green pass-rate stays at or above 50%, MEC rows may be red (Cusick 2011 is a measure-the-gap preset, intentionally out of an MFC-only closure), and the MBES holdouts keep at least 60% of rows green-or-amber.
apps/lab/src/lib/sweep/__tests__/butler-volmer-calibration.test.ts is the tighter gate: 44 numbered cases (50 tests in all), each a hard-coded numeric range, roughly ±30% around a literature anchor, that a single coefficient tweak will break together. The first ten, the MFC, MEC and MES founding anchors:
Case
Configuration
Asserted range
1
Liu & Logan 2004 — wastewater, no PEM, air cathode, 7 cm²
100–250 mW/m²
2
Liu & Logan 2004 — wastewater, with PEM, air, 7 cm²
15–50 mW/m²
3
Defined substrate (acetate), no PEM, air, 7 cm² — Liu & Logan 2004 ran no acetate
Wastewater, air, no PEM, large electrode (200 cm²) — scale-up drop
50–150 mW/m²
8
Call & Logan 2008 — acetate MEC + Pt, Vapp = 0.6 V
4–12 A/m²
9
Cusick 2011 — pilot MEC, stainless, Vapp = 0.9 V
0.1–0.6 A/m²
10
Nevin 2010 — S. ovata biocathode MES, |E| = 0.4 V
0.02–0.07 A/m² · CE 70–100%
The same file also pins two coulombic-efficiency anchors (wastewater + air 8–18%, acetate + ferricyanide 50–90% at maximum power) and asserts that activation overpotential stays temperature-dependent while the 30 °C reference is unchanged.
Adding a paper to the backtest
Create apps/lab/src/lib/sweep/presets/<first-author>-<year>-<topic>.ts exporting one LoganPaperPreset (the interface lives in liu-logan-2004.ts).
Fill paper with title, authors, journal, year, DOI, and the figureRef / tableRef the numbers came from. A preset without a figure reference cannot be checked by a reviewer and should not be merged.
Encode config as the sweep the paper actually ran — the axis it varied (usually external_resistance), its range, scale and levels — so a reader lands on the chart shape the paper shows.
Add one reportedResults entry per published number: seriesKey, reportedValue, reportedUnit, reportedConditions, pageRef. If the paper reports at a fixed operating point rather than at maximum power, set operatingPoint: { sweepValue } and make config.sweepParam the matching axis — otherwise the harness compares its MPP row against the paper’s off-peak number and the delta is meaningless.
Write caveats honestly: what the paper does not report, what you had to assume. Encode the paper’s own headline number, never a better one from a later optimisation.
Import it in presets/index.ts and add it to LOGAN_PRESETS; an out-of-fit holdout goes in _holdout/ and HOLDOUT_PRESETS instead, from a paper no calibration preset cites. A preset file left out of the registry fails backtest-presets.test.ts.
Run pnpm nx test messai-lab (or the two test files directly) and read the bands.
Never
Never widen a Butler–Volmer range so a new paper passes. The ranges are the calibration anchors; moving one to accommodate a preset destroys the only signal the gate carries. A red band on a new class is the correct, publishable result.
Never treat the backtest as held-out validation. Every anchor paper informed the closure it is scored against. The paper-disjoint audit is Part I · 14, and it reports a very different picture.
04Multi-class validation — two classes measured, five surrogate
The platform covers microbial electrochemical systems in general: 17 primary types, 12 combinations, five physics families. Its held-out validation covers two devices. That asymmetry is the single most load-bearing caveat in any performance claim we publish, and it is published — /proof carries it as multiclass-validation, “2 of 7”.
Class
Predictor
Interval
Held-out validation
MFC
Data-tuned empirical path
Conformal / priors band
measured 4 strata in the 2026-05-21 cohort (power density, current density, coulombic efficiency, COD removal) — with the exchangeability caveat of Part I · 14.
MEC
predictors/mec.ts
Conformal / priors band
measured 3 strata in the same cohort.
MDC
predictors/mdc.ts
±25% heuristic
none analytical predictor landed 2026-05-15; never scored against a held-out paper cohort.
MES
predictors/mes.ts
±25% heuristic
none and still falls through to MFC-surrogate physics enrichment.
MNRC
predictors/mnrc.ts
±25% heuristic
none MFC-surrogate enrichment.
MMRC
predictors/mmrc.ts
±25% heuristic
none MFC-surrogate enrichment.
MBES
predictors/mbes.ts
±25% heuristic
none MFC-surrogate enrichment; the only class with an out-of-fit backtest holdout (Part IV · 03).
Predictors in libs/shared/electrochemistry/src/predictors/; routing in libs/shared/ml/src/run-full-prediction.ts → predictions/per-class-base.ts, where the surrogate fall-through is a comment at line 447. The measured cohort is apps/web/public/data/computed/research/holdout-coverage-2026-05-21.json: 940 observations, 7 strata, all MFC or MEC.
Assembling a holdout cohort for one more class
Count first. Query modelable rows for the class by target slug and count papers, not rows — a cohort of 400 rows from 9 papers validates nothing. Between-paper spread is roughly twice within-paper (Part I · 14), so papers are the unit that matters.
Split by paper, never by row. Group k-fold or hash on paper id. The row-level split is exactly what produced the numbers Part I · 14 had to retract.
Run the adversarial audit. Train a classifier on design covariates to tell train from test. Near 0.50 against the permutation null is a usable split; 0.77–0.92 is the failure mode already on record.
Score against the class median baseline. The bar is the class × domain median. A predictor that does not beat it by a meaningful margin has not earned an interval, whatever its physics.
Replace the heuristic band only when it is earned. Until a class has a calibrated interval, keep uncertaintyBasis="heuristic_fixed_fraction" in the response so every consumer can see the difference. The label is the honest part.
Retire the surrogate. A class validated on its own cohort should stop falling through to MFC physics enrichment — and /proof’s multiclass-validation card should move from “2 of 7” in the same pull request.
Copy rule
Do not write, ship, or approve interface copy that says predictions are validated for “microbial electrochemical systems” without naming MFC and MEC. Coverage of the taxonomy is not coverage of the evidence.
05How hand curation in open-source/ reaches a prediction
Part III · 05 maps the nine packages, their versions, licences and release path. This is the shorter question a new engineer actually asks: if I curate a row by hand in one of them, what changes downstream? Three distinct paths, and only one of them is a database.
Read at request time
mess-materials → predictions
libs/shared/ml/src/predictions/material-features.ts imports open-source/mess-materials/data/mp-materials-rich.json directly and hydrates a material slug into DFT features — band gap, formation energy, energy above hull, work function, elastic moduli, Pourbaix stability per electrode role. Every /api/ml/predict response carries the result as feature_signals.materials. Unknown slugs return found: false with null fields rather than failing. This is the Materials Project bridge: computed thermodynamics on one side, lab electrochemistry on the other, joined by a curated slug.
Seeded into Postgres
mess-materials · mess-microbes → DB
scripts/sync-materials-to-db.ts and scripts/seed-materials-bootstrap.ts load the Material table; export-microbes-to-json.ts and audit-microbe-field-coverage.ts maintain the 28-microbe catalogue. A hand-curated row is invisible to the product until the seed runs — and the seed is a batch script someone runs, not a deploy step.
Round trip
mess-parameters ↔ DB
The ontology flows out at build time (per-slug fixtures under /data/parameters/<slug>.json), and extracted values flow back in as data/paper-parameter-values.csv. ParameterDefinition is edited in the database and synced back to the package — it is the one bidirectional edge on the map, and the one place where “which copy is authoritative” has to be answered per field rather than per file.
The loop closes only if you run it
Edit the package inside this monorepo (Part III · 05); the Messai-io/MESS-* repositories are read-only mirrors.
Then run the consumer: the seed script for materials and microbes, the fixture generator for parameters. Neither runs on deploy.
A curated field that no query filters on, no ML feature reads and no UI renders is inventory, not signal. Before curating in bulk, name the consumer.
Part V of VII · P&ID symbol library · 2 sections · ~10 min
P&ID symbol library · @messai/pid-schematic · drawn at build time
Every mark a sheet can make, and what each one commits the designer to.
A P&ID is only an engineering document if its reader and its author agree on what the marks mean. This part is that agreement, written down: the whole vocabulary of @messai/pid-schematic — equipment bodies, pump and vessel types, valve bodies and actuators, line and signal conventions, instrument bubble frames — each drawn by the same renderer that draws the sheets, and each explained by what you learn from seeing it rather than by what it is called.
ISA-5.1ISO 10628typed glossarybuild fails on an undocumented symbol
01Symbol library · The plate, drawn by the renderer it documents
Everything below is a real drawing. Each swatch is a one-symbol PidSpec handed to <PidDiagram> — the same component that renders the 19 model sheets and the two worked examples in /lab/schematic — and rendered to static SVG in this page’s frontmatter. No client bundle ships to this page, and no symbol here can drift from the drawings it explains, because the legend does not draw anything: it asks the renderer to draw a sheet with one item on it.
Read the explanations as an engineer reads a drawing. A positive-displacement pump deadheads against a shut valve, so a sheet that shows one and no relief is telling you something is missing. A rotameter is read by eye and transmitted nowhere, so that flow will not appear in any dataset. A motor-actuated valve marked FC is a contradiction unless a spring return or a battery is specified. That is the level the glossary is written at.
P&ID symbol library
124 marks · 18 groups · 132×78 sheet units each · drawn by the same renderer as the sheets
Electrochemical cell
The marks that make a sheet bioelectrochemical rather than generic process: chambers, the separator between them, the electrodes inside and the reference they are held against.
Cell chamberchamber
One half-cell of an electrochemical reactor. Drawing two chambers with a separator between them commits the design to ionic-but-not-convective coupling: anolyte and catholyte have distinct compositions, distinct pH, and separate level and overflow problems.
R-1xxISO 10628 vessel body; MESSAI convention for a bioelectrochemical half-cell
Membrane / separatormembrane
The ion-selective barrier between half-cells. Once drawn, the sheet owes a differential-pressure measurement across it and a fouling story, because a separator is the component that silently changes resistance over a run.
X-1xxMESSAI convention (hatched bar); ISO 10628 filter/membrane family
Electrodeelectrode
An anode or cathode plate inside a chamber. It is an internal, not a tagged item: it carries no loop of its own, so its material and projected area belong in the chamber datasheet where a reviewer will look for them.
MESSAI convention; untagged internal per ISA-5.1 practice
Reference electrodereferenceElectrode
The third electrode that turns a two-terminal measurement into a controlled potential. A sheet whose state text says "held at −0.2 V vs Ag/AgCl" and shows no reference electrode is claiming control it has not drawn.
IUPAC three-electrode convention; MESSAI electrical symbol set
Vessels and hold-up
Anything with an inventory. The shell says how much pressure it can hold; the roof says whether it breathes.
Vessel / tankvessel
Bulk hold-up. Its presence says the process has residence time and a level that must be controlled or overflowed; the roof style (see vessel shells) then says whether the contents can breathe to atmosphere.
V-1xxISO 10628-2 tank symbols
Gas–liquid separatorgasSeparator
A drum where evolved gas disengages from the liquid it came up with. It is where the gas line gets its clean take-off, so gas measurement placed upstream of one is measuring a two-phase stream and is not trustworthy.
D-4xxISO 10628-2 knock-out drum
Rotating equipment
Machines with a shaft. Each one puts an item on a utility list and adds a failure mode the trip case has to cover.
Pumppump
Liquid motive force, and the point where the sheet must state a body type. A centrifugal pump can run against a shut discharge for a while; a positive-displacement one cannot, so its presence obliges a relief path.
P-1xxISO 10628-2 §pumps; body detail via `pumpType`
Blower / fanblower
Low-pressure gas movement — aeration, headspace sweep, cathode air. Reading it means the gas side is near atmospheric, so an inadvertent liquid carry-over floods the machine rather than being contained.
K-1xxISO 10628-2 rotary machine
Mixer / agitatormixer
Forced mixing in a vessel, which asserts the contents are treated as well-mixed. That assumption is what lets a model use a single bulk concentration; without the mixer the sheet is claiming a gradient it has not drawn.
M-1xxISO 10628-2 agitator on a vessel
Compressorcompressor
Gas machinery that raises pressure rather than just moving volume, so unlike a blower it makes the downstream a pressurised system with its own relief and its own compression heat.
K-4xxISO 10628-2 compressor
Motor drivermotor
The electric driver of a machine, drawn on the shaft. It puts the machine on the electrical load list and makes the sheet answer what happens to it on a power failure, which is usually a different question from the valve fail position.
ISO 10628-2 driver, "M" in a circle
Turbine / expanderturbine
A driver or expander that takes work OUT of a pressurised stream. Its presence means the pressure drop shown across it is being recovered rather than throttled away.
ISO 10628-2 driver, "T" in a circle
Generatorgenerator
The electrical machine a turbine or engine drives — the point where the sheet exports power instead of consuming it. In a biogas train it is the CHP end that the flame arrestor upstream is protecting.
G-4xxISO 10628-2 / IEC 60617 machine, "G" in a circle
Fired and thermal equipment
Where energy enters or leaves as heat — and, for the fired items, where an ignition source enters the drawing.
Heat exchangerheatExchanger
Duty transferred between two streams. Its presence commits the sheet to a second utility stream that must appear somewhere; an exchanger with only one side drawn is a heat balance that does not close.
E-4xxISO 10628-2 heat-transfer equipment
Fired heaterfiredHeater
Combustion supplying process heat. It introduces an ignition source to the sheet, which changes the classification of everything routed near it and makes fuel isolation an interlock, not a valve.
E-4xxISO 10628-2 fired equipment
Boilerboiler
Steam generation: a fired box under a drum with a level that must never be lost. Drawing one commits the sheet to a low-level trip, because a boiler that runs dry fails destructively rather than gracefully.
E-4xxISO 10628-2 steam generator
Cooling towercoolingTower
Heat rejected to air by evaporation, which is also a water loss and a blowdown stream. A tower on a sheet means the water balance has a term that does not appear anywhere in the piping.
ISO 10628-2 cooling tower (induced draught)
Separation and treatment
Units that split one stream into two. Every one of them produces a second stream that has to go somewhere on the sheet.
Filterfilter
Particulate removal in the line. It is a component that blinds over, so drawing one raises the differential-pressure question: how does an operator know it is blocked before the pump upstream finds out?
F-1xxISO 10628-2 filtration equipment
Strainerstrainer
Coarse debris protection immediately upstream of a machine. It is drawn where the designer decided a pump or a control valve was worth protecting, so its position tells you which item is considered fragile.
Y-1xxISO 10628-2 in-line strainer (Y or basket)
Column / towercolumn
A counter-current contacting device — stripping, absorption, distillation. It says the separation is equilibrium-staged rather than a single pass, so the sheet owes both a top and a bottom product and the utility that drives them.
C-3xxISO 10628-2 column, packed or trayed internals
Centrifugecentrifuge
Mechanical dewatering by density difference. Its presence splits one stream into a cake and a centrate, and the centrate is the one that usually goes back to the front of the plant carrying the load nobody budgeted for.
ISO 10628-2 centrifugal separator
Cyclonecyclone
Inertial separation with no moving parts, paid for in pressure drop. Reading one tells you the designer accepted a permanent ΔP in exchange for a device that cannot seize.
ISO 10628-2 cyclone / hydrocyclone
Clarifierclarifier
Gravity settling with a scraper — the wastewater unit that decides what the downstream biology actually sees. Its underflow is a recycle, so a clarifier drawn without a return sludge line is an incomplete flowsheet.
ISO 10628-2 settling basin; wastewater practice
Screenscreen
Headworks removal of rag and grit, drawn first because everything after it assumes that protection exists. A train with electrodes and no screen is claiming a feed quality it has not secured.
ISO 10628-2 screening equipment
Packed bedpackedBed
A fixed bed of adsorbent, resin, desiccant or biofilm support. Beds saturate, so drawing one obliges the sheet to say how exhaustion is detected and what regeneration or replacement looks like.
C-3xxISO 10628-2 packed vessel
UV reactoruvReactor
Disinfection by dose, not by residence time alone. The dose depends on transmittance, so a UV unit on a sheet implies an upstream solids duty that must actually be met for the disinfection claim to hold.
ISO 10628-2 special equipment; wastewater disinfection practice
Solids handling
Where the process stops being hydraulic and starts being conveyed.
Conveyorconveyor
A solids transfer that is not a pipe. It marks where the process leaves hydraulic transport, which is where flow measurement stops being a flowmeter and starts being a weigh or a belt speed.
ISO 10628-2 conveying equipment
Silo / hoppersilo
Bulk solids hold-up with a conical outlet. Solids bridge and rathole, so a silo asserts a discharge aid or an operator with a mallet — level in it is an inventory estimate, not a measurement.
V-1xxISO 10628-2 bunker / silo
Safety and protection
The devices a HAZOP asks for by name. `lintPid` fails a combustible-gas sheet that is missing them.
Flame arrestorflameArrestor
A quenching element that stops a flame propagating back up a combustible-gas line. Its absence on an H₂ or biogas header is the first finding of a HAZOP, and `lintPid` fails a sheet that omits it.
FA-2xxISO 16852; enforced by the `gas-no-flame-arrestor` lint rule
Pressure safety valvereliefValve
The last defence against overpressure, and the one device on the sheet whose set pressure is not negotiable. A gas-evolving cell behind a fail-closed valve is a pressure vessel, so a relief with no set point is an unfinished drawing.
PSV-8xxISA-5.1 `PSV` tag (safety modifier); ASME VIII relief practice
Rupture discruptureDisc
A single-use bursting element, used where a relief valve would foul or where zero leakage matters. Choosing it says the operator accepts a shutdown to restore protection after any relief event.
PSE-8xxISA-5.1 `PSE` tag; ASME VIII non-reclosing device
Spectacle blind / spadeblind
Positive mechanical isolation — the only kind a work permit accepts, because a closed valve can be opened by mistake and a blind cannot. Its position on the sheet is where maintenance can safely break into the system.
ISO 10628-2 spectacle blind; permit-to-work practice
In-line fittings and primary elements
Small marks that sit ON a line. They are what a reviewer looks for to decide whether a drawing is a real P&ID or a block diagram with pictures.
Valvevalve
A place where the process can be stopped or throttled. Every valve on a sheet is an operating decision that somebody must be able to reach, and an actuated one must declare its fail position or the trip case is undefined.
XV / FV-1xxISA-5.1 §5.4; ISO 10628-2 valve bodies
Sample pointsample
Where a physical sample is drawn for offline analysis. It is the bridge between the drawing and the corpus: every offline COD, VFA or microbial-community number in a dataset should trace back to a sample point on a sheet.
S-3xxISA-5.1 process connection; MESSAI convention (S in a circle)
Rotameterrotameter
A local variable-area flow glass — read by eye, transmitted nowhere. Seeing one means that flow is NOT available to the control system or the data logger, which is exactly the gap that turns up when a dataset has a missing column.
FG-1xxISA-5.1 local gauge (`FG`, glass function letter)
Orifice plateorificePlate
The primary element a differential-pressure flow loop measures across. Seeing it means the flow number is inferred from ΔP and square-rooted, so it is least accurate at low flow — which is where a lab rig usually runs.
FE-1xxISA-5.1 primary element `FE`; ISO 5167 orifice
Venturi / flow nozzleventuri
The same inferred-flow principle as an orifice, chosen when permanent pressure loss matters or the fluid carries solids that would erode a plate.
FE-1xxISA-5.1 primary element `FE`; ISO 5167 venturi
Static mixerstaticMixer
In-line blending with no motor, using pressure drop instead of shaft power. It is drawn where a dosed chemical must be homogeneous before it reaches the next unit, so it fixes where the analyser downstream may legitimately sit.
ISO 10628-2 in-line mixer
Ejector / eductorejector
A motive stream entraining a second one — vacuum or dosing with no rotating part. It couples the two streams: the entrained flow is a function of the motive pressure, so it cannot be set independently.
ISO 10628-2 jet pump
Steam trapsteamTrap
Passes condensate and blocks steam. A trap on a sheet is an admission that a heated line makes liquid, and a failed-open trap is a continuous energy loss that no alarm on this drawing would catch.
ISO 10628-2 condensate trap
Sight glasssightGlass
A window on the line for an operator, and nothing else. Like a rotameter it makes a fact visible locally while leaving it absent from the data, which is worth knowing before treating a logbook entry as a measurement.
ISA-5.1 glass / gauge function (`G`)
Reducerreducer
A change of line size, and therefore of velocity. Drawn eccentric with the flat on top it also says the designer is deliberately avoiding a gas pocket, which is a pump-suction detail worth reading.
ISO 10628-2 fitting; concentric or eccentric per `eccentric`
Expansion jointexpansionJoint
A deliberate flexibility in an otherwise rigid run — thermal growth, vibration from a machine, or a skid boundary. It marks where the piping designer expected relative movement between two things.
ISO 10628-2 flexible element / bellows
Electrical and data
The external circuit and the path a measurement takes to become a row in the corpus.
External loadload
The resistance the cell works into. Its value sets the operating point of the whole drawing — the same reactor at 10 Ω and 1 kΩ is two different experiments — so a sheet with a load and no stated resistance has not specified its own duty.
L-2xxIEC 60617 resistor on an ISA-5.1 sheet
Power supply / potentiostatpowerSupply
An applied bias, which makes the cell driven rather than spontaneous. Seeing one means the energy balance has an electrical input term, and the sheet must state the bias and whether it is held against a reference.
PS-2xxIEC 60617 DC source; ISA-5.1 §5 electrical
Control cabinet / PLCcabinet
The enclosure the control functions actually live in. It gives the panel-mounted bubbles a physical home, and marks the boundary an electrical safety review cares about.
PLC / cabinetISA-5.1 §4 location; enclosure shown as a plain box
Current shuntshunt
A calibrated low resistance the ammeter reads across, because current is measured as a voltage drop. It is where the current number in every dataset physically comes from, and its tolerance is the floor on current accuracy.
IEC 60617 shunt; measured via an `IT` loop
Switch / contactorswitch
The electrical twin of a valve: it is what makes open-circuit and closed-circuit different states of the same drawing. A polarisation sheet without one cannot show how OCV was actually obtained.
SW-2xxIEC 60617 switch; steered by the state `valvesOpen` list
DC–DC converterconverter
A boost, buck or MPPT stage between a cell that produces tens of millivolts and a payload that needs volts. Its presence means the harvested-power numbers downstream are post-conversion and carry its efficiency, not the cell figure.
PC-2xxIEC 60617 converter block
Supercapacitor / batterystorage
Energy buffering, which decouples a continuous low power from a pulsed load. Drawing it commits the sheet to a duty cycle: what charges, what discharges, and what the payload is allowed to do between pulses.
BT-2xxIEC 60617 cell / capacitor
Blocking diodediode
One-way current, which stops a charged store back-feeding the cell and reversing its polarity. It also costs a forward drop that a millivolt-scale source cannot ignore, so it is a design trade, not a free part.
IEC 60617 semiconductor diode
Data logger / DAQdaq
Where the sheet stops being an instrument diagram and starts being a dataset. Every parameter that reaches the corpus passes through here, so a measurement with no path to the logger will never appear in the data.
DL-2xxISA-5.1 computer/logger function; hexagonal bubbles report here
Ground / earthground
The reference the rest of the circuit is measured against. On a multi-cell stack it also says which potentials are floating, which is what determines whether two loggers can share a common and still read the truth.
IEC 60617 earth symbol
Terminal blockterminalBlock
The physical break in the wiring where a circuit is landed, measured and disconnected. It is what makes a drawing buildable by somebody who was not in the room when it was designed.
IEC 60617 terminal / junction
Sheet boundary
Where streams enter and leave this drawing, and whose scope they become.
Off-sheet destinationsink
Where a stream leaves this drawing — drain, vent, flare, grid, next sheet. The label is the whole point: "TO DRAIN" and "SAFE VENT" are different commitments, and an unlabelled exit hides which one was meant.
ISA-5.1 off-page connector
Off-sheet originsource
Where a stream enters from outside the sheet. It is the battery limit: everything upstream of it is somebody else’s scope, so its conditions belong in the stream table rather than being assumed.
ISA-5.1 off-page connector
Pump bodies
Set with `pumpType`. The body decides how the pump fails, and therefore what protection the sheet owes it.
Centrifugalcentrifugal
Flow falls as discharge pressure rises, so it can sit against a closed valve without bursting the line — at the cost of heating its own contents. Its curve, not the motor, sets the operating point.
ISO 10628-2 centrifugal pump
Positive displacementpositiveDisplacement
Delivers a fixed volume per revolution regardless of what is downstream. It will happily raise pressure until something fails, which is why a PD pump and no relief valve is a defect a reviewer looks for first.
ISO 10628-2 displacement pump; relief required
Progressive cavityprogressiveCavity
A displacement pump that tolerates viscous, gritty, gas-laden sludge — the wastewater default. It must never run dry: the stator is elastomer and destroys itself in seconds without liquid.
ISO 10628-2 rotary displacement pump
Screw pumpscrew
Low-shear displacement pumping, chosen when the fluid is viscous or when shearing flocs or cells would change what arrives downstream.
ISO 10628-2 rotary displacement pump
Reciprocatingreciprocating
Piston or plunger delivery: high pressure, but pulsating. The pulsation is a real signal on any downstream pressure or flow measurement, so a damper is usually implied even when it is not drawn.
ISO 10628-2 reciprocating pump
Gear pumpgear
Tight-clearance displacement pumping for clean, lubricating fluids. Particulates are what kills it, which is why a strainer immediately upstream is the usual companion mark.
ISO 10628-2 rotary displacement pump
Peristaltic / hoseperistaltic
The bench default on a bioelectrochemical rig: the fluid touches only tubing, so the pump is sterile-able and cannot contaminate the anolyte. Flow is set by rpm and tube bore, and it drifts as the tube fatigues.
ISO 10628-2 displacement pump; MESSAI lab convention
Metering / dosingmetering
A displacement pump whose stroke IS the measurement — dosed volume is set, not read back. Anything relying on the dose being right needs an independent check, because the pump reports what it commanded, not what it delivered.
ISO 10628-2 metering pump
Vacuum pumpvacuum
Draws below atmospheric, which turns every downstream leak into an air INGRESS. On an anaerobic sheet that matters more than the vacuum itself: ingress poisons the culture and skews gas analysis.
ISO 10628-2 vacuum pump
Vessel shells and roofs
Set with `vesselType`. ISO 10628 draws the roof because the roof is what says whether the contents can breathe to atmosphere.
Domed headsdomed
A closed, pressure-capable shell. Drawing it says the vessel can hold a headspace above atmospheric, and therefore that it needs a relief path stated somewhere on the sheet.
ISO 10628-2 pressure vessel
Dome roofdomeRoof
A fixed dome atmospheric tank: it breathes through a vent as it fills and empties. That breathing is how oxygen gets into an anaerobic inventory, so the vent detail matters more than the roof shape.
ISO 10628-2 fixed-roof tank
Floating rooffloatingRoof
The roof rides on the liquid so there is no vapour space to breathe. It is a vapour-loss and emissions control choice, and it says the contents are volatile enough for that to have been worth the mechanism.
ISO 10628-2 floating-roof tank
Cone roofconeRoof
The plain atmospheric storage tank: fixed conical roof, vented, cheap. Reading it means gauge pressure is essentially zero and any pump taking suction from it depends entirely on static head.
ISO 10628-2 fixed-roof tank
Open topopenTop
An open basin or launder — no headspace at all, so no gas can be collected and no odour or aerosol contained. On an MES train it rules out any biogas claim for that unit.
ISO 10628-2 open basin
Horizontal drumhorizontal
A drum on saddles: large liquid surface, small depth. That geometry is chosen for disengagement and surge, so level in it changes slowly per unit volume — useful when the control loop is slow.
ISO 10628-2 horizontal vessel
Spheresphere
Pressure storage at scale, where uniform wall stress is worth the fabrication cost. Seeing a sphere means the contents are stored well above atmospheric — a hydrogen inventory, not a buffer tank.
ISO 10628-2 spherical vessel
Drivers
Set with `driver`, printed as a letter in a circle on the shaft. It answers what keeps the machine turning when something else stops.
Electric motormotor
The machine is on the electrical distribution, so it stops when power does. Every motor-driven item is therefore part of the power-failure case, which is usually the worst case a P&ID has to survive.
ISO 10628-2 driver, "M"
Turbine driveturbine
Driven by a process or steam stream rather than the grid, so it keeps running through an electrical failure. That independence is normally the reason it was specified.
ISO 10628-2 driver, "T"
Engine driveengine
A combustion prime mover — self-contained, fuelled, and an ignition source. On a biogas sheet it is often both the driver and the consumer of the gas the plant makes.
ISO 10628-2 driver, "E"
Manual drivemanual
A person turns it. That means the action is not available to any interlock, so nothing on the sheet may rely on it happening automatically or quickly.
ISO 10628-2 hand-operated
Valve bodies
Set with `valveType`. Isolation, throttling and non-return are three different jobs, and the body says which one this valve is fit for.
Gate valvegate
Isolation only — full bore when open, bad at throttling because a partly open gate erodes and chatters. A gate drawn on a control leader is a specification error.
ISO 10628-2 plain bowtie (generic / gate)
Globe valveglobe
A throttling body with a real, characterisable relationship between stem position and flow. It is what a flow or level controller should be modulating; the permanent pressure drop is the price.
ISO 10628-2 globe (filled centre)
Ball valveball
Quarter-turn, tight shut-off, full bore. Ideal for an on/off `XV` and poor for control, so a ball valve on a modulating loop tells you the loop will be coarse and mostly on the seat.
ISO 10628-2 ball (centre circle)
Butterfly valvebutterfly
A disc in the flow: cheap and compact at large sizes, but the disc stays in the stream when open, so it is not a full-bore isolation and it will not pass a pig or a probe.
ISO 10628-2 butterfly
Check valvecheck
Non-return, and the only valve on the sheet nobody operates. It defines a direction the process cannot reverse — which is exactly the assumption that a pump trip or a siphon can otherwise break.
ISO 10628-2 check (flow-direction flag)
Needle valveneedle
Fine manual trim on a small line — a sampling or gas-analyser take-off. Its presence says the flow there is set once and left alone, not controlled.
ISO 10628-2 needle body
Three-way valvethreeWay
One port diverts or blends between two others, so it makes a routing decision rather than a throttling one. The sheet must say which port is which, or the state diagram is ambiguous.
ISO 10628-2 three-port body
Diaphragm valvediaphragmValve
The wetted parts are an elastomer diaphragm and a smooth weir — no stem into the fluid, nothing to trap solids or culture. That is why it is the usual choice on a sterile or biofilm-carrying line.
ISO 10628-2 diaphragm (arc over the body)
Plug valveplug
Quarter-turn isolation with a tapered plug, tolerant of slurry because there is no cavity for solids to pack into. Chosen where a ball valve would seize.
ISO 10628-2 plug body
Angle valveangle
A 90° body that turns the line as it valves it. It removes an elbow and a joint, and it is the standard geometry at a tank nozzle or a relief inlet.
ISO 10628-2 angle body
Pinch valvepinch
An elastomer sleeve squeezed shut, so the only wetted part is a tube. It handles abrasive slurry and sludge that would destroy a seated valve, and it is replaced rather than repaired.
ISO 10628-2 pinch body
Knife gateknifeGate
A blade that shears through settled solids to close. It is the wastewater sludge isolation, and it is not a tight shut-off against gas — reading it on a biogas line should prompt a question.
ISO 10628-2 knife gate; wastewater practice
Pressure regulatorregulator
Self-contained control: it holds DOWNSTREAM pressure using the process itself, with no controller, no signal and no loop number. It works during a power failure, and it also cannot be trended.
ISA-5.1 self-actuated regulator (dome + spring)
Backpressure regulatorbackpressureRegulator
The mirror image: it holds UPSTREAM pressure by relieving excess. On a gas-evolving cell it is what keeps a stable headspace pressure without letting the vessel climb toward its relief set point.
ISA-5.1 self-actuated backpressure regulator
Valve actuators
Set with `actuator` when `actuated` is true. The actuator is what makes a declared fail position physically true.
Spring–diaphragmdiaphragm
Instrument air against a spring: it modulates smoothly and it has a defined position when the air is lost, which is what makes a stated fail position credible. The plant then needs an air supply that survives the trip.
ISA-5.1 §5.4 diaphragm actuator
Motor actuatormotor
Electric drive: strong and air-free, but on power loss it holds position rather than springing anywhere. A motor-actuated valve marked FC is a contradiction unless a battery or a spring return is specified.
ISA-5.1 §5.4 electric actuator, "M"
Solenoidsolenoid
A two-state coil — energised or not — so the valve is on/off and fails to its de-energised seat. It is the fast trip element, and it is why the interlock in the logic block can act in milliseconds.
ISA-5.1 §5.4 solenoid, "S"
Piston / cylinderpiston
High thrust from air or hydraulic pressure, for large or high-ΔP valves. Double-acting cylinders have no inherent fail position, so the sheet must say what the accumulator or spring provides.
ISA-5.1 §5.4 cylinder actuator
Spring returnspring
Stored mechanical energy that drives the valve to a safe seat with no power and no air. It is the reason a fail position is a physical fact rather than a hope about the control system.
ISA-5.1 §5.4 spring-opposed actuator
Weight operatedweight
Gravity does the work, so it cannot fail to act while the planet is present. The classic use is a separator dump valve that must open even with everything else dead.
ISA-5.1 §5.4 weight actuator
Pilot operatedpilot
The process pressure itself supplies the actuating force. It needs no utility at all, but it also means the valve responds to the process rather than to the operator, and it cannot be overridden remotely.
ISA-5.1 §5.4 pilot-operated
Hand wheelhand
A human closes it, at walking speed, if someone is there. Nothing automatic may depend on it, and on a hazard sheet it is never the protection layer.
ISA-5.1 §5.4 hand-operated
Lines and piping
Three lineweights and a dash pattern carry the whole hierarchy: what flows, what is measured, and what is only planned.
Process lineprocess
The heaviest stroke on the sheet: the main liquid path that carries mass. Weight is the hierarchy here — anything drawn thinner is carrying information or utility, not the process itself.
ISA-5.1 §5.1 main process line
Instrument signalsignal
A hairline dashed run from a measurement to whatever acts on it. It carries no mass, so it may cross process lines freely, and its absence means a reading that exists but reaches nothing.
ISA-5.1 §5.3 undefined/electrical signal
Electrical conductorelectric
The external circuit of the cell — power, not information. On a bioelectrochemical sheet this is a process path in every sense except that the thing flowing is charge.
ISA-5.1 §5.3 electrical; IEC 60617 conductor
Gas linegas
Headspace, vent, purge or product gas. The long dash is a warning as much as a convention: it flags the runs where combustibility, relief and flame arrestors have to be argued.
MESSAI convention on ISA-5.1 §5.1; long dash
Pneumatic signalpneumatic
Instrument air, drawn solid with double slashes. It says the final element depends on a compressed-air utility, which is a system that has to be shown to survive whatever the trip case is.
ISA-5.1 §5.3 pneumatic (double slash)
Hydraulic signalhydraulic
Fluid power to an actuator, marked with single strokes. It appears where thrust matters more than speed, and it brings a power pack that is itself a system on the sheet.
ISA-5.1 §5.3 hydraulic (single slash)
Capillarycapillary
A sealed, filled thermal system between a bulb and its instrument. It is not a signal that can be re-ranged or split: the tube, the fill and the instrument are one calibrated assembly.
ISA-5.1 §5.3 filled thermal element (cross marks)
Data linkdata
A software or fieldbus connection — the route by which a reading reaches the historian or the model layer. On a MESSAI sheet this is the boundary between an instrument and the corpus.
ISA-5.1 §5.3 data link (small circles)
Mechanical linkmechanical
A physical linkage between two items — a shaft, a lever, an interlocked key. Nothing electrical is involved, so it keeps working when everything else on the sheet is dead.
ISA-5.1 §5.3 mechanical link (circle marks)
Jacketed pipejacketed
A pipe inside a pipe, drawn as a double run. It says the contents are heated, cooled or contained by an annulus, so the jacket is a second service that needs its own supply and return.
ISO 10628-2 jacketed line
Traced pipetraced
Heat tracing along the line — steam or electric. It marks the runs that would otherwise freeze, wax or drop out of solution, and it is a utility load that has to appear somewhere.
ISO 10628-2 heat-traced line
Future scopefuture
Drawn light and dashed: designed for, not being built. It reserves a tie-in so a later phase does not have to break into a live system, and it must never be read as installed.
ISO 10628 drafting convention for future work
Existingexisting
Already installed and outside this scope of work. It tells a reader which parts of the drawing are a survey and which are a design, which is what decides who is responsible for the condition.
ISO 10628 drafting convention for existing plant
Instrument bubble frames
Set with `mount`. The frame says WHERE the function lives and therefore who can reach it during an upset.
Field mountedfield
A plain circle: the device is out on the process where the operator has to walk to it. Anything a control room needs from it must be transmitted, so a field bubble with no signal line is a local reading only.
ISA-5.1 Table 5, field location
Main panel frontpanel
A solid bar across the bubble: normally accessible to the operator at the main panel. This is where the interlock resets and the mode switches live — the things an operator is expected to reach during an upset.
ISA-5.1 Table 5, primary location, accessible
Main panel rearpanelRear
A dashed bar: the function exists at the main location but is behind the panel and not operator-accessible. It is real control that nobody can adjust in the moment, which is often the point.
ISA-5.1 Table 5, primary location, inaccessible
Local panel frontlocalPanel
A double solid bar: an auxiliary panel at the unit itself. It says commissioning and local operation happen at the skid, not the control room, which matters for who sees an alarm first.
ISA-5.1 Table 5, auxiliary location, accessible
Local panel rearlocalRear
A double dashed bar: behind the local panel — configured once and then invisible. Trip settings hidden here are exactly the ones a review has to go looking for.
ISA-5.1 Table 5, auxiliary location, inaccessible
Shared display / DCSdcs
A circle in a square: the function is software on a shared control system, so it is trended, alarmed and changeable by configuration. It is also only as available as that system is.
ISA-5.1 Table 5, shared display / shared control
PLC / logicplc
A diamond in a square: programmable logic. Interlocks drawn here execute deterministically and independently of the display layer, which is why a trip belongs in this frame rather than the DCS one.
ISA-5.1 Table 5, programmable logic control
Computer functioncomputer
A hexagon: a computed rather than measured quantity — coulombic efficiency, a fitted rate, a model prediction. Reading it should prompt the question of what it was computed FROM, and how good that was.
ISA-5.1 Table 5, computer function; the MESSAI model layer
Signal types
Set with `kind` on a signal. A reader tells these apart by the tick drawn across the run, not by the dash pattern.
Electric signalelectric
The default 4–20 mA or digital run between two tags. Its direction is the control story: measurement to controller to final element, and a controller with no output drawn is not controlling anything.
ISA-5.1 §5.3 electrical signal (dashed)
Pneumatic signalpneumatic
Air pressure carrying the command to a diaphragm actuator. It ties the loop to the instrument-air system, so the air header becomes part of the trip analysis for every valve it reaches.
ISA-5.1 §5.3 pneumatic (double slash)
Data linkdata
A software link between control functions or out to the historian and the model layer. It carries values that were already computed, so it propagates any error in them without adding measurement of its own.
ISA-5.1 §5.3 data link (circles)
Hydraulic signalhydraulic
Fluid power as the command path, used where the actuator needs force a diaphragm cannot supply. It is slower to plumb and faster to act than most alternatives at the same thrust.
ISA-5.1 §5.3 hydraulic (single slash)
Capillary connectioncapillary
The filled tube joining a temperature bulb or a remote diaphragm seal to its transmitter. It has thermal lag of its own, so ambient at the tube can show up in the reading.
ISA-5.1 §5.3 filled system (cross marks)
ISA-5.1 tag letters
A tag is <letters>-<loop>. These tables are the ones validateInstrumentTag enforces — the glossary presents them, it does not keep its own copy.
First letter — measured or initiating variable
position 1
What the loop is about. `E` is voltage, `I` current, `J` power — the three that make an MES sheet electrochemical rather than chemical.
Aanalysis (pH, DO, COD, CH₄, H₂, conductivity)
Bburner / combustion
Cconductivity
Ddensity
Evoltage (emf)
Fflow rate
Ggauging / dimension
Hhand (manual)
Icurrent (electrical)
Jpower
Ktime / schedule
Llevel
Mmoisture / humidity
Nuser-defined
Ouser-defined
Ppressure / vacuum
Qquantity / totaliser
Rradiation
Sspeed / frequency
Ttemperature
Umultivariable
Vvibration
Wweight / force
Xunclassified
Yevent / state
Zposition / dimension
Second letter — variable modifier
position 2, optional
Changes WHAT is measured, not what the device does: `PDT` is differential pressure, `FQI` a flow totaliser, `PSV` a pressure SAFETY valve.
Ddifferential
Fratio (fraction)
Qintegrate / totalise
Ssafety
Succeeding letters — readout, passive and output functions
positions 3+
What the device does with the variable. `E` senses, `T` transmits, `I` indicates, `C` controls, `V` is the final element that actually moves.
Aalarm
Buser's choice
Ccontroller
Esensor / primary element
Gglass / gauge (local)
Iindicator
Kcontrol station
Nuser's choice
Oorifice / restriction
Ptest point
Qtotaliser
Rrecorder
Sswitch
Ttransmitter
Vvalve / final control element
Wwell / probe
Xunclassified
Yrelay / compute / convert
Zdriver / actuator
Trailing letters — function modifiers
after A, S or C only
Where the function acts: `LAHH` is level alarm high-high, `TAL` temperature alarm low. Valid only after an alarm, a switch or a controller.
Hhigh
Llow
Mmiddle / intermediate
Equipment tag prefixes
before the dash
Equipment is `<prefix>-<number>`. Electrodes, shunts, grounds and terminals stay untagged — they are internals, not purchasable line items.
Rreactor / cell / stack
Vvessel / tank / reservoir
Ppump
Kblower / compressor
Eheat exchanger
Mmixer / agitator
Xmembrane / separator
Ggenerator / power output
PSpower supply / potentiostat
Lelectrical load / resistor bank
Fflare / filter / gas trap
FAflame arrestor
Ystrainer
Ccondenser / column
Ssampling point
Ddrum / knockout / gas separator
SWswitch / contactor / circuit isolator
PCpower converter (DC-DC, boost / buck, MPPT)
BTenergy storage (supercapacitor / battery)
DLdata logger / telemetry payload
Rendered from libs/shared/pid-schematic/src/glossary.ts via PidLegend.tsx, classic (printed-paper) theme. The blueprint plate version, with a theme switch, is at /lab/schematic → Symbol library.
02How it stays honest · The type system is the documentation policy
The mechanism, in one line
Every table in the glossary is a Record<Union, GlossaryEntry> over a union declared in spec.ts or blueprint.ts — never a Partial, never an array. Add a member to EquipmentKind and the build fails until somebody says what it means. A symbol set with a stale legend is the normal outcome; this makes it the impossible one.
Exhaustive by type
Nine unions — EquipmentKind, PumpType, VesselType, DriverKind, ValveType, ActuatorKind, LineKind, InstrumentMount, SignalKind — each with a total Record. glossary.test.ts re-asserts the same property with an Exclude<…> check, so loosening a table to Partial fails the suite as well as the typecheck.
Explanations, not restatements
The test rejects an entry whose text is empty, under eighty characters, under fifteen words, or begins with its own name, and requires at least ten content words the name does not already contain. “A pump moves fluid” does not pass.
Tag tables presented, not copied
The ISA-5.1 letter tables shown on the plate are the objects tags.ts exports — the same ones validateInstrumentTag enforces. The test asserts object identity, so the page and the linter cannot disagree about what PDT or LSHH means.
Swatches drawn, not illustrated
glossarySwatchSpec() builds the one-symbol sheet for each item, and the legend renders it through <PidDiagram>. A symbol that has no drawing yet appears as the renderer’s fallback rather than as a hand-drawn picture that quietly lies about what ships.
Source: libs/shared/pid-schematic/src/glossary.ts (the tables), PidLegend.tsx (the plate), __tests__/glossary.test.ts (the guarantees), .claude/skills/mes-pid-schematic/reference/isa-5.1-mes.md (the same material for an agent).
Part VI of VII · Database overhaul, Oct 2026 · 8 sections · ~12 min
MESSAI paper-data pipeline · 24 to 26 October 2026
What changed in the paper database, and how far to trust it now
Three days of audit, fixes and a production promotion: what was wrong, what the numbers did, what is still weak.
47,697
Modelable rows
+52%
was 31,475 · staging
11,694
Modelable + verified
+83%
was 6,403 · staging
2,546
Papers extracted
$20 total
14,947 rows landed
0 new
Science gate
134 baselined
down from 156
Staging measured 2026-10-24 and 2026-10-26; production before and after promotion on 2026-10-26. Counts are live (non-archived) extracted rows.
01The pipeline in one picture
Acquiredownload_from_db.py
Registersync-papers-to-db.ts
TextPyMuPDF to full.md
Extractsimple_value_extractor.ts
Landchangedsync-values-v2-to-db.ts
Harmonizechangedrefresh-all.sh
Fit priorschangedhierarchical_priors_v2.py
Serve/api/ml/predict
Thick teal rule and “changed”: stages rebuilt in PR 1240. The extractor also now stops on a billing error.
Paper-data pipeline from acquisition to served predictions, state on 2026-10-26, same code on staging and production.
02What was wrong
A scientist saw
Root cause
Fix
Review-paper numbers shaping priors
Four queries re-admitted rows by SI unit; genre never checked
One shared pool predicate; 102 reviews (3,737 rows) out PR 1240
Confidence nobody measured
Sync wrote 0.5; one arm stamped 0.9
Confidence nullable; arm stored PR 1240
Values missing from the model pool
Sync never set catalog link or SI value
Rows land fully harmonized PR 1240
One quantity, two names
Two slug mappers disagreed
One mapper; 2,728 camelCase slugs fused PR 1240
Refit on the wrong database
Defaults pointed at a retired local DB
Target required; prod also needs its ref PR 1240
Paid batch ran with no credits
Billing error counted per paper (568 per shard), exit 0
Extractor exits 2 on a billing error PR 1240
Different “modelable” counts per script
Five definitions
Single predicate; ladder measures on it PR 1242
Seven root causes found by the 2026-10-24 audit of the staging pipeline; the last was fixed in PR 1242, the rest in PR 1240.
03What the numbers did
Funnel, before and after
beforeafter
Live extracted rows per funnel step, staging 2026-10-24 vs 2026-10-26 (left) and production before vs after promotion on 2026-10-26 (right), n = rows, one shared scale.
Coverage ladder
no named rows yetnamed, none modelablemodelable
Highest rung reached by each live BES paper, staging, 2026-10-26, n = 15,361; papers with a modelable row rose from 1,415 to 1,809.
Extraction, checks and validation
Extraction push
Item
n
PDF, never extracted (10-24)
2,889
Via AI Gateway, ~$20
291
Via claude-cli, $0, ~15 s each
2,255
Papers extracted
2,546
Rows landed
14,947
Prior validation
Item
Value
Held-out papers
198
With usable data
81
Observations
3,982
95% coverage, v1
95.8%
95% coverage, v2
93.5%
Weakest coverage
Slug
Cover
n
total_dissolved_solids
56%
18
tafel_slope
58%
24
ammonium_ion_concentration
73%
11
Science gate
Item
n
Baseline, before
156
Baseline, after
134
Left / entered
79 / 57
Entered: interval calibration
53
Entered: logit-link support
3
Entered: gate honesty
1
Top holds, rows
Reason
n
unhandled_parameter
6,926
out_of_range:ph
2,863
unit_not_convertible:concentration_mg_l
2,062
extraction_artifact_not_a_parameter
1,482
Extraction on staging (2026-10-24 to 26, n = 2,546 papers); validation on the production held-out set (2026-10-26, n = 3,982 observations); holds on staging rows.
One pool for every consumer: modelablePoolExclusionsSql and its Python twin. Staging pool: 45,095 rows across 163 slugs; four plausibility guards return 0 rows.
All six steps run inside the insert transaction (PR 1240); confidence stays empty unless the paper reports one; pool measured on staging, 2026-10-26.
05Promotion to production, and the incident
Backup of production, 686 MB.
Three migrations, including nullable confidence and the stored extractor arm.
Search-vector backfill hit the 2-minute cap at batches of 500 and 100; resumed at 50; 0 of 23,598 papers unindexed.
Additive copy from staging: condition sets +4,076, extracted rows +19,053.
refresh-all on production: first run stopped at the cap, re-run finished; roles mirrored (106 rows), priors validated and synced.
Probe query on production far slower than staging.
prod49.7 s
staging0.59 s
Disk IO budget exhausted; the paper list times out at 60 s.
prod101 s
Compute tier raised.
All four zones Ready, every live route 200; PR 1247 cut a heavy sampler query from 9,972 ms to 46 ms.
prod0.58 s
Production promotion and incident, 2026-10-26; times UTC unless marked CET; probe = counting 3 million generated rows; the paper list answered in 0.7 s after the fix.
Lesson
Check compute tier and IO budget before a bulk production job, run heavy stages off-peak and one at a time, and stop adding load if a probe is over 10x slower than staging.
06What is still weak
Item
n
Why it matters
Prior strata that under-cover
9
ph n=101, dissolved oxygen n=28, peak current n=34, six with n < 10
Copper removal needs a logit link
3 entries
Fraction priors lack one; a general logit link is open
Methane rate not converged
1 stratum
Divergences; the gate checks only r-hat and ESS
No catalog entry for flow rate, growth rate
17 rows
Rows keep camelCase slugs (12 and 5)
Non-numeric slugs reach the normalizer
11,303
Mode, design, substrate are not measurements
Unrecognized units
13,625
% concentrations and mM stay held, outside the pool
Validation split is partial
~2,047 papers
Corpus-wide would hold out 2,924 and need a refit on both
Applied potential, no reference electrode
open
Held until scientists decide (MES-05)
Arm-B extras unlanded; no acquisition scheduler
deferred
Last PDF 2026-09-09; open-access yield ~19%
Derived artifacts not rebuilt by refresh-all
2 files
Open question
Admin lists and facets, uncached
15 queries
Slow first load per request
Known, named and not yet fixed as of 2026-10-26; n is the count each item touches.
07Glossary
Extracted row
One value, unit and source snippet from one paper.
Canonical slug
The snake_case name that groups one quantity across papers, such as power_density.
SI normalization
Converting value and unit to SI; unrecognized units stay held.
Modelable
A row allowed to feed models; it loses the flag if bounds fail.
Bounds gate
A physical-plausibility check that a row fails until judged.
Verifier
A heuristic check on modelable rows.
Catalog link (FK)
The link from a row to the parameter catalog entry for its slug.
Priors v1 and v2
Hierarchical Bayesian priors; v2 is Student-t, per system class, and serves predictions.
Validation role
Per-paper tag on both environments: 1,734 fit, 198 validation, 115 holdout.
Science ratchet
The verify:science list of known failures; new ones block, fixed ones drop off.
Condition set
A paper's group of experimental conditions that ties values together.
Modelable pool
Rows passing the single predicate: 45,095 rows, 163 slugs on staging.
docs/platform/02-corpus-state.md (staging and production funnels of 2026-10-26)
Refresh
scripts/quality/refresh-all.sh, the harmonization and refit sequence
Predicate
libs/data-access/database/src/modelable-pool.ts, the single pool predicate
Measure
pnpm tsx scripts/check-actual-database-stats.ts prints the funnel and ladder for the environment you point it at.
Measured 2026-10-24 to 2026-10-26. Staging ref tzyxbgewzgpangsbhoar, production ref ytgmbbwtawldnunndcnd. Numbers drift as extraction continues; re-measure before quoting any of them.
Part VII of VII · How to use the platform · 12 sections · ~20 min
MESSAI platform · walkthrough by screen
How to use the platform
One section per screen a researcher uses: what it is for, where it lives, the steps to take, and
how to read the numbers it shows. Each public screen has a short silent screen recording, with
the same steps written out beside it.
Last updated 2026-10-27. Recordings made on messai.ai the same day. Routes checked against the
zone route trees on 2026-10-27. Corpus counts change daily and are not quoted here; each screen
prints its own, with a date.
01The screens at a glance
Start from the question you have. Each row names the screen that answers it and who can open it.
Access as the route trees declare it on 2026-10-27. Pages served by the lab zone
(/lab, /predictions) and the web zone share one domain, so every link
in this part opens in place.
02Research listing
The one place to search the microbial-electrochemistry literature held in the corpus: by
keyword, author, DOI or meaning. Each result is a paper record with its abstract and the
parameter values extracted from it.
Open /research and type in the search field. A DOI, an author name or a few
keywords all work.
Pick a search mode: Keyword, Hybrid or Semantic. Semantic matches meaning rather than
words; if the embedding service is offline the page says so and shows keyword results
instead.
Narrow with the filter rail on the left (journal, taxonomy values, data filters). Use Clear
all to start over.
Sort by Best Papers First, Newest, Oldest, Most Cited, Highest Quality or AI
Confidence.
Tick up to three papers and choose Compare, or open one paper for its detail page.
Reading the numbers
“N papers match” counts papers in the corpus, not papers with
extracted values. Many records have a title and abstract only.
Facet counts include every paper matching your text search, not only the
top-ranked results. In semantic mode they reflect your filters only.
Quality is a stored per-paper score from 0 to 100. A paper can have none. It
ranks papers; it does not certify a result.
AI Confidence sorts on a machine-assigned score. Treat it as a hint for what
to read first.
Recorded on messai.ai, 2026-10-27, 20 s, silent.
The Research page opens with a search box, Keyword, Hybrid and Semantic modes, and a
Filters sidebar beside the paper list.
Scrolling shows paper cards with system type, parameter and condition counts, and an
average confidence bar.
Typing "nitrogen" into the search box narrows the list and the Filters counts update to
the matching papers.
Ticking the Microbial Fuel Cell box under System type adds a filter chip and narrows
the list again.
The result line shows the new count of matching papers next to the Sort control.
Counts on the paper list can differ from the paper page for the same paper.
03Paper detail
One paper, with the values extracted from it laid next to the literature. Use it to check a
number before you rely on it. Old links of the form /research/<id> forward
here.
URL/research/paper/<ref>, where the reference is the paper’s
id or short name from the listingAccess public
Steps
Open a paper from the listing. The Overview tab shows the record
and an AI summary.
Open Extracted Data to see each value, its unit and its extraction record.
Open Original PDF and find the value on the page. This is the check that matters; do it for
any number you will quote.
Read the Reported parameters panel: the paper’s value (the marker) sits on the
literature distribution, and values outside the band are flagged as outliers.
Use Chart Explorer, Polarization, Compare and Contradictions to put the paper beside
similar work. Tabs with a count in their name hold that many items.
Reading the numbers
“No values extracted from this paper yet” means extraction has
not produced rows. It is not a statement that the paper reports nothing.
Outlier flag means the value falls outside the literature p10 to p90 band for
that parameter and unit. Outliers are sometimes errors and sometimes the interesting result.
“Sits at X% of pooled literature (n papers)” places the value
inside the population distribution from the fitted priors. Read n first: a position from a
handful of papers is weak.
Trust labels (measured, calibrated, modeled, curated, flagged) say how a
displayed number was produced. Methods defines them.
AI summary and AI Insights are machine-written. The abstract and the PDF are
the record.
Recorded on messai.ai, 2026-10-27, 22.9 s, silent.
From the Research list, Open full page opens the first paper's detail page on its
Overview tab.
The Overview shows an AI summary, What they did, What worked, the abstract and a 3D
Dual-chamber H-cell MFC model.
Selecting the Extracted Data tab lists Methodology, Performance metrics, Operational
parameters and Electrochemical data tables.
Further down, Operating conditions lists the extracted runs with temperature, pH and
substrate.
Hovering a value in the Electrochemical data table highlights its row.
The number of extracted values here can differ from the count on the research list for the
same paper.
04Parameters catalog
Every canonical parameter of a microbial electrochemical system, with its definition, unit,
literature range and how it couples to other parameters. This is where a name such as power
density gets one meaning across papers.
URL/parameters, one page per parameter at /parameters/<slug>Access public
Steps
Open /parameters and search by name, or choose a category. The filter axis can
switch between Category and Subject plus Role.
Sort by Relevance, Name, Category or Unit; set how many results show per page.
Open a parameter for its definition, unit, literature range and the papers its values come
from.
Use the other tabs for the wider view: Correlations, Global Analysis, Parameter Sweep,
Methodology and Diagnostics.
Use the Methodology tab’s glossary when a unit looks unfamiliar; it lists every unit
the corpus accepts and how it is normalised.
Reading the numbers
“N parameters across M categories” counts catalog entries. It
says nothing about how many have data.
Units are the catalog’s canonical units. Values from papers are
converted when the paper’s unit is recognised; rows with an unrecognised unit stay out
of the modelling pool.
Areal and volumetric densities are different parameters. W/m² and
W/m³ are never pooled; compare power only on the same basis.
Literature ranges span many system types and conditions. Filter by system
before reading a range as typical.
Recorded on messai.ai, 2026-10-27, 16.3 s, silent.
The Parameter Catalog opens with a search box, the Catalog, Correlations and Global
Analysis tabs, and a category filter.
Scrolling the table shows each parameter's unit, category, typical value, range,
distribution and variability.
Choosing the Performance category filters the table to that category.
Clicking Ammonia Recovery opens its detail page with a Definition and a Population
prior card.
The Causal section in the side rail shows the parameter's classification and what
affects it.
When recorded, the Electrical filter showed no rows although its count said 45. The
recording uses Performance instead.
05Knowledge graph
A graph of the parameters: evidence, causal structure, correlations and knowledge gaps in one
view. Use it to see what is known to drive a target, and where the literature has little to say.
Open the page. The default is the Graph view with a force layout. Change Layout to DAG for
ranked left-to-right causal order, or to Gap map to put well-studied hubs in the core and
gaps on the rim.
Find a parameter with the search box, or narrow by facets: System, Tier, Data type and
Role. The Evidence filter shows All, Gaps, Studied or Flagged nodes.
Switch edge layers on: Causal (mechanistic), Learned-from-data, Physics laws, Causal
effects (Bayesian) and the Correlation overlay with a minimum |r|.
Click a node or an edge for its card. In the DAG layout, selecting a node also gives a
measured what-if.
Choose PATHS to find the routes between two parameters, or Matrix for a correlation heatmap
over what is in view.
Reading the numbers
n papers on a card is the evidence behind that edge or effect. A
strong-looking link from two papers is weak.
Slope and 95% CI on a causal-effect card come from a within-paper Bayesian
fit. A CI that crosses 0 means the effect is not resolved.
Correlation is not cause. The matrix offers Spearman ρ (rank-based,
recommended for the corpus’s wide log spread) and Pearson r. “Significant
only” keeps pairs with q < 0.05.
Tiers run from Metadata through Inputs, Materials and Latent variables to
Outcomes. The Tiers layout is a layout by tier, not a causal order.
Gaps are parameters with little evidence, not parameters that do not matter.
Recorded on messai.ai, 2026-10-27, 15.2 s, silent.
The MES Knowledge Graph renders as a force-directed network with a legend and a list of
Highest-value knowledge gaps.
Hovering over the dense centre highlights labelled nodes such as temperature and Power
Density.
Clicking in the graph opens a Causal edge drawer on the right with weight, mechanism
and source and target parameters.
The drawer shows an equation-based mechanism and phase strength bars for the selected
link.
Switching the layout to Tiers arranges the nodes into Inputs and drivers, Materials and
Outcomes columns.
The drawer in this recording is for a link between two parameters, not a single node.
06Lab reactor builder
A workbench for designing a reactor: pick a model, edit its parts and operating conditions, and
watch the prediction and the 3D model change together. It is for comparing designs, not for
replaying a paper.
Open /lab and choose a reactor model from the model list. On a phone, use the
Model button. A link with ?model= opens that model directly.
Edit parameters in the Parameters column: geometry, materials, membrane, organism and
operating conditions. Designers for electrode, chamber, membrane and others open as
editors.
Read the prediction as it updates. Each value carries a trust label saying whether it is
calibrated, modeled or curated.
Ask the Assistant, which sits beside Parameters. It proposes changes as cards; nothing
alters the design until you accept a proposal.
Save the workspace. It asks for a name and can copy a link you can share. The Runs tab
lists the runs.
Reading the numbers
The lab predictor is a snapshot, not a full simulation. The build guide gives
about ±25% and calls it fit for design sensitivity, not for absolute performance
claims.
An interval is only as good as its source. A fixed ±25% band is a
placeholder. A calibrated interval comes from the benchmark residuals;
Methods shows which one a predictor ships.
Units matter. Power per electrode area (W/m²) and per reactor volume
(W/m³) differ by orders of magnitude. Compare designs on one basis.
Some system types fall back. PEM, SOFC and PAFC currently use MFC kinetics
with low confidence, per the build guide.
Recorded on messai.ai, 2026-10-27, 16.3 s, silent.
The Lab opens with a reactor model rail, a 3D canvas, a Parameters panel and the
Assistant side by side.
Choosing H-CELL in the model rail loads a detailed dual-chamber MFC in the 3D
canvas.
The Live prediction panel under the canvas shows voltage, current density, power
density and coulombic efficiency.
Dragging the Anode thickness slider changes its value and shows an Optimal range
tooltip.
The Assistant panel stays open beside the parameters with suggested questions and a
message box.
07Predictions
Performance forecasting for a configured system, with a confidence score and multi-objective
optimisation. It is a form-driven companion to the lab: enter a configuration, get a forecast.
URL/predictionsAccess public; saving a prediction needs sign-in
Steps
Read the engine badge at the top first. It says either Served ML model or Illustrative
simulation, and the note under it says what that means.
In Configure System, enter the system and its operating conditions.
Run the prediction and open Prediction Results for the forecast and its confidence.
Use Optimization to trade one objective against another.
Sign in to save a prediction, then use History & Compare to set saved ones side by
side.
Reading the numbers
Illustrative simulation is not the trained model. It is a fast client-side
estimate. For research-grade forecasts with calibrated uncertainty, use the parameter sweep or
the lab.
Served ML model forecasts come from the hierarchical-priors model with
calibrated uncertainty. Its intervals are only as good as the stratum behind them; check n on
Methods.
Confidence scoring is the page’s reliability measure for the forecast.
Read it together with the interval, not instead of it.
Priors are refit as the corpus grows, so the same inputs can return a
different forecast after a refit. Note the date of any forecast you keep.
Recorded on messai.ai, 2026-10-27, 20 s, silent.
The Performance predictions page opens on Configure System and is labelled Illustrative
simulation.
Quick Start Presets offer Research Standard MFC, Educational Microfluidic Cell and
other starting points.
A Live estimate row shows power density, voltage, coulombic efficiency and energy
efficiency as the configuration changes.
Generate AI Prediction opens Prediction Results with Power Density, Coulombic
Efficiency, Energy Efficiency and Overall Confidence cards.
The Prediction Confidence panel shows dashes for training papers, parameter coverage
and uncertainty range, so no interval appears.
This page is labelled Illustrative simulation and shows dashes instead of an interval. For
live ranges, use the lab panel.
Live prediction panel in the lab, at /lab.
Recorded on messai.ai, 2026-10-27, 20 s, silent.
The Lab's Live prediction panel shows a quick estimate for the H-cell model with the
corpus p10 to p90 range under each value.
Voltage, Current density, Power density and Coulombic efficiency each carry a range
line beneath the point value.
Opening Performance and predictions reveals Live, Snapshot, Analyze and More
tabs.
The Analyze tab shows a Sensitivity tornado chart and a Mechanistic loss breakdown at
peak power.
08Reproducibility scorer
A checklist of what a paper must report so that another lab can compare or repeat it. Score a
paper from its DOI, or tick the criteria for your own manuscript.
To score a published paper, paste its DOI under Score a paper. The tool looks it up in the
corpus and scores the parameters already extracted.
To score your own manuscript, go to the interactive scorer and set each criterion to
Reported, Omitted or Missing.
Read the verdict and the list headed “To make this paper reproducible,
report:”. Fix those items first.
For a fuller audit, use the comprehensive 18-parameter view, which weights criteria by
importance.
Use Methodology & equipment to pick your study type and see the protocol and instrument
choices to state.
Reading the numbers
“Missing” means missing from the extracted data, which can be an
extraction miss rather than an omission by the authors. Items marked verify in text need a
human read.
A paper not in the corpus cannot be scored by DOI. Use the interactive
checklist instead.
Verdicts are Fully compliant, Partial compliance or Not yet comparable on the
checklists; reproducible, partial or insufficient on a DOI score.
The five-parameter claim is reported, not reproduced here. The page cites a
result from the ISMET 2026 abstract: among 63 papers, the power-density inter-quartile range
was 278 mW/m² for papers reporting all five, against 487 mW/m² for the rest. It is
retrospective and observational, an association and not an effect. The cohort list and
analysis script are not in the repository, and the verdicts do not rest on it.
The corpus baseline (average reporting completeness across 289 manually
scored papers) is also from that abstract, and the page names it as such.
Recorded on messai.ai, 2026-10-27, 20 s, silent.
The Reproducibility checklist opens with a Paste a DOI box and four sample paper chips
from the corpus.
Clicking the first sample chip fills the DOI box and scores that paper.
The result shows an MFC power generation readiness card marked Insufficient, with
Overall readiness, Conditions and Outcomes bars.
Below the bars, each reporting criterion is marked Reported, Missing or Verify in
text.
Clicking a different sample chip rescores a second paper with different
percentages.
09Collaboration workspaces
A workspace per collaboration. The first is the nitrogen-cycling use case prepared for Dr.
Benjamin Korth at Helmholtz-UFZ: what the corpus holds today, what each pipeline stage will add,
and what the collaboration needs from the partner.
Read the four figures at the top: cohort papers, full-text PDFs, modelable facts and
complete records. Note the measurement date beside them.
Follow section 01 for where the pipeline stands, in order.
In section 02, read the paper and fact funnels, then the breakdown by sub-process. Click
any value for a drawer saying what it counts.
Read “Where the data is soft” before using any count.
Open the source papers to reach corpus pages, PDFs and DOIs.
Reading the numbers
Counts are distinct facts. Duplicate copies from earlier syncs are collapsed
so nothing is counted twice; the page also states how many duplicates the raw rows held.
The page is a snapshot, built from a committed measurement with its date. It
does not read the database live.
Pending is shown as pending. A result that does not exist yet appears as a
labelled gap, never a placeholder number. Complete records read as pending until the stage
that builds them runs.
A paper can count in more than one sub-process row. The rows do not sum to
the cohort.
An amber 0 beside a parameter means none of its facts normalise to SI yet, so
nothing downstream can use it.
Recorded on messai.ai, 2026-10-27, 19.9 s, silent.
The Nitrogen cycling page opens with Cohort papers, Full-text PDFs, Modelable facts and
Complete records tiles.
The Integrity first, then the cohort section lists each pipeline step with a status tag
such as Done, In progress or Needs UFZ.
How a paper gets into the cohort explains the two-test rule with nitrogen topic terms
and bioelectrochemical system terms.
Two bar panels, Papers and Extracted facts, show the funnel from the cohort down to
modelable facts.
Clicking the paper count for Cathodic denitrification opens a side drawer that explains
what the count includes.
This page has no geographic map. It shows funnel panels, the protocol and a count
explanation instead.
10Methods
One page per predictor: the relations and constants in its code, what it leaves out, which
artifacts calibrate its intervals, and the rigor gates over them. Read it before quoting a
prediction.
URL/methods, one page per predictor at /methods/<id>Access public
Steps
Open /methods and pick the predictor for your system. Each shows its physics
family and the systems it covers.
Read What it predicts, Governing relations and Assumptions and constants.
Read Not modelled. These are the effects the predictor ignores.
Read the interval the predictor ships and the calibration artifacts used when it is
served.
Check the benchmark cells and the prior trust table for your parameter and system.
Reading the numbers
n in a benchmark cell is the number of out-of-fold residuals in that stratum,
and papers is how many papers they come from. A cell needs a minimum n to show; below it the
interval is withheld, not guessed.
Coverage (CV) is the cross-validated share of held-out points that fell
inside the band, against the nominal level. Coverage well below nominal means the band is too
narrow.
A fixed ±25% band is a placeholder, not a calibrated interval. Served
predictions replace it with the benchmark band or withhold it.
Prior trust shows, per parameter and system, the state a badge will carry
(measured, calibrated, modeled, curated or flagged) and how many papers the prior rests on.
Rigor gates are the scientific checks run before each commit. Known
violations are listed as baselined; a new one blocks the change.
The same predictor ids appear on every evidence receipt, so a receipt links back to its
method.
Recorded on messai.ai, 2026-10-27, 20 s, silent.
The Methods page lists one predictor per physics family, each with its id and a short
description.
Scrolling shows the MEC, MES, MDC, MNRC, MMRC and MBES predictors.
Opening the MFC predictor shows its governing relations and its assumptions and
constants.
The Interval the predictor ships section states the interval type and the calibration
artifacts used when served.
A benchmark cells table lists targets and strata with their sample sizes, paper counts
and coverage.
11Admin stats
Corpus health tables for the team: catalog statistics, extraction statistics, embedding coverage
and a database audit. This screen is for admins; it is not a public page.
URL/admin/statsAccess admin only. A teammate without an admin login can be given a shared password
instead.
Steps
Sign in with an admin account, or enter the shared password if you were given one. Without
either you will not see the tables.
Read the tiles at the top, then the tables below them.
Open the database audit section. It runs in approximate mode.
Before you quote a figure outside the team, re-measure it with
pnpm tsx scripts/check-actual-database-stats.ts against the environment you
mean.
Reading the numbers
The page is cached for up to an hour, so it can lag a job that just finished.
The audit is approximate by default. An exact audit is a separate admin call
and is slower.
Counts depend on the environment the page is served from. Staging and
production differ; every quoted figure needs its environment and date.
12Onboarding atlas
The page you are reading. It holds the onboarding reference as tabs, so each subject has one
home: the science, the corpus run, the platform map, operators, the symbol library, the October
2026 database overhaul and this walkthrough.
Start at the overview if you have six minutes; it routes you to the part you need and names
a first task.
Choose a part from the tab bar. The side rail lists the sections of the open tab.
Use the search for a term, a unit, a script name or a table. It searches the overview and
every part.
Follow cross-part links; they open the right tab and scroll to the section.
Share a section by copying the address after you click it; the part after the
# reopens the same place.
Reading the numbers
Every count names its database and its date. Re-measure before quoting; the
corpus changes daily.
Where the site and the Markdown docs disagree, the docs win, because they are
refreshed more often. The part that disagrees should be corrected in the same change.
Section numbers are part-local. “Part III · 09” means
section 09 of Part III.
Recorded on messai.ai, 2026-10-27, 22.6 s, silent.
The onboarding atlas opens on Part I with a search box and six part cards from
Onboarding atlas to Database overhaul.
Selecting the Platform map card switches the page to Part III and shows a rail of
section links.
Choosing Data pipeline in the rail jumps to that section with its corpus and extraction
counts.
Choosing Known gaps in the rail jumps to the ranked gap register and roadmap.
Selecting the P&ID symbol library card switches to Part V, drawn with the
platform's symbol renderer.